<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="/feed.xml" rel="self" type="application/atom+xml" /><link href="/" rel="alternate" type="text/html" /><updated>2026-07-08T21:43:47+00:00</updated><id>/feed.xml</id><title type="html">Azure, AI &amp;amp; DevOps Leadership</title><subtitle>Professional insights on Azure cloud architecture, AI implementation,  data engineering, and DevOps practices from an enterprise solution architect.</subtitle><author><name>Okko Oulasvirta</name></author><entry><title type="html">Building a Domain-Driven Data Mesh on Microsoft Fabric</title><link href="/data/2026/05/26/domain-driven-data-mesh-on-microsoft-fabric.html" rel="alternate" type="text/html" title="Building a Domain-Driven Data Mesh on Microsoft Fabric" /><published>2026-05-26T00:00:00+00:00</published><updated>2026-05-26T00:00:00+00:00</updated><id>/data/2026/05/26/domain-driven-data-mesh-on-microsoft-fabric</id><content type="html" xml:base="/data/2026/05/26/domain-driven-data-mesh-on-microsoft-fabric.html"><![CDATA[<h2 id="introduction">Introduction</h2>

<p>Microsoft Fabric is an attractive platform for industrial organizations that want to bring data engineering, lakehouse architecture, real-time analytics, reporting, and AI readiness closer together.</p>

<p>The technology story is compelling: OneLake, Lakehouse, Warehouse, Data Pipelines, Eventstream, Eventhouse, Power BI, Git integration, deployment pipelines, and the broader Microsoft data and AI ecosystem create a strong foundation for modern analytics delivery.</p>

<p>But in practice, the hard part is not only adopting Fabric.</p>

<p>The harder question is how multiple business domains, development teams, data products, CI/CD pipelines, governance rules, support models, and business owners can work on the same platform without fragmenting into local implementations.</p>

<p>This post is a retrospective on a pragmatic, domain-driven data mesh model built around Microsoft Fabric and Azure DevOps. The key lesson is simple:</p>

<blockquote>
  <p>Fabric provides the shared technical platform. The development framework determines whether the platform scales.</p>
</blockquote>

<h2 id="the-original-business-drivers">The Original Business Drivers</h2>

<p>The platform journey was not driven by technology modernization alone. The original business drivers were practical and measurable:</p>

<ul>
  <li>faster delivery of reporting and analytics solutions</li>
  <li>clearer ownership of data across business domains</li>
  <li>migration away from legacy reporting and data platform solutions</li>
  <li>a healthier foundation for future AI use cases</li>
  <li>better reuse of curated data products across the organization</li>
</ul>

<p>In many enterprises, analytics delivery starts as a sequence of point solutions. A team needs a report, an integration, a dataset, or a dashboard. The immediate problem is solved, but the organization often ends up with duplicated transformations, unclear ownership, inconsistent quality, and reporting logic scattered across systems.</p>

<p>A domain-driven platform model changes the question.</p>

<p>Instead of asking only:</p>

<blockquote>
  <p>How do we deliver this reporting need?</p>
</blockquote>

<p>The organization starts asking:</p>

<blockquote>
  <p>Is this also a reusable data product that could serve other parts of the business?</p>
</blockquote>

<p>That shift matters. It connects individual analytics demand to a broader data product portfolio.</p>

<p>As the platform model matures, improvements become visible across several dimensions:</p>

<table>
  <thead>
    <tr>
      <th>Business driver</th>
      <th>Before</th>
      <th>After the platform model matures</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Reporting and analytics delivery</td>
      <td>Each new solution planned and built from scratch</td>
      <td>Standard workspace, CI/CD and medallion patterns make delivery repeatable</td>
    </tr>
    <tr>
      <td>Data product onboarding</td>
      <td>Ownership, documentation and development path clarified case by case</td>
      <td>Data product definition becomes part of the project stage-gate process</td>
    </tr>
    <tr>
      <td>AI use case preparation</td>
      <td>Data discovery, quality checks and ownership clarified separately for each AI initiative</td>
      <td>AI initiatives can start from governed, documented gold-layer data products</td>
    </tr>
    <tr>
      <td>Domain ownership</td>
      <td>Technical ownership clearer than business ownership</td>
      <td>Domain-owned data products with clearer links to business owners and consumers</td>
    </tr>
  </tbody>
</table>

<p>The specific improvement depends on the organization and its maturity. The point is that a shared framework turns platform work into repeatable business capability.</p>

<h2 id="a-pragmatic-data-mesh-on-microsoft-fabric">A Pragmatic Data Mesh on Microsoft Fabric</h2>

<p>The model can be described as a pragmatic data mesh implementation on Microsoft Fabric.</p>

<p>Business domains own their data products, backlogs, development priorities, and release decisions. A central platform team provides the shared Fabric foundation, Azure DevOps framework, CI/CD patterns, governance guardrails, documentation model, and support structure.</p>

<p>This is not data mesh as a slideware concept. It is a practical operating model with concrete engineering mechanisms:</p>

<ul>
  <li>domain-owned Fabric workspaces and data products</li>
  <li>shared medallion architecture across domains</li>
  <li>Azure DevOps as the delivery coordination layer</li>
  <li>a monorepo for transparency and shared development patterns</li>
  <li>domain-specific Azure Pipelines with common deployment logic</li>
  <li>automated validation rules for governance controls</li>
  <li>a data product portal for discovery and consumption</li>
  <li>architecture and developer forums for cross-domain alignment</li>
</ul>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Domain-Driven Data Mesh on Microsoft Fabric
├── Platform Team (central)
│   ├── Fabric Foundation &amp; Governance
│   ├── Azure DevOps Framework
│   ├── CI/CD Templates &amp; Shared Pipelines
│   ├── Documentation Model &amp; Operating Practices
│   └── Support Structure &amp; Architecture Forums
│
├── Domain: Manufacturing
│   ├── Domain-owned Workspaces (Dev / Test / Prod)
│   ├── Medallion Layers (Bronze → Silver → Gold)
│   ├── Data Products &amp; Backlogs
│   └── Domain-specific Pipeline &amp; Approvals
│
├── Domain: Finance
│   ├── Domain-owned Workspaces (Dev / Test / Prod)
│   ├── Medallion Layers (Bronze → Silver → Gold)
│   ├── Data Products &amp; Backlogs
│   └── Domain-specific Pipeline &amp; Approvals
│
├── Domain: Sales
│   └── ...
│
└── Consumers
    ├── Reports &amp; Dashboards (Power BI)
    ├── AI / Copilots / Agents
    └── Custom Applications
</code></pre></div></div>

<p>The important balance is between autonomy and standardization.</p>

<p>Domains need enough autonomy to deliver business value. The platform team needs enough standardization to keep the overall platform understandable, secure, supportable, and scalable.</p>

<h2 id="fabric-as-the-strategic-platform">Fabric as the Strategic Platform</h2>

<p>Choosing Microsoft Fabric early was strategically important, but it was not always easy.</p>

<p>Fabric was still maturing while implementation work was already underway. Some capabilities were evolving, and teams had to adapt as the product improved. This created friction, especially in the early phases.</p>

<p>However, the strategic value came from committing to a unified Microsoft data platform direction. Fabric provided a common target for lakehouse development, warehouse modeling, Power BI reporting, real-time analytics, and future AI capabilities.</p>

<p>Just as importantly, close collaboration with Microsoft field and product teams helped the implementation teams understand the platform direction, provide feedback, and navigate early maturity gaps.</p>

<p>In hindsight, the lesson was not that early adoption is painless. It is that early adoption can be valuable when the strategic platform direction is clear and the feedback loop with the vendor is strong.</p>

<h2 id="medallion-architecture-as-a-shared-domain-pattern">Medallion Architecture as a Shared Domain Pattern</h2>

<p>The medallion architecture became one of the most important shared patterns.</p>

<p>The bronze, silver, and gold layers created a common language for data maturity:</p>

<ul>
  <li><strong>Bronze</strong> keeps data close to the original source structure.</li>
  <li><strong>Silver</strong> standardizes, cleanses, enriches, and prepares data for broader use.</li>
  <li><strong>Gold</strong> exposes curated, business-ready data products for analytics, reporting, applications, and AI use cases.</li>
</ul>

<p>The key was not only the technical layering. The key was repeating the same pattern from domain to domain.</p>

<p>Manufacturing, supply chain, finance, sales, service, product data, and industrial IoT or OT domains may have very different source systems and business semantics. But if each domain uses the same high-level development model, the platform becomes easier to operate.</p>

<p>A consistent medallion framework helps:</p>

<ul>
  <li>domain developers understand where different types of logic belong</li>
  <li>platform teams provide reusable templates and guidance</li>
  <li>support teams troubleshoot similar patterns across solutions</li>
  <li>architects reason about dependencies and ownership</li>
  <li>business consumers understand which layer is intended for consumption</li>
</ul>

<p>A single domain can always build a working solution in its own way. The challenge is scaling the model across many domains. That is where the shared medallion framework becomes valuable.</p>

<pre><code class="language-mermaid">flowchart LR
    subgraph Sources
        S1[ERP]
        S2[CRM]
        S3[IoT / OT]
        S4[Files &amp; APIs]
    end

    subgraph Bronze["Bronze — Raw"]
        B1[Source-aligned tables]
        B2[Minimal transformation]
    end

    subgraph Silver["Silver — Enriched"]
        SV1[Cleansed &amp; standardized]
        SV2[Joined &amp; deduplicated]
    end

    subgraph Gold["Gold — Data Products"]
        G1[Business-ready datasets]
        G2[Governed &amp; documented]
    end

    subgraph Consumers
        C1[Power BI Reports]
        C2[AI &amp; Copilots]
        C3[Applications]
    end

    S1 &amp; S2 &amp; S3 &amp; S4 --&gt; B1 &amp; B2
    B1 &amp; B2 --&gt; SV1 &amp; SV2
    SV1 &amp; SV2 --&gt; G1 &amp; G2
    G1 &amp; G2 --&gt; C1 &amp; C2 &amp; C3
</code></pre>

<h2 id="the-gold-layer-as-an-ai-ready-data-product-layer">The Gold Layer as an AI-Ready Data Product Layer</h2>

<p>The gold layer should not be seen only as the last step before reporting.</p>

<p>In an AI-first world, gold-layer data products become a much more important foundation. AI solutions, copilots, agents, and custom applications are only as useful as the data foundation behind them.</p>

<p>If AI initiatives connect directly to fragmented source systems, each use case must separately solve data discovery, ownership, quality, semantics, access, and integration. That is slow and fragile.</p>

<p>When data is curated into domain-owned gold-layer data products, the starting point is healthier:</p>

<ul>
  <li>the data has a business owner</li>
  <li>the semantics are closer to how the business operates</li>
  <li>the data product can be documented and discovered</li>
  <li>quality and contract expectations can be defined</li>
  <li>access can be governed</li>
  <li>the same product can serve reporting, analytics, applications, and AI use cases</li>
</ul>

<p>In this sense, the gold layer becomes a business-ready data product layer, not merely a reporting layer.</p>

<h2 id="azure-devops-as-the-delivery-operating-model">Azure DevOps as the Delivery Operating Model</h2>

<p>Azure DevOps became the strategic coordination layer for the whole development model.</p>

<p>Azure Boards made work visible. Azure Repos provided version control. Azure Pipelines handled validation, CI/CD and deployment. Azure DevOps Wiki became the home for documentation, architecture decisions, and shared operating practices.</p>

<p>This matters because multi-domain Fabric development is not only a technical platform problem. It is also a coordination problem.</p>

<p>Without an integrated delivery model, each domain can easily create its own backlog conventions, repository structure, release process, approval flow, documentation style, and definition of done.</p>

<p>Azure DevOps helped bring these together into one operating model:</p>

<ul>
  <li>work management</li>
  <li>source control</li>
  <li>pull request validation</li>
  <li>deployment orchestration</li>
  <li>release approvals</li>
  <li>documentation</li>
  <li>architecture decision tracking</li>
  <li>portfolio visibility</li>
</ul>

<p>In this model, Azure DevOps is not just a project management tool. It is part of the data platform architecture.</p>

<h2 id="monorepo-for-transparency-and-cross-domain-coordination">Monorepo for Transparency and Cross-Domain Coordination</h2>

<p>The monorepo model improved transparency across domains.</p>

<p>All development was visible in one source control structure, while each domain still had its own folders, pipelines, and approval flows. The monorepo did not mean that one central team owned all development. It meant that everyone worked inside a shared technical framework.</p>

<p>This created several benefits:</p>

<ul>
  <li>shared templates and deployment logic were easier to reuse</li>
  <li>cross-domain changes were easier to review</li>
  <li>platform-wide improvements could be introduced consistently</li>
  <li>dependencies were more visible</li>
  <li>support teams could learn one structure instead of many unrelated repositories</li>
</ul>

<p>The monorepo was especially valuable when changes required coordinated releases across domains. Related changes could be reviewed, validated, and released as one controlled change set rather than as disconnected domain-specific deployments.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>fabric-platform/                          (monorepo root)
├── domains/
│   ├── manufacturing/
│   │   ├── lakehouse/
│   │   ├── warehouse/
│   │   ├── pipelines/
│   │   └── notebooks/
│   ├── finance/
│   │   ├── lakehouse/
│   │   ├── warehouse/
│   │   ├── pipelines/
│   │   └── notebooks/
│   └── sales/
│       └── ...
├── shared/
│   ├── templates/                        (reusable pipeline templates)
│   ├── validation/                       (shared quality checks)
│   └── governance/                       (policy-as-code rules)
├── pipelines/
│   ├── manufacturing-ci.yml
│   ├── finance-ci.yml
│   └── platform-shared.yml
└── docs/
    ├── architecture-decisions/
    └── onboarding/
</code></pre></div></div>

<h2 id="domain-specific-pipelines-with-shared-deployment-logic">Domain-Specific Pipelines with Shared Deployment Logic</h2>

<p>One of the most important design decisions was to give each domain its own pipeline and approval flow while keeping the underlying pipeline structure consistent.</p>

<p>This preserved domain ownership without losing platform control.</p>

<p>Each domain could own its own release decision. At the same time, all domains used common Azure Pipelines patterns, shared templates, common validation logic, and consistent deployment principles.</p>

<p>This model separated two concerns:</p>

<ul>
  <li>the platform defines how releases are done safely</li>
  <li>the domain decides when its own solution is ready to be released</li>
</ul>

<p>Azure Pipelines and Fabric CI/CD tooling formed the core of this model. Fabric development became more repeatable when deployment, validation, and environment promotion were handled through common automation rather than ad hoc manual steps.</p>

<pre><code class="language-mermaid">flowchart TD
    PR["Pull Request\n(domain developer)"] --&gt; VAL["Shared Validation\n(lint, schema, policy checks)"]
    VAL --&gt; REV["Domain Code Review\n&amp; Approval"]
    REV --&gt; DEV["Deploy to Dev Workspace\n(automatic)"]
    DEV --&gt; TEST["Promote to Test Workspace\n(domain approval gate)"]
    TEST --&gt; PROD["Promote to Prod Workspace\n(domain + platform approval)"]

    style VAL fill:#e0f0ff,stroke:#336
    style DEV fill:#e6ffe6,stroke:#363
    style TEST fill:#fff5e6,stroke:#663
    style PROD fill:#ffe6e6,stroke:#633
</code></pre>

<h2 id="gold-layer-development-with-dbt-cloud">Gold-Layer Development with dbt Cloud</h2>

<p>dbt Cloud was selected for gold-layer transformation development because it supports analytics engineering practices: SQL-based transformations, dependencies between models, testing, documentation, and maintainable transformation logic.</p>

<p>However, tooling decisions have architectural consequences.</p>

<p>In a domain-driven Fabric model built around a monorepo, dbt Cloud introduced a repository strategy trade-off. dbt Cloud works best with its own repository structure, which means each domain solution received a dedicated dbt repository rather than being part of the Fabric monorepo.</p>

<p>The branching model followed Fabric workspace conventions: each development stage and Fabric workspace mapped to a development branch in the dbt repository. This kept dbt releases aligned with the overall Fabric deployment lifecycle while giving dbt projects the repository structure they require.</p>

<p>This is a good example of a broader lesson: tool choices are not only tool choices. They affect ownership, repository strategy, release management, governance, and supportability. The dbt decision was the right one for gold-layer development quality, but it required accepting that not all Fabric development could live in a single monorepo.</p>

<h2 id="data-product-portal-and-discovery">Data Product Portal and Discovery</h2>

<p>A domain-driven data mesh needs discovery.</p>

<p>Data products should not remain hidden inside workspaces, reports, or technical documentation. Business users, developers, analysts, and future AI initiatives need a way to find what data products exist, who owns them, what they mean, and how they can be consumed.</p>

<p>A custom data product portal can serve this role when it is aligned with the organization’s operating model.</p>

<p>The portal can expose:</p>

<ul>
  <li>data product descriptions</li>
  <li>domain ownership</li>
  <li>business purpose</li>
  <li>consumer guidance</li>
  <li>documentation links</li>
  <li>access request paths</li>
  <li>lifecycle status</li>
  <li>quality or contract information</li>
</ul>

<p>Microsoft Purview, OneLake Catalog, and other Microsoft governance capabilities may also become relevant as they mature. But the key architectural point is independent of the specific catalog technology: data products must be discoverable and consumable, not only technically deployed.</p>

<h2 id="governance-as-rules-validation-and-automation">Governance as Rules, Validation and Automation</h2>

<p>Fabric does not provide an Azure Policy equivalent for every platform governance need. That means governance must be made explicit in the development framework.</p>

<p>A useful pattern is to describe governance rules as testable rules and then implement validation automation around them.</p>

<p>Examples include validation for:</p>

<ul>
  <li>naming standards</li>
  <li>repository structure</li>
  <li>required documentation</li>
  <li>data product metadata</li>
  <li>workspace configuration</li>
  <li>environment consistency</li>
  <li>security and access patterns</li>
  <li>deployment readiness</li>
  <li>data contract expectations</li>
</ul>

<p>Azure Pipelines can then enforce these rules in two complementary ways:</p>

<ol>
  <li>scheduled validation runs across the platform</li>
  <li>pull request and release validations for every code change</li>
</ol>

<p>The same validation logic should be reused in both places. This prevents governance from becoming only a wiki page. It becomes part of the daily developer workflow.</p>

<h2 id="what-changed-for-domains">What Changed for Domains</h2>

<p>As the model matured, domains could work more independently inside a shared framework.</p>

<p>The change was not only technical. It was also organizational.</p>

<p>Before the framework matured, the platform team was often involved in many implementation details: environments, pipelines, access, documentation patterns, deployment questions, and troubleshooting.</p>

<p>Over time, the platform team’s role started to shift from hands-on dependency toward enablement, governance, and facilitation.</p>

<p>This was one of the hardest changes. Reducing platform team dependency does not mean removing the platform team from the equation. It means moving the platform team toward the role of framework owner, guardrail provider, and platform enabler.</p>

<p>Another important change was the movement from technical domain ownership toward business data product ownership. A data product is not mature if it only has a technical owner. It also needs a business purpose, consumers, ownership, and decision-making accountability.</p>

<h2 id="communication-is-part-of-the-architecture">Communication Is Part of the Architecture</h2>

<p>Domain-driven development does not remove the need for coordination. It increases the need for the right kind of coordination.</p>

<p>Several forums became important:</p>

<ul>
  <li>regular architecture forums across domains</li>
  <li>developer forums across teams and vendors</li>
  <li>shared communication channels</li>
  <li>a core team connecting business initiatives, projects, and platform capabilities</li>
</ul>

<p>One practical lesson was that private troubleshooting does not scale on a shared platform.</p>

<p>If deployment problems, design questions, or platform issues are solved only in private channels, other domains do not learn from them. The same problem may be solved multiple times. Decisions are not visible. Platform improvements are harder to identify.</p>

<p>The platform team therefore had to treat communication as part of the architecture. Problems, patterns, and decisions needed to be visible across domains, not only inside the team that first encountered them.</p>

<h2 id="what-worked-well">What Worked Well</h2>

<p>The most successful architectural decisions were not isolated technology choices.</p>

<p>Fabric provided the strategic platform direction. Azure DevOps provided the delivery operating model. The monorepo improved transparency. Domain-specific pipelines preserved autonomy without sacrificing standardization. Medallion architecture provided a shared data engineering model. The data product portal made data products more visible.</p>

<p>The domain-driven data mesh model worked because it was supported by concrete engineering practices:</p>

<ul>
  <li>common templates</li>
  <li>shared deployment logic</li>
  <li>standard validation patterns</li>
  <li>architecture forums</li>
  <li>developer communities</li>
  <li>consistent approval flows</li>
  <li>documented governance rules</li>
  <li>automated checks</li>
</ul>

<p>Without those mechanisms, data mesh would have remained an abstract organizational idea.</p>

<h2 id="business-value-beyond-technical-modernization">Business Value Beyond Technical Modernization</h2>

<p>The biggest business benefit was not simply that the organization adopted Microsoft Fabric.</p>

<p>The real value came from combining Fabric, Azure DevOps, CI/CD, medallion architecture, domain ownership, and data product thinking into one repeatable operating model.</p>

<p>This created value in several ways:</p>

<ul>
  <li>reporting and analytics delivery became more repeatable</li>
  <li>domains gained clearer ownership of their data products</li>
  <li>legacy reporting and data solutions could be migrated toward a modern platform</li>
  <li>curated data products became reusable across the organization</li>
  <li>AI initiatives gained a healthier data foundation through governed gold-layer data products</li>
  <li>support and development practices became more consistent</li>
</ul>

<h2 id="what-i-would-do-differently">What I Would Do Differently</h2>

<p>If starting again, I would treat the development framework as a first-class platform capability from day one.</p>

<p>That means introducing the monorepo model and standardized Azure Pipelines release patterns early. In a multi-domain Fabric environment, consistency in source control, validation, and deployment patterns is not an implementation detail. It is the foundation for scaling development across teams.</p>

<p>I would also make data product thinking part of the stage-gate decision process before projects start.</p>

<p>Every new analytics or reporting request should be evaluated not only as a local solution need, but also as a potential reusable data product for the wider organization.</p>

<p>Finally, I would establish cross-domain developer forums and shared communication channels as early as possible. In a multi-vendor or multi-team environment, the communication model is part of the architecture. If issues are solved only in private channels, the platform does not learn.</p>

<h2 id="where-this-could-go-next">Where This Could Go Next</h2>

<p>The next phase should not be defined only by data engineering needs.</p>

<p>As Microsoft continues to evolve Fabric, AI platform capabilities, governance services, and application development services, the more interesting question is how domain-owned data products can become building blocks for AI-enabled business applications.</p>

<p>Several topics deserve deeper exploration in their own dedicated posts:</p>

<ul>
  <li>data product lifecycle management and contract-driven development</li>
  <li>computational governance through validation automation</li>
  <li>cross-domain lineage and relationship intelligence</li>
  <li>self-service onboarding for new domains</li>
  <li>AI-ready data products and how gold-layer data can serve copilots, agents, and custom applications</li>
  <li>Backend-as-a-Service patterns for building custom applications on governed data products</li>
</ul>

<p>Each of these is a substantial topic that benefits from focused treatment rather than a summary here.</p>

<h2 id="conclusion">Conclusion</h2>

<p>A Microsoft Fabric-based data platform can start as a technology modernization effort. But it becomes truly valuable when it evolves into a domain-driven operating model.</p>

<p>Fabric provides the shared technical foundation. Azure DevOps makes development visible and governable. Medallion architecture makes data refinement repeatable. Domain ownership brings responsibility closer to the business. Governance automation keeps the model under control. Gold-layer data products make the platform valuable for reporting, analytics, AI, and future applications.</p>

<p>The lesson is not simply to adopt Fabric.</p>

<p>The lesson is to build a framework around it: a domain-driven data mesh model where multiple teams can create governed, reusable, AI-ready data products on a shared platform without losing autonomy or control.</p>

<h2 id="references">References</h2>

<ul>
  <li><a href="https://learn.microsoft.com/en-us/fabric/get-started/microsoft-fabric-overview">What is Microsoft Fabric?</a></li>
  <li><a href="https://learn.microsoft.com/en-us/fabric/data-engineering/lakehouse-overview">What is a lakehouse in Microsoft Fabric?</a></li>
  <li><a href="https://learn.microsoft.com/en-us/fabric/onelake/onelake-medallion-lakehouse-architecture">Medallion lakehouse architecture in Microsoft Fabric</a></li>
  <li><a href="https://learn.microsoft.com/en-us/fabric/governance/domains">Fabric domains</a></li>
  <li><a href="https://learn.microsoft.com/en-us/fabric/governance/governance-compliance-overview">Governance overview and guidance</a></li>
  <li><a href="https://learn.microsoft.com/en-us/fabric/cicd/git-integration/intro-to-git-integration">Git integration in Microsoft Fabric</a></li>
  <li><a href="https://learn.microsoft.com/en-us/fabric/cicd/deployment-pipelines/intro-to-deployment-pipelines">Introduction to deployment pipelines</a></li>
  <li><a href="https://learn.microsoft.com/en-us/azure/devops/pipelines/get-started/what-is-azure-pipelines">What is Azure Pipelines?</a></li>
</ul>]]></content><author><name>Okko Oulasvirta</name></author><category term="data" /><category term="microsoft-fabric" /><category term="data-mesh" /><category term="azure-devops" /><category term="data-products" /><category term="ci-cd" /><category term="platform-engineering" /><category term="medallion-architecture" /><category term="ai-readiness" /><summary type="html"><![CDATA[A retrospective on building a domain-driven, Microsoft Fabric-based data mesh model with Azure DevOps, medallion architecture, CI/CD, data products and AI-ready gold layers.]]></summary></entry><entry><title type="html">Create and Publish a Simple Blog Post with GitHub Mobile</title><link href="/devops/2026/05/14/create-and-publish-a-simple-blog-post-with-github-mobile.html" rel="alternate" type="text/html" title="Create and Publish a Simple Blog Post with GitHub Mobile" /><published>2026-05-14T00:00:00+00:00</published><updated>2026-05-14T00:00:00+00:00</updated><id>/devops/2026/05/14/create-and-publish-a-simple-blog-post-with-github-mobile</id><content type="html" xml:base="/devops/2026/05/14/create-and-publish-a-simple-blog-post-with-github-mobile.html"><![CDATA[<h2 id="introduction">Introduction</h2>

<p>Sometimes you just need to publish a short blog post quickly without opening a laptop.<br />
GitHub Mobile makes this possible by letting you edit files, commit changes, and push directly to your repository from your phone.</p>

<p>In this post, I’ll show a simple workflow for creating and publishing a Markdown blog post to a GitHub Pages/Jekyll site using only the GitHub Mobile app.</p>

<h2 id="prerequisites">Prerequisites</h2>

<ul>
  <li>GitHub Mobile installed (iOS or Android)</li>
  <li>Access to your blog repository</li>
  <li>A Jekyll-style blog setup where posts are stored in <code class="language-plaintext highlighter-rouge">_posts/</code></li>
  <li>Permission to commit to your default branch (or create a pull request)</li>
</ul>

<h2 id="step-1-open-the-repository-in-github-mobile">Step 1: Open the Repository in GitHub Mobile</h2>

<ol>
  <li>Open <strong>GitHub Mobile</strong>.</li>
  <li>Navigate to your blog repository.</li>
  <li>Open the <code class="language-plaintext highlighter-rouge">_posts</code> folder (and the category folder if your blog uses one, for example <code class="language-plaintext highlighter-rouge">_posts/devops</code>).</li>
</ol>

<h2 id="step-2-create-a-new-post-file">Step 2: Create a New Post File</h2>

<ol>
  <li>Tap <strong>+</strong> (or file actions) and create a new file.</li>
  <li>Name the file using Jekyll naming format:</li>
</ol>

<p><code class="language-plaintext highlighter-rouge">YYYY-MM-DD-title.md</code></p>

<p>Example:</p>

<p><code class="language-plaintext highlighter-rouge">2026-05-14-my-mobile-post.md</code></p>

<h2 id="step-3-add-front-matter">Step 3: Add Front Matter</h2>

<p>Add YAML front matter at the top of the file:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nn">---</span>
<span class="na">layout</span><span class="pi">:</span> <span class="s">single</span>
<span class="na">title</span><span class="pi">:</span> <span class="s2">"</span><span class="s">My</span><span class="nv"> </span><span class="s">Mobile</span><span class="nv"> </span><span class="s">Post"</span>
<span class="na">date</span><span class="pi">:</span> <span class="s">2026-05-14</span>
<span class="na">categories</span><span class="pi">:</span>
<span class="pi">-</span> <span class="s">devops</span>
<span class="na">tags</span><span class="pi">:</span>
<span class="pi">-</span> <span class="s">github</span>
<span class="pi">-</span> <span class="s">mobile</span>
<span class="nn">---</span>
</code></pre></div></div>

<p>Then write your post content below it in Markdown.</p>

<h2 id="step-4-write-the-post-content">Step 4: Write the Post Content</h2>

<p>Keep it simple:</p>

<ul>
  <li>Add a short introduction</li>
  <li>Add 2–3 key points</li>
  <li>End with a short conclusion</li>
</ul>

<p>Because you are on mobile, short sections and clear headings work best.</p>

<h2 id="step-5-commit-and-push-from-mobile">Step 5: Commit and Push from Mobile</h2>

<ol>
  <li>Review your changes in the file editor.</li>
  <li>Tap <strong>Commit changes</strong>.</li>
  <li>Write a clear commit message, for example:</li>
</ol>

<p><code class="language-plaintext highlighter-rouge">Add post: My Mobile Post</code></p>

<ol>
  <li>Commit directly to the target branch or create a new branch and open a pull request.</li>
</ol>

<h2 id="step-6-publish">Step 6: Publish</h2>

<p>If your site is configured with GitHub Pages, publishing happens automatically after the commit is merged to the publishing branch.</p>

<p>To verify:</p>

<ul>
  <li>Open your blog URL</li>
  <li>Confirm the new post appears on the home page or category page</li>
  <li>Open the post and check formatting</li>
</ul>

<h2 id="tips-for-a-better-mobile-workflow">Tips for a Better Mobile Workflow</h2>

<ul>
  <li>Use a reusable front matter template in Notes for quick copy/paste</li>
  <li>Keep post titles short to avoid filename mistakes</li>
  <li>Make one post per commit for easy rollback</li>
  <li>If possible, use pull requests for review before publishing</li>
</ul>

<h2 id="conclusion">Conclusion</h2>

<p>GitHub Mobile is a practical option for lightweight publishing tasks.<br />
For short updates and quick posts, you can create, commit, and publish directly from your phone in just a few minutes.</p>]]></content><author><name>Okko Oulasvirta</name></author><category term="devops" /><category term="github" /><category term="github-mobile" /><category term="blogging" /><category term="jekyll" /><category term="markdown" /><summary type="html"><![CDATA[A quick guide to creating a simple Markdown blog post directly from your phone using GitHub Mobile and publishing it via GitHub Pages.]]></summary></entry><entry><title type="html">From Data Lineage to Relationship Intelligence in Manufacturing Data Platforms</title><link href="/data/2026/05/02/from-data-lineage-to-relationship-intelligence.html" rel="alternate" type="text/html" title="From Data Lineage to Relationship Intelligence in Manufacturing Data Platforms" /><published>2026-05-02T00:00:00+00:00</published><updated>2026-05-02T00:00:00+00:00</updated><id>/data/2026/05/02/from-data-lineage-to-relationship-intelligence</id><content type="html" xml:base="/data/2026/05/02/from-data-lineage-to-relationship-intelligence.html"><![CDATA[<h2 id="introduction">Introduction</h2>

<p>Modern data platforms are usually discussed through their technical building blocks: lakehouses, warehouses, pipelines, notebooks, semantic models, reports, catalogs, governance tools, and increasingly AI assistants.</p>

<p>Those building blocks matter. But in a large manufacturing company, the most interesting questions are often not about individual assets. They are about relationships.</p>

<ul>
  <li>Where does this KPI come from?</li>
  <li>Which data products are used by this business process?</li>
  <li>Who owns the data behind this report?</li>
  <li>What changes if this source system, semantic model, or data product changes?</li>
  <li>Which customers, factories, machines, components, service events, or spare parts are connected through the data?</li>
  <li>Can an AI assistant explain not only an answer, but also the data context behind the answer?</li>
</ul>

<p>This post is a thinking-out-loud exploration of a spike I would run on top of a modern Microsoft Fabric-based data platform. The goal is not to declare a final architecture. The goal is to ask better questions before building another metadata solution.</p>

<h2 id="the-starting-point-lineage-is-useful-but-not-enough">The Starting Point: Lineage Is Useful, but Not Enough</h2>

<p>Data lineage is usually understood as the traceability of data: where data comes from, how it is transformed, and where it is consumed.</p>

<p>A simplified lineage path might look like this:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Source system
  -&gt; Data pipeline
    -&gt; Lakehouse table
      -&gt; Warehouse table
        -&gt; Semantic model
          -&gt; Power BI report
</code></pre></div></div>

<p>This is valuable. It helps with troubleshooting, impact analysis, governance, and trust.</p>

<p>But manufacturing data platforms need more than technical lineage diagrams. The business rarely asks only “which table feeds which report?” More often, the business asks questions like:</p>

<ul>
  <li>Which process depends on this data?</li>
  <li>Which KPI will be affected?</li>
  <li>Which factory or customer is impacted?</li>
  <li>Who should be informed?</li>
  <li>Is this data product reliable enough for operational or AI use?</li>
</ul>

<p>That requires a broader view.</p>

<h2 id="from-lineage-to-relationship-intelligence">From Lineage to Relationship Intelligence</h2>

<p>The next useful layer on top of a modern data platform may not be another database or another catalog. It may be relationship intelligence.</p>

<p>By relationship intelligence, I mean the ability to connect technical data flows with business context:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Technical lineage
  + Data product contracts
  + Catalog metadata
  + Data portal content
  + Ownership and support responsibilities
  + Usage metrics
  + Business process and KPI context
  + Governance metadata
  + AI-readable context
= Relationship intelligence
</code></pre></div></div>

<p>This is not just a nicer diagram. It is a decision-support capability.</p>

<p>A data catalog tells people what exists. A data portal helps people find and request data products. Data product contracts define expectations. Lineage shows technical dependencies. Governance tools help classify and control data. AI assistants can help users ask questions.</p>

<p>The real opportunity is to connect these pieces.</p>

<h2 id="why-manufacturing-makes-this-interesting">Why Manufacturing Makes This Interesting</h2>

<p>Manufacturing is full of relationships.</p>

<p>A customer may have several sites. A site may contain production lines. A line may contain machines. A machine may contain components. Components may be connected to spare parts, service events, suppliers, maintenance plans, telemetry, and operational KPIs.</p>

<p>Another relationship chain could look like this:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Supplier
  -&gt; Component
    -&gt; Product
      -&gt; Factory
        -&gt; Customer
</code></pre></div></div>

<p>Or this:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Customer
  -&gt; Site
    -&gt; Machine
      -&gt; Component
        -&gt; Service event
          -&gt; Spare part
</code></pre></div></div>

<p>In this environment, data platform metadata is not only an IT concern. It can become a way to understand business impact, operational risk, and AI-readiness.</p>

<h2 id="microsoft-fabric-as-the-strategic-platform-context">Microsoft Fabric as the Strategic Platform Context</h2>

<p>If Microsoft Fabric is the strategic data platform, the first principle should be simple:</p>

<blockquote>
  <p>Test the native platform capabilities before adding a separate relationship or graph technology.</p>
</blockquote>

<p>The initial candidate capabilities would include:</p>

<ul>
  <li>Microsoft Fabric lineage views</li>
  <li>Semantic model impact analysis</li>
  <li>OneLake Catalog</li>
  <li>Microsoft Purview integration</li>
  <li>Fabric REST APIs</li>
  <li>Fabric Data Agent</li>
  <li>Fabric Graph preview</li>
  <li>Fabric IQ and ontology-related preview capabilities</li>
</ul>

<p>Some of these are mature platform capabilities. Some are still preview capabilities. The point of the spike is not to assume they solve everything. The point is to find out how far the strategic platform already takes us.</p>

<h2 id="the-spike-should-start-with-roles-not-tools">The Spike Should Start with Roles, Not Tools</h2>

<p>A common mistake would be to start with a technology question such as: “Do we need a graph database?”</p>

<p>A better first question is:</p>

<blockquote>
  <p>Who would benefit if we understood the relationships around data better?</p>
</blockquote>

<p>Potential stakeholder roles include:</p>

<h3 id="business-analyst-or-data-consumer">Business Analyst or Data Consumer</h3>

<p>They want to find the right data product, understand whether it can be trusted, and see where it comes from.</p>

<p>Useful questions:</p>

<ul>
  <li>Is this the recommended data product for my use case?</li>
  <li>Who owns it?</li>
  <li>What reports or semantic models already use it?</li>
  <li>Is there a contract, description, or known limitation?</li>
</ul>

<p>Possible outputs:</p>

<ul>
  <li>Enriched data portal detail page</li>
  <li>Data product relationship view</li>
  <li>Source and ownership summary</li>
  <li>Related reports and related data products</li>
</ul>

<h3 id="report-owner-or-analytics-product-owner">Report Owner or Analytics Product Owner</h3>

<p>They care about the reports and analytical products used by the business.</p>

<p>Useful questions:</p>

<ul>
  <li>Which upstream data products feed this report?</li>
  <li>What changed if the numbers suddenly look different?</li>
  <li>Which semantic model or dataset is the report dependent on?</li>
  <li>Are there cross-domain dependencies behind this report?</li>
</ul>

<p>Possible outputs:</p>

<ul>
  <li>Report lineage diagram</li>
  <li>Affected reports list</li>
  <li>Semantic model dependency view</li>
  <li>Report confidence or source transparency summary</li>
</ul>

<h3 id="kpi-owner-or-business-controller">KPI Owner or Business Controller</h3>

<p>They care about the meaning, reliability, and comparability of business metrics.</p>

<p>Useful questions:</p>

<ul>
  <li>Where does this KPI come from?</li>
  <li>Which source systems and transformations affect it?</li>
  <li>Has the calculation logic changed?</li>
  <li>Can I distinguish business change from data pipeline change?</li>
</ul>

<p>Possible outputs:</p>

<ul>
  <li>KPI lineage view</li>
  <li>Calculation and source transparency page</li>
  <li>KPI impact report</li>
</ul>

<h3 id="business-process-owner">Business Process Owner</h3>

<p>They care about operational processes such as order-to-cash, procure-to-pay, supply chain planning, field service, spare parts, production follow-up, or finance closing.</p>

<p>Useful questions:</p>

<ul>
  <li>Which data products support this process?</li>
  <li>Which KPIs, reports, or AI use cases depend on this data?</li>
  <li>What business process is affected if the data is late, stale, or incorrect?</li>
</ul>

<p>Possible outputs:</p>

<ul>
  <li>Business process dependency map</li>
  <li>Critical data product list</li>
  <li>Process-level data risk view</li>
</ul>

<h3 id="field-service-spare-parts-supply-chain-or-manufacturing-owner">Field Service, Spare Parts, Supply Chain, or Manufacturing Owner</h3>

<p>These roles bring the strongest manufacturing-specific use cases.</p>

<p>Useful questions:</p>

<ul>
  <li>Which machines, components, customers, suppliers, or spare parts are connected through data?</li>
  <li>Which customers are affected by a component or material change?</li>
  <li>Which service events are related to a recurring asset issue?</li>
  <li>What data context would improve field service or spare part recommendations?</li>
</ul>

<p>Possible outputs:</p>

<ul>
  <li>Asset relationship diagram</li>
  <li>Component impact view</li>
  <li>Supply chain dependency map</li>
  <li>AI-readiness assessment for service or spare parts use cases</li>
</ul>

<h3 id="data-product-responsible-or-domain-owner">Data Product Responsible or Domain Owner</h3>

<p>They need visibility into the data products they provide and consume.</p>

<p>Useful questions:</p>

<ul>
  <li>Who consumes my data product?</li>
  <li>Does the implementation match the data product contract?</li>
  <li>Which reports, AI use cases, or business processes depend on it?</li>
  <li>Which consumer teams should be informed before changes?</li>
</ul>

<p>Possible outputs:</p>

<ul>
  <li>Data product consumer map</li>
  <li>Contract coverage report</li>
  <li>Producer-consumer dependency list</li>
  <li>Data product health score</li>
</ul>

<h3 id="data-steward-governance-owner-security-or-compliance">Data Steward, Governance Owner, Security, or Compliance</h3>

<p>They care about traceability, ownership, classification, and auditability.</p>

<p>Useful questions:</p>

<ul>
  <li>Which data products lack ownership or documentation?</li>
  <li>Where does sensitive data flow?</li>
  <li>Which data products are used in critical business processes?</li>
  <li>Can we prove how a metric or report is built?</li>
</ul>

<p>Possible outputs:</p>

<ul>
  <li>Governance gap report</li>
  <li>Sensitive data lineage diagram</li>
  <li>Missing owner list</li>
  <li>Audit evidence package</li>
</ul>

<h3 id="ai-lead-or-business-ai-owner">AI Lead or Business AI Owner</h3>

<p>AI makes this topic more urgent.</p>

<p>An AI assistant can retrieve documents, but that is not enough. Enterprise AI needs context: source systems, ownership, trust, usage, business meaning, and relationships.</p>

<p>Useful questions:</p>

<ul>
  <li>Can an AI assistant explain where an answer came from?</li>
  <li>Can it identify the owner of the data behind the answer?</li>
  <li>Can it understand that a machine belongs to a site, a site belongs to a customer, and a service event is related to a component?</li>
  <li>Which data products are ready for AI use?</li>
</ul>

<p>Possible outputs:</p>

<ul>
  <li>AI-ready metadata model</li>
  <li>Data product discovery assistant</li>
  <li>Relationship-aware Q&amp;A</li>
  <li>Source and ownership explanation for AI answers</li>
</ul>

<h2 id="how-i-would-run-the-spike">How I Would Run the Spike</h2>

<p>The first deliverable should not be a solution architecture. It should be a better set of questions and a prioritized set of use cases.</p>

<h3 id="1-collect-role-based-questions">1. Collect Role-Based Questions</h3>

<p>Start with interviews or short workshops. Ask each role what they would like to know if the data platform could explain relationships better.</p>

<p>Do not start with lineage diagrams. Start with decisions.</p>

<p>Example prompt:</p>

<blockquote>
  <p>What decision would become easier if you understood the origin, ownership, usage, and business impact of data better?</p>
</blockquote>

<h3 id="2-map-existing-metadata-sources">2. Map Existing Metadata Sources</h3>

<p>Inventory what already exists.</p>

<p>Possible sources:</p>

<ul>
  <li>Data product contracts</li>
  <li>Data catalog content</li>
  <li>Data portal content</li>
  <li>Fabric workspaces and items</li>
  <li>Semantic models and reports</li>
  <li>OneLake Catalog</li>
  <li>Purview metadata and lineage</li>
  <li>Source system metadata</li>
  <li>Usage metrics</li>
  <li>Ownership metadata</li>
  <li>Support and operational metadata</li>
  <li>Documentation and architecture decisions</li>
  <li>CI/CD and repository metadata</li>
</ul>

<p>Classify each source:</p>

<ul>
  <li>already structured</li>
  <li>manually maintained</li>
  <li>available through API</li>
  <li>available only by convention</li>
  <li>missing completely</li>
</ul>

<h3 id="3-test-native-fabric-capabilities-first">3. Test Native Fabric Capabilities First</h3>

<p>Use the strategic platform before adding new components.</p>

<p>Test questions such as:</p>

<ul>
  <li>What lineage does Fabric show automatically?</li>
  <li>What impact can semantic model analysis reveal?</li>
  <li>What does OneLake Catalog already know?</li>
  <li>What can Purview add?</li>
  <li>Which metadata is available through APIs?</li>
  <li>Can a Data Agent answer simple relationship questions?</li>
  <li>Could Fabric Graph or ontology capabilities help with multi-hop or business-semantic questions?</li>
</ul>

<h3 id="4-identify-the-gaps">4. Identify the Gaps</h3>

<p>The gap analysis is the most valuable output of the spike.</p>

<p>Typical gaps may include:</p>

<ul>
  <li>ownership is manually maintained</li>
  <li>data product contracts are not connected to actual Fabric items</li>
  <li>business processes are not linked to reports or KPIs</li>
  <li>downstream consumers are not fully known</li>
  <li>usage metrics are not connected to data product criticality</li>
  <li>AI assistants do not yet have trusted relationship context</li>
</ul>

<h3 id="5-select-poc-candidates">5. Select PoC Candidates</h3>

<p>After the spike, pick a small number of PoCs. Each PoC should test one business question, not one technology.</p>

<p>Good candidates:</p>

<ul>
  <li>KPI lineage PoC: where does this KPI come from?</li>
  <li>Data product consumer PoC: who uses this data product?</li>
  <li>Data portal enrichment PoC: can we reduce manual maintenance?</li>
  <li>Manufacturing asset relationship PoC: how are customer, site, machine, component, service event, and spare part connected?</li>
  <li>AI assistant PoC: can an assistant explain an answer with source, ownership, and relationship context?</li>
</ul>

<h2 id="what-good-outputs-might-look-like">What Good Outputs Might Look Like</h2>

<p>The spike should produce tangible outputs, even before any production solution exists.</p>

<p>Possible outputs:</p>

<ul>
  <li>Prioritized use case list</li>
  <li>Role-to-question map</li>
  <li>Metadata source inventory</li>
  <li>Fabric-native capability assessment</li>
  <li>Gap analysis</li>
  <li>Candidate relationship model</li>
  <li>PoC backlog</li>
  <li>Example diagrams</li>
  <li>Example JSON output for a data portal</li>
  <li>Example Power BI report concept</li>
  <li>AI assistant prompt and response examples</li>
</ul>

<h2 id="what-i-would-avoid-at-the-beginning">What I Would Avoid at the Beginning</h2>

<p>I would avoid starting with product selection.</p>

<p>The wrong first questions are:</p>

<ul>
  <li>Do we need a graph database?</li>
  <li>Should this be implemented with a specific product?</li>
  <li>Can AI solve this for us?</li>
  <li>Should we build a new catalog?</li>
</ul>

<p>The better first questions are:</p>

<ul>
  <li>Who needs relationship context?</li>
  <li>Which decisions would improve?</li>
  <li>Which metadata already exists?</li>
  <li>Which parts can be automated?</li>
  <li>Which use cases are valuable enough for a PoC?</li>
</ul>

<h2 id="conclusion">Conclusion</h2>

<p>Data lineage is a useful starting point, but the bigger opportunity is relationship intelligence.</p>

<p>For a manufacturing data platform, that means connecting data products, contracts, catalogs, portals, reports, KPIs, business processes, assets, ownership, governance, and AI context.</p>

<p>The first step is not to choose a product. The first step is to run a focused spike that discovers the best use cases, tests the native platform capabilities, and identifies what additional metadata or automation is actually needed.</p>

<p>Only after that does it make sense to decide which PoCs to build.</p>

<h2 id="references">References</h2>

<ul>
  <li><a href="https://learn.microsoft.com/en-us/fabric/">Microsoft Fabric documentation</a></li>
  <li><a href="https://learn.microsoft.com/en-us/fabric/governance/lineage">Lineage in Fabric</a></li>
  <li><a href="https://learn.microsoft.com/en-us/fabric/governance/impact-analysis">Impact analysis in Fabric</a></li>
  <li><a href="https://learn.microsoft.com/en-us/fabric/governance/microsoft-purview-fabric">Use Microsoft Purview to govern Microsoft Fabric</a></li>
  <li><a href="https://learn.microsoft.com/en-us/fabric/governance/onelake-catalog-overview">OneLake catalog overview</a></li>
  <li><a href="https://learn.microsoft.com/en-us/fabric/data-science/concept-data-agent">Fabric data agent concepts</a></li>
  <li><a href="https://learn.microsoft.com/en-us/fabric/graph/overview">Graph in Microsoft Fabric overview (preview)</a></li>
  <li><a href="https://learn.microsoft.com/en-us/fabric/iq/">Fabric IQ</a></li>
</ul>]]></content><author><name>Okko Oulasvirta</name></author><category term="data" /><category term="microsoft-fabric" /><category term="data-lineage" /><category term="data-products" /><category term="ai" /><category term="manufacturing" /><category term="governance" /><summary type="html"><![CDATA[A thinking-out-loud exploration of how manufacturing data platforms can move beyond technical lineage diagrams toward relationship intelligence across data products, business processes, ownership, governance, and AI context.]]></summary></entry><entry><title type="html">Building an Electron Multi-Auth MVP: A Development Journal</title><link href="/labs/2026/02/22/electron-multi-auth-mvp-journal.html" rel="alternate" type="text/html" title="Building an Electron Multi-Auth MVP: A Development Journal" /><published>2026-02-22T00:00:00+00:00</published><updated>2026-02-22T00:00:00+00:00</updated><id>/labs/2026/02/22/electron-multi-auth-mvp-journal</id><content type="html" xml:base="/labs/2026/02/22/electron-multi-auth-mvp-journal.html"><![CDATA[<h2 id="introduction">Introduction</h2>

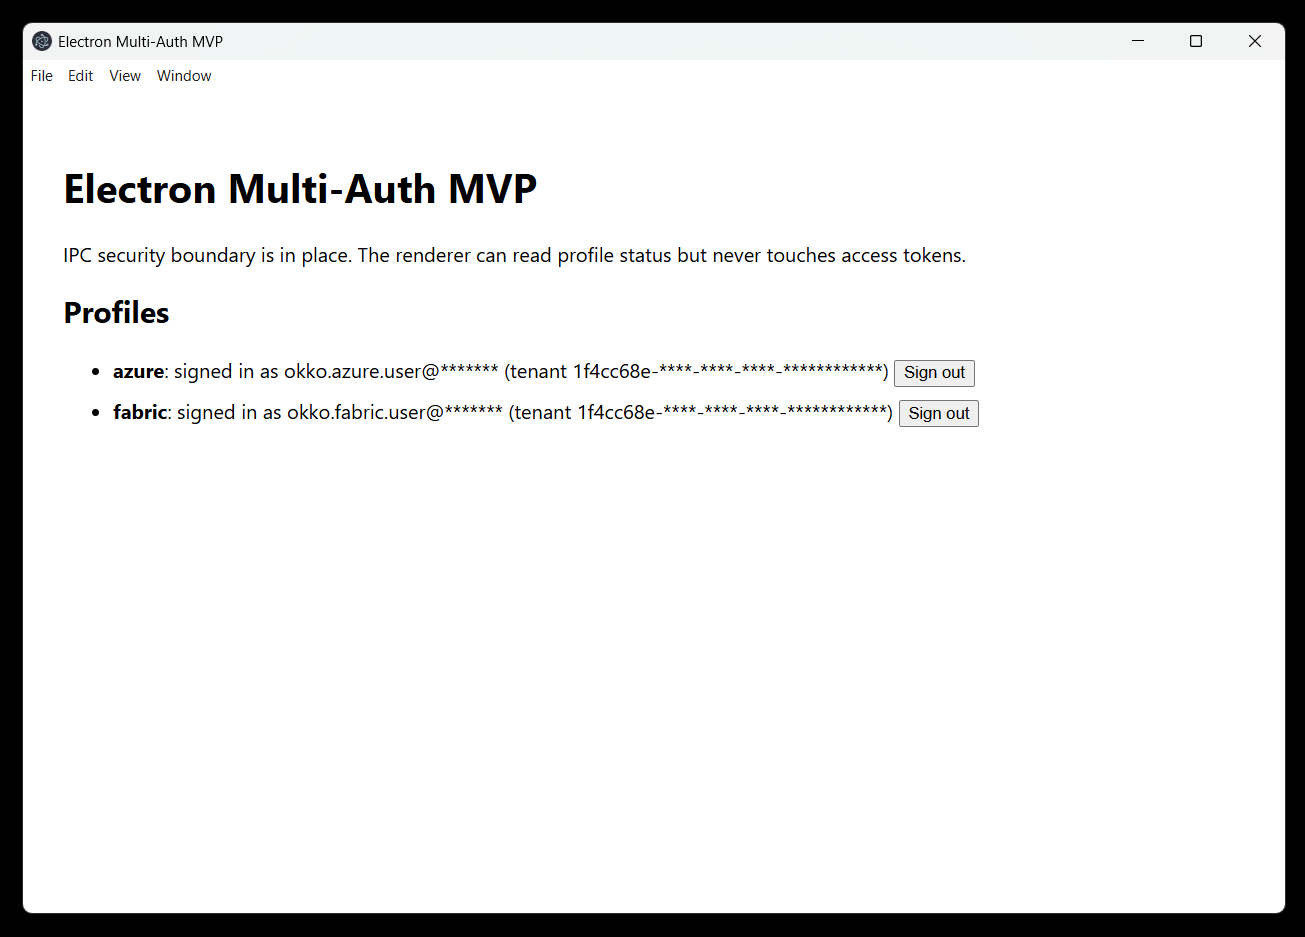
<p>This post documents building an Electron desktop app that signs in simultaneously to two different Microsoft Entra ID identities — one for Azure, one for Microsoft Fabric — with strict isolation between them.</p>

<p><strong>Why it matters.</strong> As soon as a tool needs more than one resource type, it stops being “a script” and becomes a small app. A consultant building for a client typically talks to several control planes in the same session — Azure Resource Manager, Azure DevOps, the Fabric REST API — each potentially needing its own identity, audience, and sometimes its own tenant. A Python CLI piggybacking on <code class="language-plaintext highlighter-rouge">az login</code> is fine for personal automation but collapses with two concurrent identities. An Electron app orchestrating the auth flows itself can hold independent token caches, drive separate system-browser sign-ins, and present a real UI for what would otherwise be a tangle of CLI subshells.</p>

<h2 id="goals--success-criteria">Goals &amp; Success Criteria</h2>

<table>
  <thead>
    <tr>
      <th>ID</th>
      <th>Goal</th>
      <th>Success Criteria</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>G1</td>
      <td>Dual identity support</td>
      <td>User can authenticate with two separate Entra ID accounts simultaneously</td>
    </tr>
    <tr>
      <td>G2</td>
      <td>Profile isolation</td>
      <td>Tokens and session data from one profile cannot leak to another</td>
    </tr>
    <tr>
      <td>G3</td>
      <td>No Azure CLI dependency</td>
      <td>All auth flows work without <code class="language-plaintext highlighter-rouge">az login</code></td>
    </tr>
    <tr>
      <td>G4</td>
      <td>Browser-based OAuth</td>
      <td>Uses Authorization Code + PKCE via system browser</td>
    </tr>
    <tr>
      <td>G5</td>
      <td>No plaintext tokens on disk</td>
      <td>Per-profile MSAL token caches may persist via OS-encrypted storage (Electron <code class="language-plaintext highlighter-rouge">safeStorage</code>); tokens never cross into the renderer</td>
    </tr>
    <tr>
      <td>G6</td>
      <td>Secure IPC</td>
      <td>Tokens never exposed to renderer process</td>
    </tr>
  </tbody>
</table>

<h2 id="tech-stack">Tech Stack</h2>

<ul>
  <li><strong>Electron 42</strong> — desktop framework; renders Chromium for the UI and runs Node.js in the main process for token handling. Pinned to a current major after the first <code class="language-plaintext highlighter-rouge">npm audit</code> flagged 17 CVEs against the older 31.x line — a worthwhile early lesson that platform pins drift faster than feature code does</li>
  <li><strong>TypeScript 5.5</strong> — strict mode with <code class="language-plaintext highlighter-rouge">noUncheckedIndexedAccess</code> and <code class="language-plaintext highlighter-rouge">exactOptionalPropertyTypes</code>; the IPC contract leans on the type system to mechanically forbid token-shaped fields</li>
  <li><strong>React 18</strong> — renderer UI only; the main process stays UI-free</li>
  <li><strong>esbuild 0.28</strong> — bundles the renderer <strong>and the preload script</strong> (the latter is required by Electron’s sandbox; see the Azure stage); main process still compiles with plain <code class="language-plaintext highlighter-rouge">tsc</code></li>
  <li><strong>MSAL Node (<code class="language-plaintext highlighter-rouge">@azure/msal-node</code>)</strong> — OAuth 2.0 Authorization Code + PKCE driven from the main process; the right tool for Electron, where <code class="language-plaintext highlighter-rouge">@azure/identity</code>’s <code class="language-plaintext highlighter-rouge">InteractiveBrowserCredential</code> is browser-only</li>
  <li><strong>Node.js 22+</strong> — the small <code class="language-plaintext highlighter-rouge">audit:ipc</code> script uses <code class="language-plaintext highlighter-rouge">--experimental-strip-types</code> to run TypeScript directly without a separate tool</li>
</ul>

<h2 id="development-log">Development Log</h2>

<!--
Each stage is written up retrospectively after implementation:
- What I tried (approach taken, key decisions, trade-offs)
- What I observed (challenges, surprises, lessons learned)
- Optional: a small code highlight
-->

<h3 id="ipc-security-layer">IPC Security Layer</h3>

<blockquote>
  <p><strong>IPC</strong> (<em>Inter-Process Communication</em>) is how Electron’s two processes talk to each other. The <strong>main process</strong> is a Node.js process with full OS access — this is where tokens live. The <strong>renderer process</strong> runs the UI (HTML/JS) and is treated as untrusted because it handles web content (XSS risk). They don’t share memory, so any data exchange goes through explicit IPC channels via a preload script. Getting these channels right is the difference between a token staying in main memory and leaking to the renderer.</p>
</blockquote>

<p>The first stage establishes the security boundary between Electron’s main and renderer processes — a typed IPC contract plus a hardened preload script, designed so access tokens can never structurally cross into the renderer. Only safe profile metadata (sign-in status, account name) is exposed.</p>

<p><strong>What I tried:</strong> define a single typed contract module shared by main, preload, and renderer; expose exactly one bridge (<code class="language-plaintext highlighter-rouge">window.api</code>) via <code class="language-plaintext highlighter-rouge">contextBridge</code>; lock down <code class="language-plaintext highlighter-rouge">webPreferences</code> to <code class="language-plaintext highlighter-rouge">contextIsolation: true</code>, <code class="language-plaintext highlighter-rouge">nodeIntegration: false</code>, <code class="language-plaintext highlighter-rouge">sandbox: true</code>; add a strict CSP to the renderer HTML; and back the type system up with a runtime guard that walks every IPC response looking for token-shaped fields.</p>

<p><strong>What I observed:</strong></p>

<ol>
  <li>
    <p><strong>Starting with IPC made the rest of the work calmer.</strong> Once <code class="language-plaintext highlighter-rouge">window.api</code> was the only renderer surface, every later feature had to fit through a small, reviewable shape.</p>
  </li>
  <li>
    <p><strong>I still do not trust compile-time checks by themselves.</strong> The type assertion is useful, but the runtime <code class="language-plaintext highlighter-rouge">safeResponse</code> guard is what catches the “I cast this and moved on” kind of mistake.</p>
  </li>
  <li>
    <p><strong>The audit script paid for itself immediately.</strong> It made the IPC surface cheap to check, and it also exposed its own first bug when <code class="language-plaintext highlighter-rouge">profile:azure:sign-in</code> did not match the original regex.</p>
  </li>
  <li>
    <p><strong>The Electron security baseline only felt real as a set.</strong> <code class="language-plaintext highlighter-rouge">contextIsolation</code>, <code class="language-plaintext highlighter-rouge">nodeIntegration: false</code>, <code class="language-plaintext highlighter-rouge">sandbox</code>, and CSP each cover a different way to get this wrong.</p>
  </li>
</ol>

<p><strong>A couple of code highlights:</strong></p>

<p>The compile-time block on token-shaped fields lives in the shared contract:</p>

<div class="language-typescript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">type</span> <span class="nx">ForbiddenKey</span> <span class="o">=</span> <span class="dl">"</span><span class="s2">accessToken</span><span class="dl">"</span> <span class="o">|</span> <span class="dl">"</span><span class="s2">refreshToken</span><span class="dl">"</span> <span class="o">|</span> <span class="dl">"</span><span class="s2">idToken</span><span class="dl">"</span> <span class="o">|</span> <span class="dl">"</span><span class="s2">token</span><span class="dl">"</span> <span class="o">|</span> <span class="dl">"</span><span class="s2">bearer</span><span class="dl">"</span><span class="p">;</span>

<span class="kd">type</span> <span class="nx">AssertNoTokens</span><span class="o">&lt;</span><span class="nx">T</span><span class="o">&gt;</span> <span class="o">=</span> <span class="nx">Extract</span><span class="o">&lt;</span><span class="kr">keyof</span> <span class="nx">T</span><span class="p">,</span> <span class="nx">ForbiddenKey</span><span class="o">&gt;</span> <span class="kd">extends</span> <span class="nx">never</span> <span class="p">?</span> <span class="nx">T</span> <span class="p">:</span> <span class="nx">never</span><span class="p">;</span>

<span class="c1">// If ProfileStatus ever grows a forbidden field, this line errors at build time.</span>
<span class="kd">type</span> <span class="nx">_AssertProfileStatus</span> <span class="o">=</span> <span class="nx">AssertNoTokens</span><span class="o">&lt;</span><span class="nx">ProfileStatus</span><span class="o">&gt;</span><span class="p">;</span>
</code></pre></div></div>

<p>And the runtime guard every handler funnels its response through:</p>

<div class="language-typescript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">export</span> <span class="kd">function</span> <span class="nx">safeResponse</span><span class="o">&lt;</span><span class="nx">T</span><span class="o">&gt;</span><span class="p">(</span><span class="nx">value</span><span class="p">:</span> <span class="nx">T</span><span class="p">):</span> <span class="nx">T</span> <span class="p">{</span>
  <span class="nx">assertNoTokenFieldsImpl</span><span class="p">(</span><span class="nx">value</span><span class="p">,</span> <span class="mi">0</span><span class="p">);</span>   <span class="c1">// recursive walk; throws on a forbidden key</span>
  <span class="k">return</span> <span class="nx">value</span><span class="p">;</span>
<span class="p">}</span>

<span class="nx">ipcMain</span><span class="p">.</span><span class="nx">handle</span><span class="p">(</span><span class="nx">IpcChannels</span><span class="p">.</span><span class="nx">GetProfileStatus</span><span class="p">,</span> <span class="p">(</span><span class="nx">_e</span><span class="p">,</span> <span class="nx">req</span><span class="p">)</span> <span class="o">=&gt;</span> <span class="p">{</span>
  <span class="k">return</span> <span class="nx">safeResponse</span><span class="p">(</span><span class="nx">getProfileStatus</span><span class="p">(</span><span class="nx">req</span><span class="p">.</span><span class="nx">profile</span><span class="p">));</span>
<span class="p">});</span>
</code></pre></div></div>

<p><strong>Verifying this stage:</strong></p>

<p>The point of this stage isn’t a feature you can demo — it’s an invariant you can <em>prove</em>. Five checks, each with an expected outcome:</p>

<table>
  <thead>
    <tr>
      <th>#</th>
      <th>Check</th>
      <th>Expected outcome</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>1</td>
      <td><code class="language-plaintext highlighter-rouge">npm run typecheck</code></td>
      <td>No errors</td>
    </tr>
    <tr>
      <td>2</td>
      <td><code class="language-plaintext highlighter-rouge">npm run build</code></td>
      <td><code class="language-plaintext highlighter-rouge">dist/</code> is produced; renderer bundles cleanly</td>
    </tr>
    <tr>
      <td>3</td>
      <td><code class="language-plaintext highlighter-rouge">npm run audit:ipc</code></td>
      <td><code class="language-plaintext highlighter-rouge">IPC audit: OK · Channels declared: 1 · Preload bridges: 1 (api)</code></td>
    </tr>
    <tr>
      <td>4</td>
      <td><code class="language-plaintext highlighter-rouge">npm start</code>, then in renderer DevTools: <code class="language-plaintext highlighter-rouge">window.require</code>, <code class="language-plaintext highlighter-rouge">window.process</code>, <code class="language-plaintext highlighter-rouge">window.ipcRenderer</code></td>
      <td>All three return <code class="language-plaintext highlighter-rouge">undefined</code>; <code class="language-plaintext highlighter-rouge">Object.keys(window.api)</code> returns exactly <code class="language-plaintext highlighter-rouge">["getProfileStatus"]</code></td>
    </tr>
    <tr>
      <td>5</td>
      <td>Grep <code class="language-plaintext highlighter-rouge">dist/renderer/renderer.js</code> for <code class="language-plaintext highlighter-rouge">ipcRenderer</code></td>
      <td>No matches — the renderer bundle has no awareness of Electron’s IPC API</td>
    </tr>
  </tbody>
</table>

<p>And three deliberate-regression tests that should <em>fail</em> if the boundary is real:</p>

<table>
  <thead>
    <tr>
      <th>#</th>
      <th>Break attempt</th>
      <th>Expected outcome</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>A</td>
      <td>Add <code class="language-plaintext highlighter-rouge">accessToken: string</code> to <code class="language-plaintext highlighter-rouge">ProfileStatus</code> and run <code class="language-plaintext highlighter-rouge">npm run typecheck</code></td>
      <td>Type error from the <code class="language-plaintext highlighter-rouge">AssertNoTokens</code> assertion</td>
    </tr>
    <tr>
      <td>B</td>
      <td>Return <code class="language-plaintext highlighter-rouge">{ ...status, refreshToken: "leaked" } as ProfileStatus</code> from a handler, restart, call from renderer</td>
      <td>Runtime throw: <code class="language-plaintext highlighter-rouge">IPC security violation: response contains forbidden field "refreshToken"</code></td>
    </tr>
    <tr>
      <td>C</td>
      <td>Add a second <code class="language-plaintext highlighter-rouge">contextBridge.exposeInMainWorld("danger", ...)</code> in the preload and run <code class="language-plaintext highlighter-rouge">npm run audit:ipc</code></td>
      <td>Audit fails: <code class="language-plaintext highlighter-rouge">Preload exposes 2 world bridges; expected exactly 1 named "api"</code></td>
    </tr>
  </tbody>
</table>

<p>With those eight checks passing the way they should, the security claim isn’t documentation any more — it’s mechanically enforced.</p>

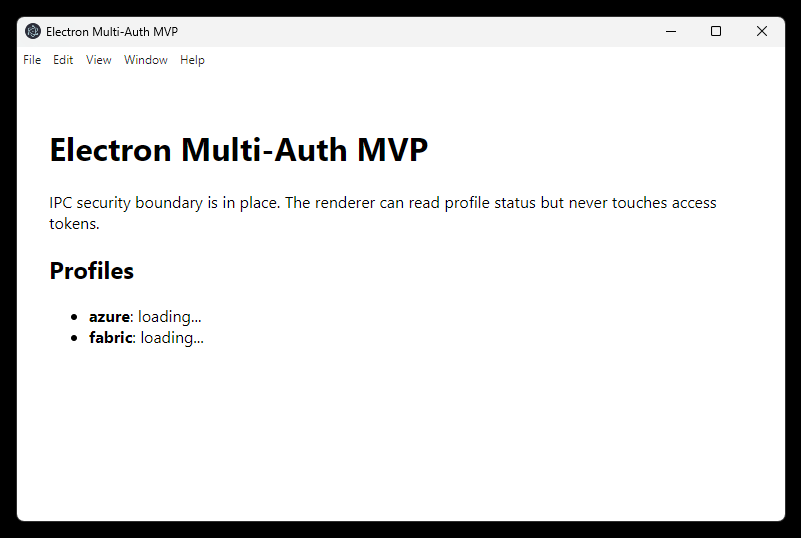
<p>And here’s what the running app actually looks like at the end of this stage — boring on purpose. No tokens, no real profiles yet, just the bare evidence that the IPC boundary works end-to-end: the renderer can ask the main process for both profile statuses, and the main process answers with safe metadata only.</p>

<p><img src="/assets/images/2026-02-22-electron-multi-auth-mvp/stage1-ipc-running.png" alt="Electron app window titled 'Electron Multi-Auth MVP' showing both azure and fabric profiles in a loading/unauthenticated state, with the IPC security boundary in place." />
<em>Stage 1 complete: renderer reads profile status over a typed, token-free IPC channel.</em></p>

<hr />

<h3 id="azure-profile-authentication">Azure Profile Authentication</h3>

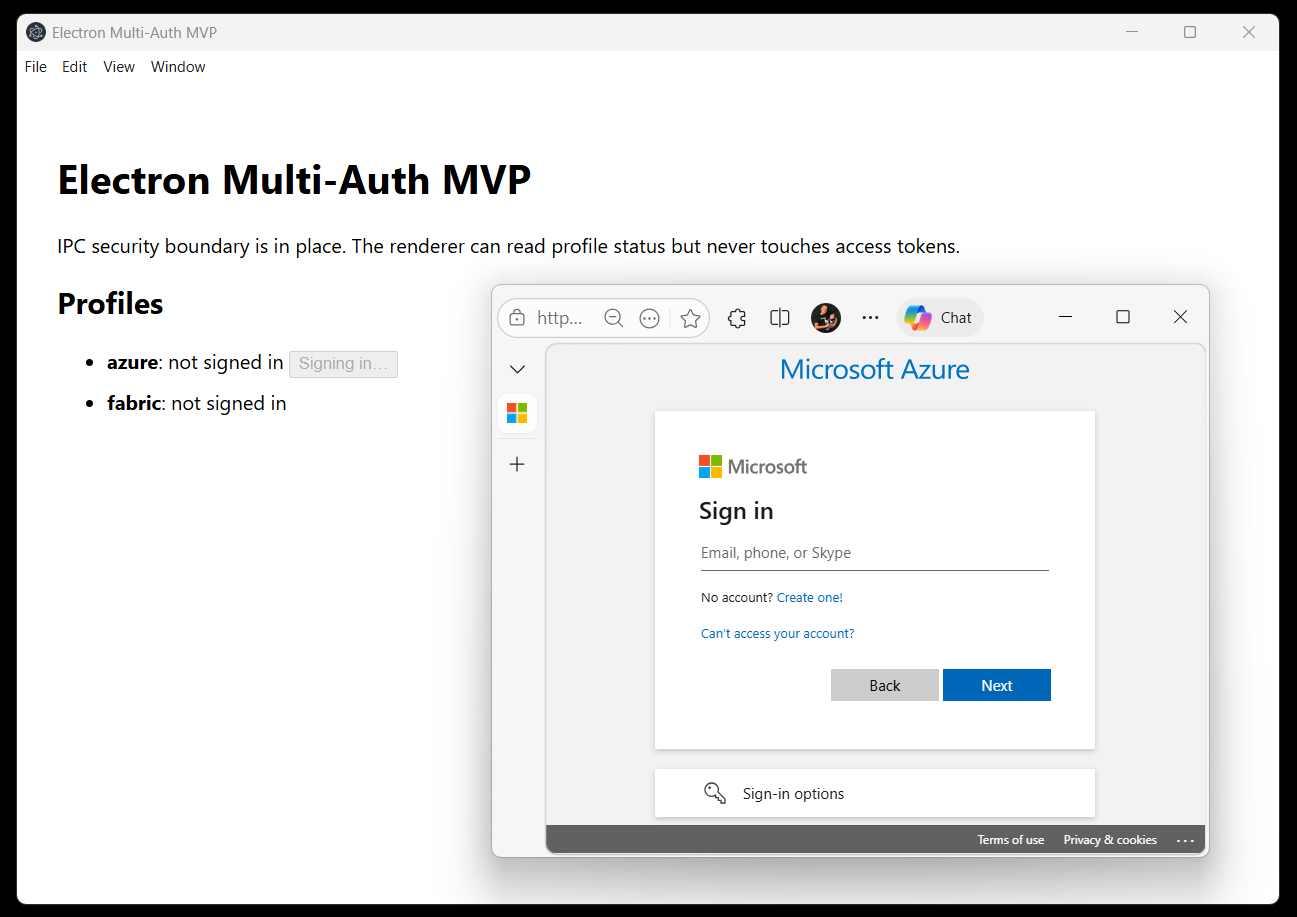
<p>First identity (Profile A): OAuth 2.0 Authorization Code + PKCE through the system browser, targeting the Azure Resource Manager audience (<code class="language-plaintext highlighter-rouge">https://management.azure.com/.default</code>). The renderer never receives tokens; main owns the MSAL client, profile state, and token cache boundary.</p>

<p><strong>What I tried:</strong> add a small <code class="language-plaintext highlighter-rouge">src/main/auth/</code> module that owns the Azure token lifecycle end-to-end. <code class="language-plaintext highlighter-rouge">@azure/msal-node</code>’s <code class="language-plaintext highlighter-rouge">PublicClientApplication.acquireTokenInteractive</code> drives the flow; the system browser is opened explicitly via <code class="language-plaintext highlighter-rouge">shell.openExternal</code>, MSAL picks an ephemeral loopback port for the redirect, and the resulting <code class="language-plaintext highlighter-rouge">AuthenticationResult</code> is stored in module-scope state. A new IPC channel (<code class="language-plaintext highlighter-rouge">profile:azure:sign-in</code>) exposes a single trigger to the renderer; the existing <code class="language-plaintext highlighter-rouge">getProfileStatus</code> channel now returns the real Azure profile state instead of a placeholder. For the MVP I default the client ID to the well-known Azure CLI public client (<code class="language-plaintext highlighter-rouge">04b07795-…</code>), so the app works without anyone having to register their own Entra app first — overridable via <code class="language-plaintext highlighter-rouge">AZURE_CLIENT_ID</code>/<code class="language-plaintext highlighter-rouge">AZURE_TENANT_ID</code> env vars.</p>

<p><strong>What I observed:</strong></p>

<ol>
  <li>
    <p><strong><code class="language-plaintext highlighter-rouge">@azure/identity</code> was the wrong first instinct.</strong> I reached for the familiar Azure SDK, then hit the runtime mismatch. In Electron main, <code class="language-plaintext highlighter-rouge">@azure/msal-node</code> is the right tool.</p>
  </li>
  <li>
    <p><strong>The public-client flow kept the secret story simple.</strong> No client secret, no service principal, no Azure CLI dependency. The client ID is configuration, not a credential.</p>
  </li>
  <li>
    <p><strong>The sandboxed preload failure was the annoying one.</strong> The renderer only showed <code class="language-plaintext highlighter-rouge">window.api</code> as missing; the real error was in main-process stderr. Bundling the preload with esbuild fixed it.</p>
  </li>
  <li>
    <p><strong>MSAL’s silent SSO default was wrong for this app.</strong> It picked the browser’s current account without asking. <code class="language-plaintext highlighter-rouge">prompt: "select_account"</code> is part of the multi-profile contract, not just UX polish.</p>
  </li>
  <li>
    <p><strong>The system browser felt less slick but more correct.</strong> MFA, password managers, and Conditional Access stay where the user already trusts them.</p>
  </li>
  <li>
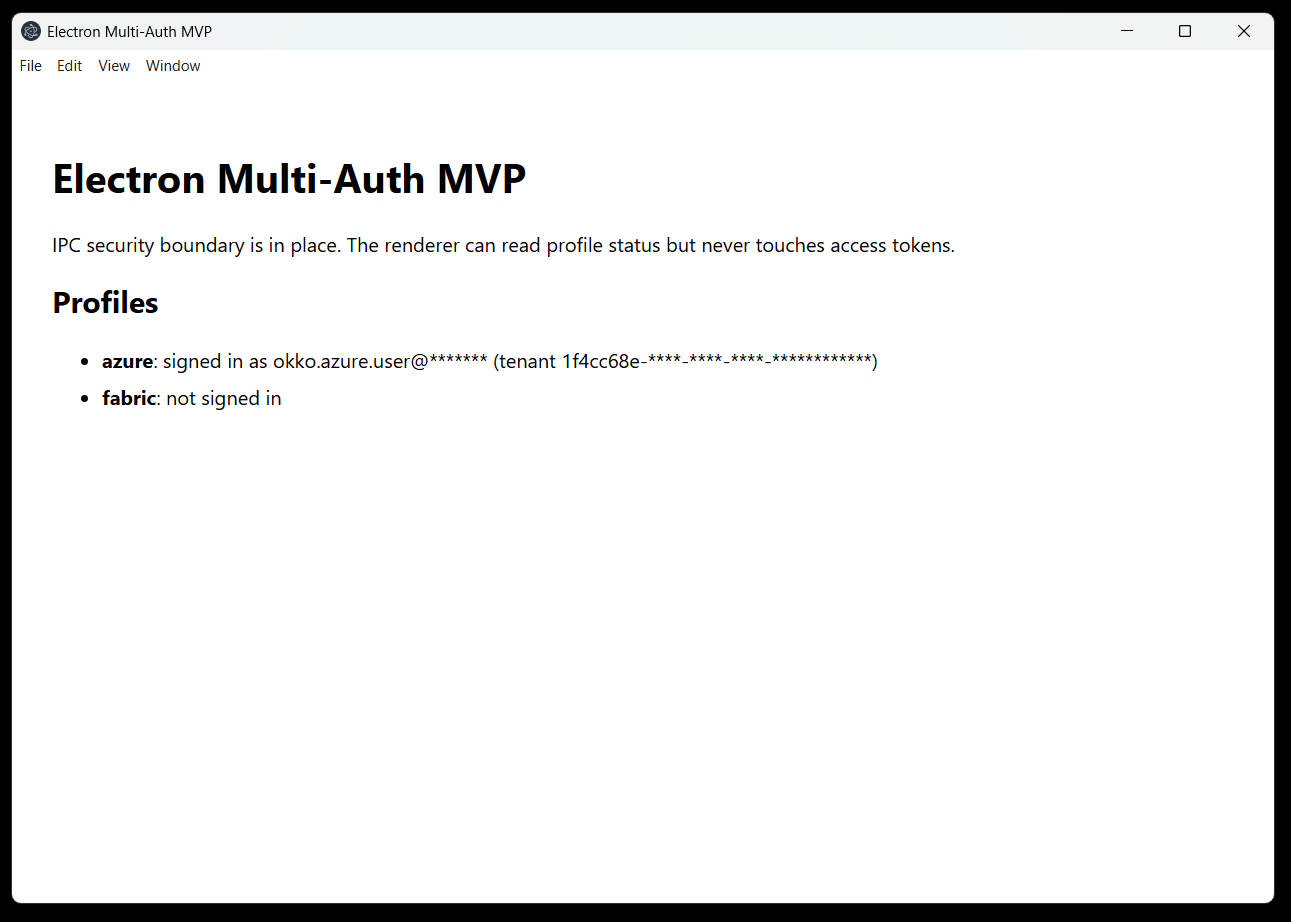
    <p><strong>Masking the UPN and tenant in the UI was worth doing early.</strong> It is not a security boundary, but it made every screenshot safe by default.</p>
  </li>
  <li>
    <p><strong>The IPC work paid off here.</strong> Adding Azure sign-in did not require new token protections; it just had to return the existing safe profile snapshot.</p>
  </li>
</ol>

<p><strong>A couple of code highlights:</strong></p>

<p>The whole Azure auth surface is small. The interactive flow:</p>

<div class="language-typescript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">const</span> <span class="nx">pca</span> <span class="o">=</span> <span class="k">new</span> <span class="nx">PublicClientApplication</span><span class="p">({</span>
  <span class="na">auth</span><span class="p">:</span> <span class="p">{</span> <span class="na">clientId</span><span class="p">:</span> <span class="nx">config</span><span class="p">.</span><span class="nx">clientId</span><span class="p">,</span> <span class="na">authority</span><span class="p">:</span> <span class="nx">config</span><span class="p">.</span><span class="nx">authority</span> <span class="p">},</span>
<span class="p">});</span>

<span class="kd">const</span> <span class="nx">result</span> <span class="o">=</span> <span class="k">await</span> <span class="nx">pca</span><span class="p">.</span><span class="nx">acquireTokenInteractive</span><span class="p">({</span>
  <span class="na">scopes</span><span class="p">:</span> <span class="p">[</span><span class="nx">config</span><span class="p">.</span><span class="nx">scope</span><span class="p">],</span>                          <span class="c1">// https://management.azure.com/.default</span>
  <span class="na">prompt</span><span class="p">:</span> <span class="dl">"</span><span class="s2">select_account</span><span class="dl">"</span><span class="p">,</span>                        <span class="c1">// force the account chooser; never reuse SSO silently</span>
  <span class="na">openBrowser</span><span class="p">:</span> <span class="k">async</span> <span class="p">(</span><span class="nx">url</span><span class="p">)</span> <span class="o">=&gt;</span> <span class="p">{</span>
    <span class="k">await</span> <span class="nx">shell</span><span class="p">.</span><span class="nx">openExternal</span><span class="p">(</span><span class="nx">url</span><span class="p">);</span>                 <span class="c1">// user's real browser, not an embedded webview</span>
  <span class="p">},</span>
<span class="p">});</span>
</code></pre></div></div>

<p>And the renderer-facing snapshot — note what <em>isn’t</em> in the return type:</p>

<div class="language-typescript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">let</span> <span class="nx">state</span><span class="p">:</span> <span class="nx">AzureProfileState</span> <span class="o">=</span> <span class="nx">UNAUTHENTICATED</span><span class="p">;</span> <span class="c1">// module-scope; the access token never leaves</span>

<span class="k">export</span> <span class="kd">function</span> <span class="nx">getAzureProfileSnapshot</span><span class="p">():</span> <span class="p">{</span>
  <span class="nl">authenticated</span><span class="p">:</span> <span class="nx">boolean</span><span class="p">;</span>
  <span class="nl">accountName</span><span class="p">:</span> <span class="kr">string</span> <span class="o">|</span> <span class="kc">null</span><span class="p">;</span>
  <span class="nl">tenantId</span><span class="p">:</span> <span class="kr">string</span> <span class="o">|</span> <span class="kc">null</span><span class="p">;</span>
<span class="p">}</span> <span class="p">{</span>
  <span class="c1">// accessToken and expiresOn intentionally omitted from this view</span>
  <span class="k">return</span> <span class="p">{</span> <span class="na">authenticated</span><span class="p">:</span> <span class="nx">state</span><span class="p">.</span><span class="nx">authenticated</span><span class="p">,</span> <span class="na">accountName</span><span class="p">:</span> <span class="nx">state</span><span class="p">.</span><span class="nx">accountName</span><span class="p">,</span> <span class="na">tenantId</span><span class="p">:</span> <span class="nx">state</span><span class="p">.</span><span class="nx">tenantId</span> <span class="p">};</span>
<span class="p">}</span>
</code></pre></div></div>

<p><strong>Verifying this stage:</strong></p>

<p>Five behavioural checks, each requiring a real Entra ID account:</p>

<table>
  <thead>
    <tr>
      <th>#</th>
      <th>Check</th>
      <th>Expected outcome</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>1</td>
      <td>Click <strong>Sign in to Azure</strong> in the running app</td>
      <td>System browser opens at <code class="language-plaintext highlighter-rouge">login.microsoftonline.com</code></td>
    </tr>
    <tr>
      <td>2</td>
      <td>Complete sign-in (with MFA / Conditional Access if your tenant requires it)</td>
      <td>UI updates to <code class="language-plaintext highlighter-rouge">azure: signed in as &lt;upn&gt; (tenant &lt;tid&gt;)</code></td>
    </tr>
    <tr>
      <td>3</td>
      <td>Decode the in-memory token’s <code class="language-plaintext highlighter-rouge">aud</code> claim</td>
      <td>Value equals <code class="language-plaintext highlighter-rouge">https://management.azure.com</code></td>
    </tr>
    <tr>
      <td>4</td>
      <td>Inspect the in-memory token’s <code class="language-plaintext highlighter-rouge">tid</code> claim</td>
      <td>Matches the tenant shown in the UI</td>
    </tr>
    <tr>
      <td>5</td>
      <td>Inspect the in-memory token’s <code class="language-plaintext highlighter-rouge">preferred_username</code> claim</td>
      <td>Matches the account name shown in the UI</td>
    </tr>
  </tbody>
</table>

<p>And two regression checks that should still hold after sign-in:</p>

<table>
  <thead>
    <tr>
      <th>#</th>
      <th>Break attempt</th>
      <th>Expected outcome</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>A</td>
      <td>In renderer DevTools, run <code class="language-plaintext highlighter-rouge">Object.keys(window.api)</code> after sign-in</td>
      <td>Returns exactly <code class="language-plaintext highlighter-rouge">["getProfileStatus", "signInAzure"]</code> — no new token-bearing methods appeared</td>
    </tr>
    <tr>
      <td>B</td>
      <td>Grep <code class="language-plaintext highlighter-rouge">dist/preload/preload.js</code> and <code class="language-plaintext highlighter-rouge">dist/renderer/index.js</code> for the literal <code class="language-plaintext highlighter-rouge">accessToken</code></td>
      <td>No matches — the token shape is unknown to anything outside <code class="language-plaintext highlighter-rouge">src/main/auth/</code></td>
    </tr>
  </tbody>
</table>

<p>Once those pass, the Azure profile is wired up end-to-end with the token confined to the main-process auth module and never exposed over IPC — ready for the second profile to be added alongside it.</p>

<p>And here’s what the running app looks like mid-flow, after the <code class="language-plaintext highlighter-rouge">prompt: "select_account"</code> fix: the Electron window shows <code class="language-plaintext highlighter-rouge">azure: not signed in · Signing in…</code>, while the user’s real system browser is open at the Microsoft sign-in page with the account chooser visible. No embedded webview, no silent SSO — just an explicit, deliberate identity choice for Profile A.</p>

<p><img src="/assets/images/2026-02-22-electron-multi-auth-mvp/stage2-azure-auth-login.png" alt="Electron app showing the 'Signing in…' state side by side with the system browser open at the Microsoft Azure sign-in account picker, demonstrating that the account chooser appears instead of silent SSO and that the consent UI lives in the real browser, not an embedded webview." />
<em>Stage 2 in flight: account chooser in the user’s real browser, Electron waiting on the loopback redirect.</em></p>

<p>And after sign-in completes, the same window settles into the success state. The <strong>Sign in to Azure</strong> button is gone (a real sign-out affordance is wired up later in the <code class="language-plaintext highlighter-rouge">add-sign-out</code> change), the row shows the masked UPN and masked tenant ID, and the access token itself never crossed into the renderer at all — only the safe metadata did.</p>

<p><img src="/assets/images/2026-02-22-electron-multi-auth-mvp/stage2-azure-auth-authenticated.png" alt="Electron app showing the Azure profile signed in as okko.azure.user@******* with tenant 1f4cc68e-****-****-****-************, with the fabric profile still 'not signed in'. The sign-in button has been replaced by just the status text." />
<em>Stage 2 complete: Profile A authenticated, UI shows masked identity claims, and token material stays behind the main-process boundary.</em></p>

<hr />

<h3 id="session-persistence">Session Persistence</h3>

<p>The first Azure implementation was deliberately strict: keep token material in memory only and make every app restart require a fresh interactive sign-in. That was clean from a security-model standpoint, but unpleasant in daily use. A desktop app that forgets its identity every time it restarts feels broken, especially when MFA or Conditional Access is involved.</p>

<p><strong>What I tried:</strong> keep the renderer boundary unchanged, but persist the MSAL cache per profile using Electron’s <code class="language-plaintext highlighter-rouge">safeStorage</code>. MSAL Node exposes an <code class="language-plaintext highlighter-rouge">ICachePlugin</code> with two hooks: <code class="language-plaintext highlighter-rouge">beforeCacheAccess</code> reads <code class="language-plaintext highlighter-rouge">&lt;userData&gt;/auth-cache-azure.bin</code>, decrypts it with <code class="language-plaintext highlighter-rouge">safeStorage.decryptString</code>, and deserializes it into MSAL; <code class="language-plaintext highlighter-rouge">afterCacheAccess</code> serializes the updated cache, encrypts it with <code class="language-plaintext highlighter-rouge">safeStorage.encryptString</code>, writes to a temporary file, and renames it into place. On launch, the main process calls <code class="language-plaintext highlighter-rouge">restoreAzureProfile()</code> before opening the window; if MSAL can perform <code class="language-plaintext highlighter-rouge">acquireTokenSilent()</code> for a cached account, the UI starts already authenticated.</p>

<p><strong>What I observed:</strong></p>

<ol>
  <li>
    <p><strong>Memory-only tokens were clean but irritating.</strong> Restarting the app and signing in again every time made the MVP feel worse than the security model looked on paper.</p>
  </li>
  <li>
    <p><strong>MSAL’s cache plugin was the smallest useful change.</strong> I could keep the renderer boundary exactly the same and only teach main how to restore a profile before opening the window.</p>
  </li>
  <li>
    <p><strong><code class="language-plaintext highlighter-rouge">safeStorage</code> gave me the policy I wanted.</strong> Persist encrypted cache when OS protection exists; otherwise do not persist anything. No plaintext fallback.</p>
  </li>
  <li>
    <p><strong>I had to be honest about the word “cache”.</strong> MSAL serializes more than a naked refresh token. The right claim is OS-encrypted MSAL cache, not “only refresh tokens on disk”.</p>
  </li>
  <li>
    <p><strong>This does not solve a compromised user session.</strong> If malware runs as the same OS user, it may decrypt what the app can decrypt. That is not a problem I can fix with a clever local file format.</p>
  </li>
</ol>

<p>The compromise is practical: restarts restore sign-in without another browser prompt, while the renderer still never sees token material and copied cache files are not useful outside the same OS user context.</p>

<h3 id="fabric-profile-authentication">Fabric Profile Authentication</h3>

<p>A second, independent identity (Profile B) mirroring the Azure flow but targeting Microsoft Fabric (<code class="language-plaintext highlighter-rouge">https://api.fabric.microsoft.com/.default</code>). This is the stage that turns the app from single-auth into the dual-identity scenario at the heart of the MVP.</p>

<p><strong>What I tried:</strong> add a sibling pair <code class="language-plaintext highlighter-rouge">fabric-config.ts</code> + <code class="language-plaintext highlighter-rouge">fabric-profile.ts</code> next to the Azure equivalents, parameterising the existing <code class="language-plaintext highlighter-rouge">safeStorage</code>-backed cache plugin with a different <code class="language-plaintext highlighter-rouge">PROFILE_ID</code>. Two new IPC channels (<code class="language-plaintext highlighter-rouge">profile:fabric:sign-in</code>, <code class="language-plaintext highlighter-rouge">profile:fabric:sign-out</code>), one extra restore call in <code class="language-plaintext highlighter-rouge">main.ts</code>, one symmetric pair of React buttons. No shared “currently selected profile” indirection — two parallel UIs against two parallel modules.</p>

<p><strong>What I observed:</strong></p>

<ol>
  <li>
    <p><strong>The boring stage paid back the earlier discipline.</strong> The actual second profile was almost mechanical — two files copied with a handful of edits, no shared mutable state to untangle. The price of repeating two ~180-line modules is the lower price of zero accidental coupling: the <code class="language-plaintext highlighter-rouge">PublicClientApplication</code> instances, the in-memory <code class="language-plaintext highlighter-rouge">state</code>, and the <code class="language-plaintext highlighter-rouge">signInInProgress</code> flag are all file-local.</p>
  </li>
  <li>
    <p><strong>Specs drift if you don’t tend them.</strong> The original Fabric proposal said “no tokens or credentials are written to disk” — written before the token-persistence revision introduced the encrypted MSAL cache. I caught the contradiction during implementation and updated the change delta to “no plaintext tokens on disk; per-profile <code class="language-plaintext highlighter-rouge">auth-cache-fabric.bin</code> allowed, independent of the Azure cache file.” Archiving a change whose spec lies about its own behaviour is a future trap.</p>
  </li>
</ol>

<p><strong>A small code highlight</strong> — the only meaningful divergence from <code class="language-plaintext highlighter-rouge">azure-profile.ts</code> is the audience scope and the cache plugin’s <code class="language-plaintext highlighter-rouge">PROFILE_ID</code>:</p>

<div class="language-typescript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">// src/main/auth/fabric-config.ts</span>
<span class="nx">scope</span><span class="p">:</span> <span class="dl">"</span><span class="s2">https://api.fabric.microsoft.com/.default</span><span class="dl">"</span><span class="p">,</span>     <span class="c1">// (1) Fabric audience</span>

<span class="c1">// src/main/auth/fabric-profile.ts</span>
<span class="kd">const</span> <span class="nx">PROFILE_ID</span> <span class="o">=</span> <span class="dl">"</span><span class="s2">fabric</span><span class="dl">"</span><span class="p">;</span>                            <span class="c1">// (2) drives auth-cache-fabric.bin</span>
<span class="nx">pca</span> <span class="o">=</span> <span class="k">new</span> <span class="nx">PublicClientApplication</span><span class="p">({</span>
  <span class="na">auth</span><span class="p">:</span>  <span class="p">{</span> <span class="nx">clientId</span><span class="p">,</span> <span class="nx">authority</span> <span class="p">},</span>
  <span class="na">cache</span><span class="p">:</span> <span class="p">{</span> <span class="na">cachePlugin</span><span class="p">:</span> <span class="nx">createSafeStorageCachePlugin</span><span class="p">(</span><span class="nx">PROFILE_ID</span><span class="p">)</span> <span class="p">},</span>
<span class="p">});</span>
</code></pre></div></div>

<p>The IPC layer grew the symmetric shape you’d expect — two new channels, two new preload methods, two new React callbacks — all declared in one place:</p>

<div class="language-typescript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">export</span> <span class="kd">const</span> <span class="nx">IpcChannels</span> <span class="o">=</span> <span class="p">{</span>
  <span class="na">GetProfileStatus</span><span class="p">:</span> <span class="dl">"</span><span class="s2">profile:get-status</span><span class="dl">"</span><span class="p">,</span>
  <span class="na">AzureSignIn</span><span class="p">:</span>  <span class="dl">"</span><span class="s2">profile:azure:sign-in</span><span class="dl">"</span><span class="p">,</span>   <span class="na">AzureSignOut</span><span class="p">:</span>  <span class="dl">"</span><span class="s2">profile:azure:sign-out</span><span class="dl">"</span><span class="p">,</span>
  <span class="na">FabricSignIn</span><span class="p">:</span> <span class="dl">"</span><span class="s2">profile:fabric:sign-in</span><span class="dl">"</span><span class="p">,</span>  <span class="na">FabricSignOut</span><span class="p">:</span> <span class="dl">"</span><span class="s2">profile:fabric:sign-out</span><span class="dl">"</span><span class="p">,</span>
<span class="p">}</span> <span class="k">as</span> <span class="kd">const</span><span class="p">;</span>
</code></pre></div></div>

<p><strong>Verifying this stage:</strong> after <code class="language-plaintext highlighter-rouge">npm start</code>, both profiles sign in independently with different accounts. Two encrypted cache files on disk (<code class="language-plaintext highlighter-rouge">auth-cache-azure.bin</code> and <code class="language-plaintext highlighter-rouge">auth-cache-fabric.bin</code>), zero token material crossing IPC, audit reports <code class="language-plaintext highlighter-rouge">Channels declared: 5 · Preload bridges: 1 (api)</code>. That single screen — two profiles, two account UPNs, two <strong>Sign out</strong> buttons — is the success criterion for G1.</p>

<p><img src="/assets/images/2026-02-22-electron-multi-auth-mvp/stage3-fabruc-auth-auhtenticated.png" alt="Electron app showing both profiles authenticated side by side: azure as okko.azure.user@******* and fabric as okko.fabric.user@*******, each in tenant 1f4cc68e-****-****-****-************, with a Sign out button on each row. G1 success criterion — two simultaneous, independently revocable identities." /></p>

<hr />

<h3 id="sign-out">Sign Out</h3>

<p>Per-profile sign-out that clears one profile’s local token cache and in-memory state while leaving the other profile untouched. Browser/global Entra sign-out is a separate, explicit action: with a system-browser flow, clearing the browser-side session can affect other apps and should not be hidden inside a local profile sign-out.</p>

<p><strong>What I tried:</strong> add a <code class="language-plaintext highlighter-rouge">signOutAzure()</code> to the same module that owns the Azure profile state, exposed via a new IPC channel <code class="language-plaintext highlighter-rouge">profile:azure:sign-out</code>. The cleanup is two steps: walk MSAL’s in-memory token cache and <code class="language-plaintext highlighter-rouge">removeAccount</code> each entry, then <code class="language-plaintext highlighter-rouge">unlink</code> the encrypted on-disk cache file (<code class="language-plaintext highlighter-rouge">auth-cache-azure.bin</code>). The renderer button is just a state-driven swap — when authenticated, the <strong>Sign in to Azure</strong> button becomes <strong>Sign out</strong> on the same row.</p>

<p><strong>What I observed:</strong></p>

<ol>
  <li>
    <p><strong>There are two caches to clear.</strong> Deleting <code class="language-plaintext highlighter-rouge">auth-cache-azure.bin</code> is not enough if MSAL still has accounts in memory. The sign-out path has to clear MSAL first, then remove the file.</p>
  </li>
  <li>
    <p><strong>Local sign-out and browser sign-out are different features.</strong> I only want this app to forget the profile by default. Clearing the system browser’s Entra session could affect unrelated apps, so that needs to stay explicit.</p>
  </li>
  <li>
    <p><strong>The Fabric work is mostly a repeatable shape now.</strong> Once each profile owns its own module and cache file, preserving the other profile during sign-out becomes a design property rather than a special case.</p>
  </li>
</ol>

<p><strong>A small code highlight</strong> — the whole sign-out, including defensive ordering:</p>

<div class="language-typescript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">export</span> <span class="k">async</span> <span class="kd">function</span> <span class="nx">signOutAzure</span><span class="p">():</span> <span class="nb">Promise</span><span class="o">&lt;</span><span class="p">{</span> <span class="p">...</span> <span class="p">}</span><span class="o">&gt;</span> <span class="p">{</span>
  <span class="k">if</span> <span class="p">(</span><span class="nx">pca</span> <span class="o">!==</span> <span class="kc">null</span><span class="p">)</span> <span class="p">{</span>
    <span class="k">try</span> <span class="p">{</span>
      <span class="kd">const</span> <span class="nx">cache</span> <span class="o">=</span> <span class="nx">pca</span><span class="p">.</span><span class="nx">getTokenCache</span><span class="p">();</span>
      <span class="k">for</span> <span class="p">(</span><span class="kd">const</span> <span class="nx">account</span> <span class="k">of</span> <span class="k">await</span> <span class="nx">cache</span><span class="p">.</span><span class="nx">getAllAccounts</span><span class="p">())</span> <span class="p">{</span>
        <span class="k">await</span> <span class="nx">cache</span><span class="p">.</span><span class="nx">removeAccount</span><span class="p">(</span><span class="nx">account</span><span class="p">);</span>          <span class="c1">// (1) drop MSAL's in-memory copy</span>
      <span class="p">}</span>
    <span class="p">}</span> <span class="k">catch</span> <span class="p">{</span>
      <span class="c1">// fall through: still wipe the on-disk cache below</span>
    <span class="p">}</span>
  <span class="p">}</span>
  <span class="nx">state</span> <span class="o">=</span> <span class="nx">UNAUTHENTICATED</span><span class="p">;</span>                            <span class="c1">// (2) reset module-scope state</span>
  <span class="k">await</span> <span class="nx">deleteCacheFile</span><span class="p">(</span><span class="nx">PROFILE_ID</span><span class="p">).</span><span class="k">catch</span><span class="p">(()</span> <span class="o">=&gt;</span> <span class="kc">undefined</span><span class="p">);</span> <span class="c1">// (3) remove auth-cache-azure.bin</span>
  <span class="k">return</span> <span class="nx">getAzureProfileSnapshot</span><span class="p">();</span>
<span class="p">}</span>
</code></pre></div></div>

<p><strong>Verifying this stage:</strong></p>

<p>Three behavioural checks (Azure-only until the Fabric profile ships):</p>

<table>
  <thead>
    <tr>
      <th>#</th>
      <th>Check</th>
      <th>Expected outcome</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>1</td>
      <td>After signing in, click <strong>Sign out</strong></td>
      <td>UI flips to <code class="language-plaintext highlighter-rouge">azure: not signed in · Sign in to Azure</code></td>
    </tr>
    <tr>
      <td>2</td>
      <td><code class="language-plaintext highlighter-rouge">Test-Path "$env:APPDATA\electron-app-multi-login-test\auth-cache-azure.bin"</code></td>
      <td><code class="language-plaintext highlighter-rouge">False</code> — the encrypted cache file is gone</td>
    </tr>
    <tr>
      <td>3</td>
      <td>Click <strong>Sign in to Azure</strong> again</td>
      <td>Browser opens; sign-in completes; UI returns to the signed-in state</td>
    </tr>
  </tbody>
</table>

<hr />

<h2 id="reflections">Reflections</h2>

<h3 id="surprising-discoveries">Surprising Discoveries</h3>

<p>Nothing earth-shattering, but two small things stuck with me:</p>

<ul>
  <li><strong>The system browser flow shifts where isolation lives.</strong> Because sign-in happens in the OS browser, Electron’s session partitions are not the isolation boundary I needed to worry about — the app-owned MSAL caches and the IPC contract are. Less Electron-specific knowledge required than I expected going in.</li>
  <li><strong><code class="language-plaintext highlighter-rouge">safeStorage</code> is bound to the OS user, not just the file.</strong> On Windows it’s DPAPI behind the scenes, so the encrypted <code class="language-plaintext highlighter-rouge">auth-cache-*.bin</code> is useless if copied to another machine or even to another local account. That’s a nicer security property than I gave it credit for before reading the platform docs.</li>
</ul>

<h3 id="final-thoughts">Final Thoughts</h3>

<p>The MVP delivers a small, opinionated thing: one desktop app, two simultaneous Entra ID identities, each in its own MSAL client with its own encrypted cache, no tokens crossing into the renderer. That’s it. The auth part itself is almost free once you commit to MSAL Node and the system browser; the work that actually mattered was the boring orchestration — per-profile modules, typed IPC contracts, atomic cache writes, and a sign-out path that clears both the in-memory and on-disk copies.</p>

<p>The target audience is genuinely niche: consultants and support engineers who routinely operate on behalf of multiple customers with separate Entra ID accounts and want to hold those contexts side by side in a single tool instead of juggling browser profiles, incognito windows, or a second machine. That’s a small group — but for that group, the pattern is real, and now there’s a reference implementation that doesn’t pretend to be more than what it is. Customer is always right; even when the customer is a population of two.</p>

<hr />

<h2 id="references">References</h2>

<ul>
  <li><a href="https://learn.microsoft.com/en-us/entra/identity-platform/">Microsoft Identity Platform Documentation</a></li>
  <li><a href="https://www.electronjs.org/docs/latest/tutorial/security">Electron Security Best Practices</a></li>
  <li><a href="https://www.electronjs.org/docs/latest/api/safe-storage#platform-specific-key-providers">Electron <code class="language-plaintext highlighter-rouge">safeStorage</code> API — Platform-Specific Key Providers</a></li>
  <li><a href="https://learn.microsoft.com/en-us/windows/win32/api/dpapi/nf-dpapi-cryptprotectdata">Windows DPAPI — <code class="language-plaintext highlighter-rouge">CryptProtectData</code></a></li>
  <li><a href="https://learn.microsoft.com/en-us/javascript/api/@azure/msal-node/icacheplugin">MSAL Node — Token Cache Plugin (<code class="language-plaintext highlighter-rouge">ICachePlugin</code>)</a></li>
  <li><a href="https://learn.microsoft.com/en-us/javascript/api/@azure/identity/">Azure Identity SDK for Node.js</a></li>
  <li><a href="https://github.com/oulasvirta/electron-app-multi-login-test">Project Repository</a></li>
</ul>]]></content><author><name>Okko Oulasvirta</name></author><category term="labs" /><category term="electron" /><category term="azure" /><category term="authentication" /><category term="msal" /><category term="typescript" /><category term="mvp" /><summary type="html"><![CDATA[A hands-on development journal documenting my experience building an Electron app that supports dual Microsoft Entra ID authentication - one for Azure, one for Fabric - with strict profile isolation.]]></summary></entry><entry><title type="html">Fabric DevOps with Microsoft Terraform Provider - Part 1</title><link href="/devops/data/2024/10/22/fabric-devops-with-microsoft-terraform-provider-part-1.html" rel="alternate" type="text/html" title="Fabric DevOps with Microsoft Terraform Provider - Part 1" /><published>2024-10-22T00:00:00+00:00</published><updated>2024-10-22T00:00:00+00:00</updated><id>/devops/data/2024/10/22/fabric-devops-with-microsoft-terraform-provider-part-1</id><content type="html" xml:base="/devops/data/2024/10/22/fabric-devops-with-microsoft-terraform-provider-part-1.html"><![CDATA[<h2 id="introduction">Introduction</h2>

<p>Microsoft Fabric provides powerful analytics capabilities, but enterprises need reliable methods to deploy and manage resources across environments. Infrastructure as Code (IaC) has emerged as a DevOps best practice across cloud platforms, and the recently announced Microsoft Fabric Provider for Terraform extends this capability to Fabric resources.</p>

<blockquote>
  <p>‼️NOTE: Provider is still currently in experimental state and not recommended to production workloads. Latest version is release candidate <code class="language-plaintext highlighter-rouge">0.1.0-rc.1</code> as of 14.3.2024</p>
</blockquote>

<p>The Terraform provider introduces a declarative approach where entire Fabric workspaces and related resources can be defined, versioned, and deployed with complete consistency and auditability—critical requirements for enterprise governance and compliance.</p>

<p>This part 1 of evaluation concentrates first on capabilities of the Terraform provider using simple DEV &amp; TEST workspace architecture where DEV is configured with Git integration and Terraform state management is stored locally on developer machine.</p>

<p>For simplicity in all scenarios, Fabric workspaces already exist - they are not created with Terraform.</p>

<h2 id="prerequisites">Prerequisites</h2>

<ul>
  <li>Terraform tooling installed on development workstation.</li>
  <li>Existing Microsoft Fabric capacity (trial capacity is not supported).</li>
  <li>Existing Fabric workspaces for DEV and TEST environments.</li>
  <li>Fabric account with contributor access to the workspaces.</li>
</ul>

<h2 id="key-concepts">Key Concepts</h2>

<p><strong>Declarative Resource Management</strong> - Terraform allows you to define the desired state of your Fabric resources in <code class="language-plaintext highlighter-rouge">infrastructure-as-code</code> rather than writing procedural scripts to create them.</p>

<p><strong>State Management</strong> - Terraform tracks the real-world resources in its state file, allowing it to detect drift and make incremental changes.</p>

<p><strong>Dependency Management</strong> - Dependencies between Fabric resources are automatically managed by Terraform’s resource graph.</p>

<h2 id="setup-a-local-development-environment">Setup a Local Development Environment</h2>

<p>In this section, we’ll configure a local Terraform environment to manage Fabric resources across multiple workspaces. This setup enables consistent deployment patterns while maintaining environment isolation through Terraform workspaces.</p>

<p>We’ll focus on three key components:</p>
<ol>
  <li>Terraform workspace configuration for state management</li>
  <li>Fabric provider installation and authentication</li>
  <li>Environment-specific variable configuration for DEV and TEST</li>
</ol>

<p><img src="/assets/images/2024-10-20-fabric-devops-with-microsoft-terraform-provider-part-1/fabric-deployment-architecture-tf.excalidraw.png" alt="local-state-dev-test" /></p>

<h3 id="create-a-terraform-workspaces-for-dev-and-test-environments">Create a Terraform workspaces for DEV and TEST environments</h3>

<p>Create a new <code class="language-plaintext highlighter-rouge">Terraform workspace</code> for the DEV and TEST <code class="language-plaintext highlighter-rouge">Fabric workspace</code> deployments in different environment stages.</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">terraform</span><span class="w"> </span><span class="nx">workspace</span><span class="w"> </span><span class="nx">new</span><span class="w"> </span><span class="nx">dev</span><span class="w">
</span><span class="n">terraform</span><span class="w"> </span><span class="nx">workspace</span><span class="w"> </span><span class="nx">new</span><span class="w"> </span><span class="nx">test</span><span class="w">
</span></code></pre></div></div>

<p>This will create a <code class="language-plaintext highlighter-rouge">terraform.tfstate.d</code> directory with <code class="language-plaintext highlighter-rouge">dev</code> and <code class="language-plaintext highlighter-rouge">test</code> subdirectories for storing the Terraform state files. Use <code class="language-plaintext highlighter-rouge">terraform workspace list</code> to see the available workspaces and <code class="language-plaintext highlighter-rouge">terraform workspace show</code> to see the current workspace. First test deployments are going to be done against development workspace, so I’ll select the Terraform <code class="language-plaintext highlighter-rouge">dev</code> workspace as current state management context.</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">terraform</span><span class="w"> </span><span class="nx">workspace</span><span class="w"> </span><span class="nx">select</span><span class="w"> </span><span class="nx">dev</span><span class="w">
</span></code></pre></div></div>

<h3 id="install-terraform-fabric-provider">Install Terraform Fabric Provider</h3>

<p>Microsoft Fabric Terraform provider needs to be installed on the development workstation. Add the following Terraform provider configuration and run <code class="language-plaintext highlighter-rouge">terraform init</code> to download the provider plugin.</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="err">terraform</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">required_version</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="s2">"&gt;= 1.8.0"</span><span class="w">
    </span><span class="err">required_providers</span><span class="w"> </span><span class="p">{</span><span class="w">
        </span><span class="err">fabric</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="p">{</span><span class="w">
            </span><span class="err">source</span><span class="w">  </span><span class="err">=</span><span class="w"> </span><span class="s2">"microsoft/fabric"</span><span class="w">
            </span><span class="err">version</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="s2">"0.1.0-rc.1"</span><span class="w">
        </span><span class="p">}</span><span class="w">
    </span><span class="p">}</span><span class="w">
</span><span class="p">}</span><span class="w">

</span><span class="err">provider</span><span class="w"> </span><span class="s2">"fabric"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">use_cli</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="kc">true</span><span class="w"> </span><span class="err">#</span><span class="w"> </span><span class="err">Allow</span><span class="w"> </span><span class="err">Azure</span><span class="w"> </span><span class="err">CLI</span><span class="w"> </span><span class="err">to</span><span class="w"> </span><span class="err">be</span><span class="w"> </span><span class="err">used</span><span class="w"> </span><span class="err">for</span><span class="w"> </span><span class="err">authentication.</span><span class="w">
    </span><span class="err">preview</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="kc">true</span><span class="w"> </span><span class="err">#</span><span class="w">  </span><span class="err">Enable</span><span class="w"> </span><span class="err">preview</span><span class="w"> </span><span class="err">mode</span><span class="w"> </span><span class="err">to</span><span class="w"> </span><span class="err">use</span><span class="w"> </span><span class="err">preview</span><span class="w"> </span><span class="err">features.</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>
<p><em><code class="language-plaintext highlighter-rouge">providers.tf</code></em></p>

<p>Verify latest available version in <a href="https://registry.terraform.io/providers/microsoft/fabric/latest/docs">Microsoft Fabric Provider docs</a>.</p>

<h3 id="add-terraform-variables-and-values-for-dev-and-test-workspace-deployments">Add Terraform variables and values for DEV and TEST workspace deployments</h3>

<p>Define Terraform variables for the DEV workspace in a <code class="language-plaintext highlighter-rouge">variables.tf</code> file and set values for the variables to customize the deployment for the DEV <code class="language-plaintext highlighter-rouge">dev.tfvars</code> and TEST <code class="language-plaintext highlighter-rouge">test.tfvars</code> workspaces.</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="err">variable</span><span class="w"> </span><span class="s2">"workspace_id"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">description</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="s2">"An id (guid) for targeted workspace."</span><span class="w">
    </span><span class="err">type</span><span class="w">        </span><span class="err">=</span><span class="w"> </span><span class="err">string</span><span class="w">    
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>
<p><em><code class="language-plaintext highlighter-rouge">variables.tf</code></em></p>

<p>Workspace ID can be found in the Fabric portal URL.</p>

<p><img src="/assets/images/2024-10-20-fabric-devops-with-microsoft-terraform-provider-part-1/workspace-id-is-in-the-url.png" alt="workspace id can be found in the url" /></p>

<p>Values for the variables are set in the <code class="language-plaintext highlighter-rouge">variables.dev.tfvars</code> file.</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="err">#</span><span class="w"> </span><span class="err">The</span><span class="w"> </span><span class="err">DEV</span><span class="w"> </span><span class="err">Fabric</span><span class="w"> </span><span class="err">Workspace</span><span class="w"> </span><span class="err">ID</span><span class="w"> </span><span class="err">(guid</span><span class="w"> </span><span class="err">can</span><span class="w"> </span><span class="err">be</span><span class="w"> </span><span class="err">found</span><span class="w"> </span><span class="err">in</span><span class="w"> </span><span class="err">the</span><span class="w"> </span><span class="err">URL</span><span class="w"> </span><span class="err">of</span><span class="w"> </span><span class="err">the</span><span class="w"> </span><span class="err">workspace)</span><span class="w">
</span><span class="err">workspace_id</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="s2">"d03d9bfb-0a87-4646-9399-ceaccb437f53"</span><span class="w">
</span></code></pre></div></div>
<p><em><code class="language-plaintext highlighter-rouge">variables.dev.tfvars</code></em></p>

<p>and for the TEST workspace in the <code class="language-plaintext highlighter-rouge">variables.test.tfvars</code> file.</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="err">#</span><span class="w"> </span><span class="err">The</span><span class="w"> </span><span class="err">TEST</span><span class="w"> </span><span class="err">Fabric</span><span class="w"> </span><span class="err">Workspace</span><span class="w"> </span><span class="err">ID</span><span class="w"> </span><span class="err">(guid</span><span class="w"> </span><span class="err">can</span><span class="w"> </span><span class="err">be</span><span class="w"> </span><span class="err">found</span><span class="w"> </span><span class="err">in</span><span class="w"> </span><span class="err">the</span><span class="w"> </span><span class="err">URL</span><span class="w"> </span><span class="err">of</span><span class="w"> </span><span class="err">the</span><span class="w"> </span><span class="err">workspace)</span><span class="w">
</span><span class="err">workspace_id</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="s2">"2ac9716d-ce8d-4508-9b84-9eff009fbffa"</span><span class="w">
</span></code></pre></div></div>
<p><em><code class="language-plaintext highlighter-rouge">variables.test.tfvars</code></em></p>

<h2 id="-terraform-first-approach---deploy-fabric-items-to-dev-workspace-with-terraform">🧪 Terraform first approach - Deploy Fabric Items to DEV Workspace with Terraform</h2>

<p>In this scenario, we start by defining Fabric resources as Terraform templates first, then deploy them to create the actual resources in the DEV workspace. This approach follows the infrastructure-as-code principle where all resources are declared and versioned in code before they exist in the environment.</p>

<p>We’ll define and deploy multiple Fabric resource types, demonstrating how Terraform can manage various components of your Fabric workspace:</p>

<ol>
  <li>Define resource templates for each Fabric item type</li>
  <li>Apply the templates to create resources in the DEV workspace</li>
  <li>Verify the resources are created correctly</li>
</ol>

<p>Let’s walk through creating templates for each Fabric resource type and applying them to our DEV workspace.</p>

<h3 id="fabric-lakehouse---terraform-resource-template">Fabric Lakehouse - Terraform Resource Template</h3>

<p>To test deployment of non-existing Fabric item, create a new Terraform template file <code class="language-plaintext highlighter-rouge">lakehouse.tf</code> 
and add the following code to define a Fabric workspace and a lakehouse resource.</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="err">#</span><span class="w"> </span><span class="err">Terraform</span><span class="w"> </span><span class="err">template</span><span class="w"> </span><span class="err">for</span><span class="w"> </span><span class="err">Microsoft</span><span class="w"> </span><span class="err">Fabric</span><span class="w"> </span><span class="err">Lakehouse</span><span class="w">
</span><span class="err">resource</span><span class="w"> </span><span class="s2">"fabric_lakehouse"</span><span class="w"> </span><span class="s2">"lakehouse"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">display_name</span><span class="w">        </span><span class="err">=</span><span class="w"> </span><span class="s2">"lakehouse"</span><span class="w">
    </span><span class="err">description</span><span class="w">         </span><span class="err">=</span><span class="w"> </span><span class="s2">"Managed with Terraform template lakehouse.tf"</span><span class="w">
    </span><span class="err">workspace_id</span><span class="w">        </span><span class="err">=</span><span class="w"> </span><span class="err">var.workspace_id</span><span class="w">
</span><span class="p">}</span><span class="w">

</span><span class="err">#</span><span class="w"> </span><span class="err">Output</span><span class="w"> </span><span class="err">the</span><span class="w"> </span><span class="err">lakehouse</span><span class="w"> </span><span class="err">ID</span><span class="w"> </span><span class="err">for</span><span class="w"> </span><span class="err">use</span><span class="w"> </span><span class="err">by</span><span class="w"> </span><span class="err">other</span><span class="w"> </span><span class="err">resources</span><span class="w">
</span><span class="err">output</span><span class="w"> </span><span class="s2">"lakehouse_id"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">value</span><span class="w">       </span><span class="err">=</span><span class="w"> </span><span class="err">fabric_lakehouse.lakehouse.id</span><span class="w">
    </span><span class="err">description</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="s2">"The ID of the created Fabric lakehouse."</span><span class="w">
</span><span class="p">}</span><span class="w">

</span></code></pre></div></div>
<p><em><code class="language-plaintext highlighter-rouge">lakehouse.tf</code></em></p>

<p>Run <code class="language-plaintext highlighter-rouge">terraform plan	-var-file=variables.dev.tfvars</code> to see what changes Terraform will make to the DEV workspace.
It should report that it will create a new lakehouse resource.</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">terraform</span><span class="w"> </span><span class="nx">plan</span><span class="w"> </span><span class="nt">-compact-warnings</span><span class="w"> </span><span class="nt">-var-file</span><span class="o">=</span><span class="n">variables.dev.tfvars</span><span class="w">
</span></code></pre></div></div>

<p>Plan outputs <code class="language-plaintext highlighter-rouge">Plan: 1 to add, 0 to change, 0 to destroy.</code> as expected. The Lakehouse Fabric item doesn’t yet exist in the DEV workspace. 
Now creating it with <code class="language-plaintext highlighter-rouge">terraform apply</code> command.</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">terraform</span><span class="w"> </span><span class="nx">apply</span><span class="w"> </span><span class="nt">-var-file</span><span class="o">=</span><span class="s2">"variables.dev.tfvars"</span><span class="w"> </span><span class="nt">-auto-approve</span><span class="w"> </span><span class="nt">-no-color</span><span class="w"> </span><span class="nt">-out</span><span class="w"> </span><span class="s2">"dev.tfout"</span><span class="w">

</span><span class="n">fabric_lakehouse.lakehouse:</span><span class="w"> </span><span class="nx">Creating...</span><span class="w">
</span><span class="n">fabric_lakehouse.lakehouse:</span><span class="w"> </span><span class="nx">Still</span><span class="w"> </span><span class="nx">creating...</span><span class="w"> </span><span class="p">[</span><span class="mi">10</span><span class="n">s</span><span class="w"> </span><span class="nx">elapsed</span><span class="p">]</span><span class="w">
</span><span class="n">fabric_lakehouse.lakehouse</span><span class="p">:</span><span class="w"> </span><span class="n">Creation</span><span class="w"> </span><span class="n">complete</span><span class="w"> </span><span class="n">after</span><span class="w"> </span><span class="mi">36</span><span class="n">s</span><span class="w">

</span><span class="n">Apply</span><span class="w"> </span><span class="n">complete</span><span class="o">!</span><span class="w"> </span><span class="n">Resources</span><span class="p">:</span><span class="w"> </span><span class="mi">1</span><span class="w"> </span><span class="n">added</span><span class="p">,</span><span class="w"> </span><span class="mi">0</span><span class="w"> </span><span class="n">changed</span><span class="p">,</span><span class="w"> </span><span class="mi">0</span><span class="w"> </span><span class="n">destroyed.</span><span class="w">
</span></code></pre></div></div>

<h3 id="fabric-warehouse---terraform-resource-template">Fabric Warehouse - Terraform Resource Template</h3>

<p>Add a new Terraform template file <code class="language-plaintext highlighter-rouge">warehouse.tf</code> and add the following code to define a Fabric warehouse resource.</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="err">#</span><span class="w"> </span><span class="err">Terraform</span><span class="w"> </span><span class="err">template</span><span class="w"> </span><span class="err">for</span><span class="w"> </span><span class="err">Microsoft</span><span class="w"> </span><span class="err">Fabric</span><span class="w"> </span><span class="err">Warehouse</span><span class="w">
</span><span class="err">resource</span><span class="w"> </span><span class="s2">"fabric_warehouse"</span><span class="w"> </span><span class="s2">"warehouse"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">display_name</span><span class="w">        </span><span class="err">=</span><span class="w"> </span><span class="s2">"warehouse"</span><span class="w">
    </span><span class="err">description</span><span class="w">         </span><span class="err">=</span><span class="w"> </span><span class="s2">"Managed with Terraform template warehouse.tf"</span><span class="w">
    </span><span class="err">workspace_id</span><span class="w">        </span><span class="err">=</span><span class="w"> </span><span class="err">var.workspace_id</span><span class="w">
</span><span class="p">}</span><span class="w">

</span><span class="err">#</span><span class="w"> </span><span class="err">Output</span><span class="w"> </span><span class="err">the</span><span class="w"> </span><span class="err">warehouse</span><span class="w"> </span><span class="err">ID</span><span class="w"> </span><span class="err">for</span><span class="w"> </span><span class="err">use</span><span class="w"> </span><span class="err">by</span><span class="w"> </span><span class="err">other</span><span class="w"> </span><span class="err">resources</span><span class="w">
</span><span class="err">output</span><span class="w"> </span><span class="s2">"warehouse_id"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">value</span><span class="w">       </span><span class="err">=</span><span class="w"> </span><span class="err">fabric_warehouse.warehouse.id</span><span class="w">
    </span><span class="err">description</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="s2">"The ID of the created Fabric warehouse."</span><span class="w">
</span><span class="p">}</span><span class="w">

</span></code></pre></div></div>
<p><em><code class="language-plaintext highlighter-rouge">warehouse.tf</code></em></p>

<h3 id="fabric-data-pipeline---terraform-resource-template">Fabric Data Pipeline - Terraform Resource Template</h3>

<p>Add a new Terraform template file <code class="language-plaintext highlighter-rouge">data-pipeline.tf</code> and add the following code to define a Fabric data pipeline resource.</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="err">#</span><span class="w"> </span><span class="err">Terraform</span><span class="w"> </span><span class="err">template</span><span class="w"> </span><span class="err">for</span><span class="w"> </span><span class="err">Microsoft</span><span class="w"> </span><span class="err">Fabric</span><span class="w"> </span><span class="err">DataPipeline</span><span class="w">
</span><span class="err">resource</span><span class="w"> </span><span class="s2">"fabric_data_pipeline"</span><span class="w"> </span><span class="s2">"datapipeline"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">display_name</span><span class="w">        </span><span class="err">=</span><span class="w"> </span><span class="s2">"datapipeline"</span><span class="w">
    </span><span class="err">description</span><span class="w">         </span><span class="err">=</span><span class="w"> </span><span class="s2">"Managed with Terraform template data_pipeline.DataPipeline.tf."</span><span class="w">
    </span><span class="err">workspace_id</span><span class="w">        </span><span class="err">=</span><span class="w"> </span><span class="err">var.workspace_id</span><span class="w">
    </span><span class="err">format</span><span class="w">              </span><span class="err">=</span><span class="w"> </span><span class="s2">"Default"</span><span class="w">
</span><span class="p">}</span><span class="w">

</span><span class="err">#</span><span class="w"> </span><span class="err">Output</span><span class="w"> </span><span class="err">the</span><span class="w"> </span><span class="err">data</span><span class="w"> </span><span class="err">pipeline</span><span class="w"> </span><span class="err">ID</span><span class="w"> </span><span class="err">for</span><span class="w"> </span><span class="err">use</span><span class="w"> </span><span class="err">by</span><span class="w"> </span><span class="err">other</span><span class="w"> </span><span class="err">resources</span><span class="w">
</span><span class="err">output</span><span class="w"> </span><span class="s2">"datapipeline_id"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">value</span><span class="w">       </span><span class="err">=</span><span class="w"> </span><span class="err">fabric_data_pipeline.datapipeline.id</span><span class="w">
    </span><span class="err">description</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="s2">"The ID of the created Fabric data pipeline"</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>
<p><em><code class="language-plaintext highlighter-rouge">pipeline.tf</code></em></p>

<h3 id="fabric-notebook---terraform-resource-template">Fabric Notebook - Terraform Resource Template</h3>

<p>Add a new Terraform template file <code class="language-plaintext highlighter-rouge">notebook.tf</code> and add the following code to define a Fabric notebook resource. Notebooks are key components for data analysis and transformation in Fabric, providing a code-first interface for data professionals.</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="err">#</span><span class="w"> </span><span class="err">Terraform</span><span class="w"> </span><span class="err">template</span><span class="w"> </span><span class="err">for</span><span class="w"> </span><span class="err">Microsoft</span><span class="w"> </span><span class="err">Fabric</span><span class="w"> </span><span class="err">Notebook</span><span class="w">
</span><span class="err">resource</span><span class="w"> </span><span class="s2">"fabric_notebook"</span><span class="w"> </span><span class="s2">"notebook"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">display_name</span><span class="w">        </span><span class="err">=</span><span class="w"> </span><span class="s2">"notebook"</span><span class="w">
    </span><span class="err">description</span><span class="w">         </span><span class="err">=</span><span class="w"> </span><span class="s2">"Managed with Terraform template notebook.tf"</span><span class="w">
    </span><span class="err">workspace_id</span><span class="w">        </span><span class="err">=</span><span class="w"> </span><span class="err">var.workspace_id</span><span class="w">
</span><span class="p">}</span><span class="w">

</span><span class="err">#</span><span class="w"> </span><span class="err">Output</span><span class="w"> </span><span class="err">the</span><span class="w"> </span><span class="err">notebook</span><span class="w"> </span><span class="err">ID</span><span class="w"> </span><span class="err">for</span><span class="w"> </span><span class="err">use</span><span class="w"> </span><span class="err">by</span><span class="w"> </span><span class="err">other</span><span class="w"> </span><span class="err">resources</span><span class="w">
</span><span class="err">output</span><span class="w"> </span><span class="s2">"notebook_id"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">value</span><span class="w">       </span><span class="err">=</span><span class="w"> </span><span class="err">fabric_notebook.notebook.id</span><span class="w">
    </span><span class="err">description</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="s2">"The ID of the created Fabric notebook."</span><span class="w">
</span><span class="p">}</span><span class="w">

</span></code></pre></div></div>
<p><em><code class="language-plaintext highlighter-rouge">notebook.tf</code></em></p>

<h3 id="fabric-eventstream---terraform-resource-template">Fabric EventStream - Terraform Resource Template</h3>

<p>Create a new Terraform template file <code class="language-plaintext highlighter-rouge">eventstream.tf</code> to define a Fabric eventstream resource. EventStreams in Fabric enable real-time data ingestion and processing, ideal for scenarios requiring continuous data analysis.</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="err">#</span><span class="w"> </span><span class="err">Terraform</span><span class="w"> </span><span class="err">template</span><span class="w"> </span><span class="err">for</span><span class="w"> </span><span class="err">Microsoft</span><span class="w"> </span><span class="err">Fabric</span><span class="w"> </span><span class="err">EventStream</span><span class="w">
</span><span class="err">resource</span><span class="w"> </span><span class="s2">"fabric_eventstream"</span><span class="w"> </span><span class="s2">"eventstream"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">display_name</span><span class="w">        </span><span class="err">=</span><span class="w"> </span><span class="s2">"eventstream"</span><span class="w">
    </span><span class="err">description</span><span class="w">         </span><span class="err">=</span><span class="w"> </span><span class="s2">"Managed with Terraform template eventstream.tf"</span><span class="w">
    </span><span class="err">workspace_id</span><span class="w">        </span><span class="err">=</span><span class="w"> </span><span class="err">var.workspace_id</span><span class="w">
</span><span class="p">}</span><span class="w">

</span><span class="err">#</span><span class="w"> </span><span class="err">Output</span><span class="w"> </span><span class="err">the</span><span class="w"> </span><span class="err">eventstream</span><span class="w"> </span><span class="err">ID</span><span class="w"> </span><span class="err">for</span><span class="w"> </span><span class="err">use</span><span class="w"> </span><span class="err">by</span><span class="w"> </span><span class="err">other</span><span class="w"> </span><span class="err">resources</span><span class="w">
</span><span class="err">output</span><span class="w"> </span><span class="s2">"eventstream_id"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">value</span><span class="w">       </span><span class="err">=</span><span class="w"> </span><span class="err">fabric_eventstream.eventstream.id</span><span class="w">
    </span><span class="err">description</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="s2">"The ID of the created Fabric eventstream."</span><span class="w">
</span><span class="p">}</span><span class="w">

</span></code></pre></div></div>
<p><em><code class="language-plaintext highlighter-rouge">eventstream.tf</code></em></p>

<h3 id="fabric-eventhouse---terraform-resource-template">Fabric EventHouse - Terraform Resource Template</h3>

<p>Create a new Terraform template file <code class="language-plaintext highlighter-rouge">eventhouse.tf</code> to manage an eventhouse resource with Terraform. EventHouses provide storage and querying capabilities for event data captured by eventstreams.</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="err">#</span><span class="w"> </span><span class="err">Terraform</span><span class="w"> </span><span class="err">template</span><span class="w"> </span><span class="err">for</span><span class="w"> </span><span class="err">Microsoft</span><span class="w"> </span><span class="err">Fabric</span><span class="w"> </span><span class="err">EventHouse</span><span class="w">
</span><span class="err">resource</span><span class="w"> </span><span class="s2">"fabric_eventhouse"</span><span class="w"> </span><span class="s2">"eventhouse"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">display_name</span><span class="w">        </span><span class="err">=</span><span class="w"> </span><span class="s2">"eventhouse"</span><span class="w">
    </span><span class="err">description</span><span class="w">         </span><span class="err">=</span><span class="w"> </span><span class="s2">"Managed with Terraform template eventhouse.tf"</span><span class="w">
    </span><span class="err">workspace_id</span><span class="w">        </span><span class="err">=</span><span class="w"> </span><span class="err">var.workspace_id</span><span class="w">
</span><span class="p">}</span><span class="w">

</span><span class="err">#</span><span class="w"> </span><span class="err">Output</span><span class="w"> </span><span class="err">the</span><span class="w"> </span><span class="err">eventhouse</span><span class="w"> </span><span class="err">ID</span><span class="w"> </span><span class="err">for</span><span class="w"> </span><span class="err">use</span><span class="w"> </span><span class="err">by</span><span class="w"> </span><span class="err">other</span><span class="w"> </span><span class="err">resources</span><span class="w">
</span><span class="err">output</span><span class="w"> </span><span class="s2">"eventhouse_id"</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="err">value</span><span class="w">       </span><span class="err">=</span><span class="w"> </span><span class="err">fabric_eventhouse.eventhouse.id</span><span class="w">
    </span><span class="err">description</span><span class="w"> </span><span class="err">=</span><span class="w"> </span><span class="s2">"The ID of the created Fabric eventhouse."</span><span class="w">
</span><span class="p">}</span><span class="w">

</span></code></pre></div></div>
<p><em><code class="language-plaintext highlighter-rouge">eventhouse.tf</code></em></p>

<h2 id="-apply-terraform-templates-to-create-fabric-resources-in-dev-workspace">🚀 Apply Terraform Templates to Create Fabric Resources in DEV Workspace</h2>

<p>After defining the five new Terraform templates for Fabric resource types, we can now apply them to create the resources in the DEV workspace. Run the <code class="language-plaintext highlighter-rouge">terraform plan</code> command to see the changes Terraform will make to the DEV workspace.</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">terraform</span><span class="w"> </span><span class="nx">plan</span><span class="w"> </span><span class="nt">-var-file</span><span class="o">=</span><span class="n">variables.dev.tfvars</span><span class="w"> </span><span class="nt">-out</span><span class="w"> </span><span class="s2">"dev.tfplan"</span><span class="w">
</span><span class="o">.</span><span class="w">
</span><span class="n">Plan:</span><span class="w"> </span><span class="nx">5</span><span class="w"> </span><span class="nx">to</span><span class="w"> </span><span class="nx">add</span><span class="p">,</span><span class="w"> </span><span class="nx">0</span><span class="w"> </span><span class="nx">to</span><span class="w"> </span><span class="nx">change</span><span class="p">,</span><span class="w"> </span><span class="nx">0</span><span class="w"> </span><span class="nx">to</span><span class="w"> </span><span class="nx">destroy.</span><span class="w">

</span><span class="n">Changes</span><span class="w"> </span><span class="nx">to</span><span class="w"> </span><span class="nx">Outputs:</span><span class="w">
  </span><span class="n">~</span><span class="w"> </span><span class="nx">datapipeline_id</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="p">(</span><span class="n">known</span><span class="w"> </span><span class="nx">after</span><span class="w"> </span><span class="nx">apply</span><span class="p">)</span><span class="w">
  </span><span class="n">~</span><span class="w"> </span><span class="nx">eventhouse_id</span><span class="w">   </span><span class="o">=</span><span class="w"> </span><span class="p">(</span><span class="n">known</span><span class="w"> </span><span class="nx">after</span><span class="w"> </span><span class="nx">apply</span><span class="p">)</span><span class="w">
  </span><span class="n">~</span><span class="w"> </span><span class="nx">eventstream_id</span><span class="w">  </span><span class="o">=</span><span class="w"> </span><span class="p">(</span><span class="n">known</span><span class="w"> </span><span class="nx">after</span><span class="w"> </span><span class="nx">apply</span><span class="p">)</span><span class="w">
  </span><span class="n">~</span><span class="w"> </span><span class="nx">notebook_id</span><span class="w">     </span><span class="o">=</span><span class="w"> </span><span class="p">(</span><span class="n">known</span><span class="w"> </span><span class="nx">after</span><span class="w"> </span><span class="nx">apply</span><span class="p">)</span><span class="w">
  </span><span class="n">~</span><span class="w"> </span><span class="nx">warehouse_id</span><span class="w">    </span><span class="o">=</span><span class="w"> </span><span class="p">(</span><span class="n">known</span><span class="w"> </span><span class="nx">after</span><span class="w"> </span><span class="nx">apply</span><span class="p">)</span><span class="w">
</span></code></pre></div></div>

<p>The plan output shows that Terraform will create five new resources in the DEV workspace: data pipeline, eventhouse, eventstream, notebook, and warehouse. Also it states that outputs will be updated with the new resource IDs.</p>

<p>Now run the <code class="language-plaintext highlighter-rouge">terraform apply</code> command using the plan we created. This will ensure that the changes are applied as expected and with variable values from <code class="language-plaintext highlighter-rouge">variables.dev.tfvars</code> at the time of the plan creation.</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">terraform</span><span class="w"> </span><span class="nx">apply</span><span class="w"> </span><span class="s2">"dev.tfplan"</span><span class="w">
</span><span class="o">.</span><span class="w">
</span><span class="n">fabric_warehouse.warehouse:</span><span class="w"> </span><span class="nx">Creating...</span><span class="w">
</span><span class="n">fabric_data_pipeline.datapipeline:</span><span class="w"> </span><span class="nx">Creating...</span><span class="w">
</span><span class="n">fabric_eventstream.eventstream:</span><span class="w"> </span><span class="nx">Creating...</span><span class="w">
</span><span class="n">fabric_notebook.notebook:</span><span class="w"> </span><span class="nx">Creating...</span><span class="w">
</span><span class="n">fabric_eventhouse.eventhouse:</span><span class="w"> </span><span class="nx">Creating...</span><span class="w">
</span><span class="o">.</span><span class="w">
</span><span class="n">Apply</span><span class="w"> </span><span class="nx">complete</span><span class="o">!</span><span class="w"> </span><span class="nx">Resources:</span><span class="w"> </span><span class="nx">5</span><span class="w"> </span><span class="nx">added</span><span class="p">,</span><span class="w"> </span><span class="nx">0</span><span class="w"> </span><span class="nx">changed</span><span class="p">,</span><span class="w"> </span><span class="nx">0</span><span class="w"> </span><span class="nx">destroyed.</span><span class="w">
</span></code></pre></div></div>

<p>The apply command successfully created all <strong>five</strong> new Fabric resources in the DEV workspace. We can verify the resources in the Fabric portal to ensure they were created correctly.</p>

<p><img src="/assets/images/2024-10-20-fabric-devops-with-microsoft-terraform-provider-part-1/resources-created-succesfully.png" alt="fabric resources created in dev workspace" /></p>

<h2 id="-switch-terraform-workspace-context-to-test-and-deploy-resources">🚀 Switch Terraform workspace context to TEST and deploy Resources</h2>

<p>Now that we’ve successfully deployed Fabric resources to the DEV workspace, let’s switch the Terraform workspace context to TEST and deploy the same resources to the TEST workspace. This demonstrates how Terraform can manage resources across different environments using the same templates but with different parameter values.</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">terraform</span><span class="w"> </span><span class="nx">workspace</span><span class="w"> </span><span class="nx">select</span><span class="w"> </span><span class="nx">test</span><span class="w">
</span></code></pre></div></div>

<p>Run the <code class="language-plaintext highlighter-rouge">terraform plan</code> command to see the changes Terraform will make to the TEST workspace.</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">terraform</span><span class="w"> </span><span class="nx">plan</span><span class="w"> </span><span class="nt">-var-file</span><span class="o">=</span><span class="n">variables.test.tfvars</span><span class="w"> </span><span class="nt">-out</span><span class="w"> </span><span class="s2">"test.tfplan"</span><span class="w">
</span><span class="o">.</span><span class="w">
</span><span class="n">Plan:</span><span class="w"> </span><span class="nx">6</span><span class="w"> </span><span class="nx">to</span><span class="w"> </span><span class="nx">add</span><span class="p">,</span><span class="w"> </span><span class="nx">0</span><span class="w"> </span><span class="nx">to</span><span class="w"> </span><span class="nx">change</span><span class="p">,</span><span class="w"> </span><span class="nx">0</span><span class="w"> </span><span class="nx">to</span><span class="w"> </span><span class="nx">destroy.</span><span class="w">
</span></code></pre></div></div>

<p>The plan output shows that Terraform will create <strong>six</strong> new resources in the empty TEST workspace: lakehouse, data pipeline, eventhouse, eventstream, notebook, and warehouse. Run the <code class="language-plaintext highlighter-rouge">terraform apply</code> command using the plan we created to deploy the resources to the TEST workspace.</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">terraform</span><span class="w"> </span><span class="nx">apply</span><span class="w"> </span><span class="s2">"test.tfplan"</span><span class="w">
</span><span class="n">fabric_eventstream.eventstream:</span><span class="w"> </span><span class="nx">Creating...</span><span class="w">
</span><span class="n">fabric_notebook.notebook:</span><span class="w"> </span><span class="nx">Creating...</span><span class="w">
</span><span class="n">fabric_lakehouse.lakehouse:</span><span class="w"> </span><span class="nx">Creating...</span><span class="w">
</span><span class="n">fabric_data_pipeline.datapipeline:</span><span class="w"> </span><span class="nx">Creating...</span><span class="w">
</span><span class="n">fabric_warehouse.warehouse:</span><span class="w"> </span><span class="nx">Creating...</span><span class="w">
</span><span class="n">fabric_eventhouse.eventhouse:</span><span class="w"> </span><span class="nx">Creating...</span><span class="w">
</span><span class="o">.</span><span class="w">
</span><span class="n">Apply</span><span class="w"> </span><span class="nx">complete</span><span class="o">!</span><span class="w"> </span><span class="nx">Resources:</span><span class="w"> </span><span class="nx">6</span><span class="w"> </span><span class="nx">added</span><span class="p">,</span><span class="w"> </span><span class="nx">0</span><span class="w"> </span><span class="nx">changed</span><span class="p">,</span><span class="w"> </span><span class="nx">0</span><span class="w"> </span><span class="nx">destroyed.</span><span class="w">
</span></code></pre></div></div>

<p>Now we have identical Fabric resources deployed to both DEV and TEST workspaces using the same Terraform templates. This demonstrates how Terraform can manage resources consistently across different environments with environment-specific configurations.</p>

<p><img src="/assets/images/2024-10-20-fabric-devops-with-microsoft-terraform-provider-part-1/dev-and-test-workpsaces-are-identical.png" alt="fabric resources created in test workspace" /></p>

<h2 id="summary">Summary</h2>

<p>In this first part of our Fabric DevOps evaluation, we’ve successfully demonstrated how the Microsoft Fabric Terraform provider has potential to address some of the key enterprise DevOps requirements. We’ve evaluated how Terraform enables:</p>

<ul>
  <li>🟩 <strong>Environment isolation (EDR-01)</strong>: By using Terraform workspaces to manage state separately for DEV and TEST environments. NOTE: This is a simple local state management, not yet suitable for team collaboration.</li>
  <li>✅ <strong>Version control (EDR-03)</strong>: By defining Fabric resources as code in Terraform templates.</li>
  <li>✅ <strong>Automation (EDR-04)</strong>: By deploying multiple Fabric items consistently with parameterization</li>
  <li>✅ <strong>Cross-environment deployments</strong>: By deploying identical resource structures to both DEV and TEST environments while maintaining environment-specific configurations</li>
</ul>

<p>We’ve implemented and validated the “Terraform-first” approach for six different Fabric item types: <em>Lakehouse</em>, <em>Warehouse</em>, <em>Data Pipeline</em>, <em>Notebook</em>, <em>EventStream</em>, and <em>EventHouse</em>.</p>

<p>Our implementation demonstrated that the Terraform provider successfully handles resource creation across environments and provides a foundation for infrastructure-as-code practices with Fabric.</p>

<p>‼️ NOTE, we’ve only explored <strong>local state management</strong> so far, which presents challenges for team collaboration. In the next part, we’ll address this limitation by exploring the <strong>“Fabric-first” approach where existing Fabric items are imported into Terraform state</strong> and examine more advanced state management options including <em>remote backend configurations for shared state between multiple developers</em>.</p>

<h2 id="encountered-issues-and-workarounds">Encountered Issues and Workarounds</h2>

<p>Terraform is trying to use IPv6 to connect to the registry but encountering a “network is unreachable” error.</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">terraform</span><span class="w"> </span><span class="nx">init</span><span class="w">
</span><span class="n">Initializing</span><span class="w"> </span><span class="nx">the</span><span class="w"> </span><span class="nx">backend...</span><span class="w">
</span><span class="n">Initializing</span><span class="w"> </span><span class="nx">provider</span><span class="w"> </span><span class="nx">plugins...</span><span class="w">
</span><span class="o">-</span><span class="w"> </span><span class="n">Finding</span><span class="w"> </span><span class="nx">microsoft/fabric</span><span class="w"> </span><span class="nx">versions</span><span class="w"> </span><span class="nx">matching</span><span class="w"> </span><span class="s2">"0.1.0-rc.1"</span><span class="o">...</span><span class="w">
</span><span class="err">╷</span><span class="w">
</span><span class="err">│</span><span class="w"> </span><span class="n">Error:</span><span class="w"> </span><span class="nx">Failed</span><span class="w"> </span><span class="nx">to</span><span class="w"> </span><span class="nx">query</span><span class="w"> </span><span class="nx">available</span><span class="w"> </span><span class="nx">provider</span><span class="w"> </span><span class="nx">packages</span><span class="w">
</span><span class="err">│</span><span class="w"> 
</span><span class="err">│</span><span class="w"> </span><span class="n">Could</span><span class="w"> </span><span class="nx">not</span><span class="w"> </span><span class="nx">retrieve</span><span class="w"> </span><span class="nx">the</span><span class="w"> </span><span class="nx">list</span><span class="w"> </span><span class="nx">of</span><span class="w"> </span><span class="nx">available</span><span class="w"> </span><span class="nx">versions</span><span class="w"> </span><span class="nx">for</span><span class="w"> </span><span class="nx">provider</span><span class="w"> </span><span class="nx">microsoft/fabric:</span><span class="w"> </span><span class="nx">could</span><span class="w"> </span><span class="nx">not</span><span class="w"> </span><span class="nx">query</span><span class="w"> </span><span class="nx">provider</span><span class="w"> </span><span class="nx">registry</span><span class="w"> </span><span class="nx">for</span><span class="w">
</span><span class="err">│</span><span class="w"> </span><span class="n">registry.terraform.io/microsoft/fabric:</span><span class="w"> </span><span class="nx">the</span><span class="w"> </span><span class="nx">request</span><span class="w"> </span><span class="nx">failed</span><span class="w"> </span><span class="nx">after</span><span class="w"> </span><span class="nx">2</span><span class="w"> </span><span class="nx">attempts</span><span class="p">,</span><span class="w"> </span><span class="nx">please</span><span class="w"> </span><span class="nx">try</span><span class="w"> </span><span class="nx">again</span><span class="w"> </span><span class="nx">later:</span><span class="w"> </span><span class="nx">Get</span><span class="w">
</span><span class="err">│</span><span class="w"> </span><span class="s2">"https://registry.terraform.io/v1/providers/microsoft/fabric/versions"</span><span class="p">:</span><span class="w"> </span><span class="n">dial</span><span class="w"> </span><span class="nx">tcp</span><span class="w">
</span><span class="err">│</span><span class="w"> </span><span class="p">[</span><span class="mi">2600</span><span class="p">:</span><span class="mi">9000</span><span class="p">:</span><span class="mi">278</span><span class="n">f:c800:16:1aa3:1440:93a1</span><span class="p">]:</span><span class="mi">443</span><span class="p">:</span><span class="w"> </span><span class="n">connect</span><span class="p">:</span><span class="w"> </span><span class="n">network</span><span class="w"> </span><span class="n">is</span><span class="w"> </span><span class="n">unreachable</span><span class="w">
</span><span class="err">│</span><span class="w"> 
</span><span class="err">│</span><span class="w"> </span><span class="n">To</span><span class="w"> </span><span class="n">see</span><span class="w"> </span><span class="n">which</span><span class="w"> </span><span class="n">modules</span><span class="w"> </span><span class="n">are</span><span class="w"> </span><span class="n">currently</span><span class="w"> </span><span class="n">depending</span><span class="w"> </span><span class="n">on</span><span class="w"> </span><span class="n">microsoft/fabric</span><span class="w"> </span><span class="nx">and</span><span class="w"> </span><span class="nx">what</span><span class="w"> </span><span class="nx">versions</span><span class="w"> </span><span class="nx">are</span><span class="w"> </span><span class="nx">specified</span><span class="p">,</span><span class="w"> </span><span class="nx">run</span><span class="w"> </span><span class="nx">the</span><span class="w"> </span><span class="nx">following</span><span class="w"> </span><span class="nx">command:</span><span class="w">
</span><span class="err">│</span><span class="w">     </span><span class="n">terraform</span><span class="w"> </span><span class="n">providers</span><span class="w">
</span></code></pre></div></div>

<p>Workaround is to enforce <code class="language-plaintext highlighter-rouge">go</code> (used by Terraform) to use IPv4 for DNS resolution:</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">$</span><span class="nn">env</span><span class="p">:</span><span class="nv">GODEBUG</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="s2">"netdns=go+4"</span><span class="w">
</span><span class="n">terraform</span><span class="w"> </span><span class="nx">init</span><span class="w">
</span></code></pre></div></div>]]></content><author><name>Okko Oulasvirta</name></author><category term="devops" /><category term="data" /><category term="fabric" /><category term="devops" /><category term="terraform" /><summary type="html"><![CDATA[In part 1 we kick tires of Fabric Terraform provider and see how Fabric items can be declared as Terraform resources and deployed to different Fabric workspaces using same template but different parametrization.]]></summary></entry><entry><title type="html">The Enterprise Fabric Challenge: DevOps for Microsoft Fabric</title><link href="/data/2024/10/15/the-enterprise-fabric-challenge-devops-for-microsoft-fabric.html" rel="alternate" type="text/html" title="The Enterprise Fabric Challenge: DevOps for Microsoft Fabric" /><published>2024-10-15T00:00:00+00:00</published><updated>2024-10-15T00:00:00+00:00</updated><id>/data/2024/10/15/the-enterprise-fabric-challenge-devops-for-microsoft-fabric</id><content type="html" xml:base="/data/2024/10/15/the-enterprise-fabric-challenge-devops-for-microsoft-fabric.html"><![CDATA[<h2 id="introduction">Introduction</h2>

<p>Microsoft Fabric represents a significant leap forward in unified data analytics platforms, bringing together data engineering, data science, and business intelligence into a cohesive experience.</p>

<p>However, as organizations adopt Fabric for enterprise-scale implementations, they quickly encounter a familiar challenge.</p>

<blockquote>
  <p>How to implement robust DevOps practices for this new platform. While Fabric excels at enabling data professionals to create powerful analytics solutions, the platform is still evolving its enterprise-grade deployment and lifecycle management capabilities.</p>
</blockquote>

<p>In this blog series, we’ll explore the challenges and solutions for implementing effective DevOps practices with Microsoft Fabric in enterprise environments. This first post identifies the key challenges that organizations face when trying to manage Fabric items across development, testing, and production environments. By understanding these challenges, we can better appreciate the various Solutions we’ll examine in subsequent posts.</p>

<h2 id="fabric-items-and-devops">Fabric Items and DevOps</h2>

<p>Microsoft Fabric encompasses various item types or <strong>Fabric items</strong>, each with unique characteristics that impact how they’re managed in a DevOps pipeline:</p>

<ul>
  <li><strong>Notebooks</strong>: Code-based items that combine code, visualizations, and narrative text.</li>
  <li><strong>Dataflows</strong>: Visual or code-based data transformation definitions.</li>
  <li><strong>Semantic Models</strong>: Metadata structures that define business metrics and relationships.</li>
  <li><strong>Pipelines</strong>: Orchestration workflows that define dependencies and execution order.</li>
  <li><strong>Lakehouses</strong>: Data storage and organization structures.</li>
  <li><strong>Warehouses</strong>: Data storage and organization structures.</li>
  <li><strong>Other specialized items</strong>: Reports, dashboards, ML models, etc.</li>
</ul>

<p>Each of these items has different serialization formats, dependencies, and parameterization requirements, making a unified DevOps solution challenging.</p>

<h2 id="enterprise-devops-requirements">Enterprise DevOps Requirements</h2>

<p>Enterprise DevOps for Fabric must address several core requirements. Let’s outline some of the key expectations and use them as a lens to evaluate potential solutions in the subsequent posts.</p>

<h3 id="edr-01---environment-isolation">EDR-01 - Environment isolation</h3>

<p>Strict separation between <em>development</em>, <em>testing</em>, and <em>production</em>.</p>

<h3 id="edr-02---promotion-workflow">EDR-02 - Promotion workflow</h3>

<p>Controlled processes for moving items through environments.</p>

<h3 id="edr-03---version-control">EDR-03 - Version control</h3>

<p>Tracking and reviewing changes.</p>

<h3 id="edr-04---automation">EDR-04 - Automation</h3>

<p>Minimizing manual steps to reduce errors and increase efficiency.</p>

<h3 id="edr-05---governance">EDR-05 - Governance</h3>

<p>Ensuring compliance with organizational policies.</p>

<h3 id="edr-06---collaboration">EDR-06 - Collaboration</h3>

<p>Enabling teams to work together without conflicts.</p>

<p><img src="/assets/images/2024-10-15-fabric-devops-workspaces.png" alt="Fabric DevOps Workspaces" /></p>

<h2 id="fabric-item-deployment-requirements">Fabric Item Deployment Requirements</h2>

<p>Fabric provides Git integration to store Fabric item configurations to version control but different item types have different serialization formats and granularity. For example, notebooks are relatively straightforward to version control, while warehouse may have complex dependency structures that can be challenging to track.</p>

<ul>
  <li>
    <p>Fabric items often have interdependencies (e.g., a notebook or data pipeline have lakehouse references). Ensuring these dependencies are targeting to correct environment during deployment is critical. However, unfortunatelly currently not automatically managed by Fabric.</p>
  </li>
  <li>
    <p>Many Fabric items contain hardcoded references to data sources, schemas, or other environment-specific elements. Parameterizing these references for multi-environment deployment is complex.</p>
  </li>
</ul>

<p>Below is a list of <em>Fabric Item Deployment Requirements</em> we wanto to test for each solution and Fabric item type.</p>

<h3 id="fidr-dp---data-pipeline-deployment">FIDR-DP - Data Pipeline Deployment</h3>

<ul>
  <li><strong>Version control</strong>: Ability to track changes to data pipelines over time.</li>
  <li><strong>Dependency management</strong>: Handling dependencies between data pipelines and other Fabric items.</li>
  <li><strong>Parameterization</strong>: Ability to set environment-specific parameters.</li>
  <li><strong>Deployment of Data Pipeline resources</strong>: Deploying data pipelines to different environments.</li>
  <li><strong>Deployment of Data Pipeline content</strong>: Deploying data pipeline content.</li>
</ul>

<h3 id="fidr-df---dataflow-deployment">FIDR-DF - Dataflow Deployment</h3>

<ul>
  <li><strong>Version control</strong>: Ability to track changes to dataflows over time.</li>
  <li><strong>Dependency management</strong>: Handling dependencies between dataflows and other Fabric items.</li>
  <li><strong>Parameterization</strong>: Ability to set environment-specific parameters.</li>
  <li><strong>Deployment of Dataflow resources</strong>: Deploying dataflows to different environments.</li>
  <li><strong>Deployment of Dataflow content</strong>: Deploying dataflow content.</li>
</ul>

<h3 id="fidr-es---eventstream-deployment">FIDR-ES - Eventstream Deployment</h3>

<ul>
  <li><strong>Version control</strong>: Ability to track changes to eventstreams over time.</li>
  <li><strong>Dependency management</strong>: Handling dependencies between eventstreams and other Fabric items.</li>
  <li><strong>Parameterization</strong>: Ability to set environment-specific parameters.</li>
  <li><strong>Deployment of Eventstream resources</strong>: Deploying eventstreams to different environments.</li>
  <li><strong>Deployment of Eventstream content</strong>: Deploying eventstream content.</li>
</ul>

<h3 id="fidr-nb---notebook-deployment">FIDR-NB - Notebook Deployment</h3>

<ul>
  <li><strong>Version control</strong>: Ability to track changes to notebooks over time.</li>
  <li><strong>Parameterization</strong>: Ability to set environment-specific parameters.</li>
  <li><strong>Dependency management</strong>: Handling dependencies between notebooks and other Fabric items.</li>
  <li><strong>Deployment of Notebook resources</strong>: Deploying notebook to different environments.</li>
  <li><strong>Deployment of Notebook content</strong>: Deploying notebook content (code, visualizations, etc.).</li>
</ul>

<h3 id="fidr-eh---eventhouse-deployment">FIDR-EH - Eventhouse Deployment</h3>

<ul>
  <li><strong>Version control</strong>: Ability to track changes to eventhouses over time.</li>
  <li><strong>Dependency management</strong>: Handling dependencies between eventhouses and other Fabric items.</li>
  <li><strong>Parameterization</strong>: Ability to set environment-specific parameters.</li>
  <li><strong>Deployment of Eventhouse resources</strong>: Deploying eventhouses to different environments.</li>
  <li><strong>Deployment of Eventhouse schema</strong>: Deploying eventhouse schema.</li>
</ul>

<h3 id="fidr-lh---lakehouse-deployment">FIDR-LH - Lakehouse Deployment</h3>

<ul>
  <li><strong>Version control</strong>: Ability to track changes to lakehouses over time.</li>
  <li><strong>Dependency management</strong>: Handling dependencies between lakehouses and other Fabric items.</li>
  <li><strong>Parameterization</strong>: Ability to set environment-specific parameters.</li>
  <li><strong>Deployment of Lakehouse resources</strong>: Deploying lakehouses to different environments.</li>
  <li><strong>Deployment of Lakehouse schema</strong>: Deploying lakehouse schema.</li>
</ul>

<h3 id="fidr-wh---warehouse-deployment">FIDR-WH - Warehouse Deployment</h3>

<ul>
  <li><strong>Version control</strong>: Ability to track changes to warehouses over time.</li>
  <li><strong>Dependency management</strong>: Handling dependencies between warehouses and other Fabric items.</li>
  <li><strong>Parameterization</strong>: Ability to set environment-specific parameters.</li>
  <li><strong>Deployment of Warehouse resources</strong>: Deploying warehouses to different environments.</li>
  <li><strong>Deployment of Warehouse schema</strong>: Deploying warehouse schema.</li>
</ul>

<h2 id="fabric-identity-and-access-management-requirements">Fabric Identity and Access Management Requirements</h2>

<p>Enterprise environments require different access permissions in different environments, with production typically having the most restrictive controls. Automating these permission changes during promotion is challenging.</p>

<h3 id="fiamr-01---service-principal-authentication">FIAMR-01 - Service Principal Authentication</h3>

<p>Managing service principal authentication across environments.</p>

<h3 id="fiamr-02---access-control-automation">FIAMR-02 - Access Control Automation</h3>

<p>Managing role-based access control across environments programmatically.</p>

<h2 id="fabric-operational-requirements">Fabric Operational Requirements</h2>

<p>Validating that data pipelines work correctly with reduced test datasets while ensuring they will scale to production volumes is technically challenging.</p>

<p>Challenges with rollback strategies in case of failed deployments are also critical. Unlike traditional software where rollbacks can be relatively straightforward, data platform rollbacks may need to consider data changes that have already occurred.</p>

<h3 id="for-01---testing--validation">FOR-01 - Testing &amp; Validation</h3>

<p>Automated testing of Fabric items including data quality checks and performance validation.</p>

<h3 id="for-02---rollback-strategies">FOR-02 - Rollback Strategies</h3>

<p>Implementing safe rollback mechanisms for failed deployments.</p>

<h2 id="evaluating-potential-solutions">Evaluating Potential Solutions</h2>

<p>Now that we have requirements defined for our enterprise Fabric DevOps solution (and even cool new acronyms 🤣), we can evaluate potential solutions. In the next posts, I’ll review following tools as potential solutions for Enterprise scaled Fabric DevOps:</p>

<p><strong>Microsoft Terraform provider for Fabric</strong>: Managing Fabric resources declaratively using Infrastructure as Code (IaC) principles. This provider enables teams to define Fabric workspaces, capacities, and various Fabric items in code, facilitating repeatable deployments across environments. Terraform’s state management capabilities help track deployed resources and manage dependencies between them.</p>

<p>🧪 Validate <a href="/devops/data/2024/10/22/fabric-devops-with-microsoft-terraform-provider-part-1.html">Terraform first approach</a></p>
<ul>
  <li>Terraform Fabric resource templates are created first.</li>
  <li>Terraform resource templates are deployed to DEV workspace with Terraform <code class="language-plaintext highlighter-rouge">apply</code> command.</li>
  <li>Configuration changes are done to DEV workspace.</li>
  <li>Terraform <code class="language-plaintext highlighter-rouge">plan</code> command is executed to see what changes it can detect.</li>
</ul>

<p>🧪 Validate Create Fabric items first approach</p>
<ul>
  <li>Empty Fabric items are created in the DEV environment.</li>
  <li>Fabric items are added to Terraform state management using Terraform <code class="language-plaintext highlighter-rouge">import</code> command.</li>
  <li>Terraform resource templates are created and deployed to DEV.</li>
</ul>

<p>🧪 Validate Deploy resources to TEST workspace with Terraform</p>
<ul>
  <li>Create <code class="language-plaintext highlighter-rouge">Terraform workspaces</code> for DEV and TEST environments.</li>
  <li>Switch local Terraform state to use TEST workspace.</li>
  <li>Execute Terraform <code class="language-plaintext highlighter-rouge">apply</code> command to deploy resources to TEST workspace.</li>
  <li>Verify resources are deployed correctly in the TEST workspace.</li>
</ul>

<p><strong>Microsoft fabric-cicd: Python library for Fabric CI/CD</strong>: It is a code-first solution for deploying Microsoft Fabric items from a repository into a workspace. Its capabilities are intentionally simplified, with the primary goal of streamlining script-based deployments.</p>

<p><strong>Native Fabric DevOps Tools</strong>: Using Fabric’s built-in Git integration and Fabric deployment pipelines.</p>

<p><strong>Custom solutions</strong>: Above solutions probably have requirements that are not met without using custom scripting solutions that uses Fabric APIs, SDKs and Fabric CLI.</p>

<h2 id="references">References</h2>

<ul>
  <li>Microsoft <a href="https://registry.terraform.io/providers/microsoft/fabric/latest/docs">Terraform Fabric Provider</a></li>
  <li><a href="https://microsoft.github.io/fabric-cicd/latest/">fabric-cicd Python Library</a></li>
  <li><a href="https://blog.fabric.microsoft.com/en-us/blog/introducing-fabric-cicd-deployment-tool?ft=All">Fabric DevOps Blog Series</a></li>
  <li>Microsoft <a href="https://microsoft.github.io/fabric-cicd/latest/">fabric-cicd Python Library</a></li>
</ul>]]></content><author><name>Okko Oulasvirta</name></author><category term="data" /><category term="devops" /><category term="fabric" /><category term="terraform" /><summary type="html"><![CDATA[An introduction to the DevOps challenges in Microsoft Fabric for enterprise environments. This post explores common pain points when managing Fabric items across multiple environments and sets the stage for effective DevOps practices.]]></summary></entry><entry><title type="html">Deploy Spark Pool and Manage Packages in Synapse using Bicep - Part 1</title><link href="/data/azure/2024/05/01/deploy-spark-pool-packages-bicep-part-1.html" rel="alternate" type="text/html" title="Deploy Spark Pool and Manage Packages in Synapse using Bicep - Part 1" /><published>2024-05-01T00:00:00+00:00</published><updated>2024-05-01T00:00:00+00:00</updated><id>/data/azure/2024/05/01/deploy-spark-pool-packages-bicep-part-1</id><content type="html" xml:base="/data/azure/2024/05/01/deploy-spark-pool-packages-bicep-part-1.html"><![CDATA[<h1 id="part-1--deploy-synapse-apache-spark-pool-and-install-pypi-packages">Part 1- Deploy Synapse Apache Spark Pool and install PyPI packages</h1>

<p>Azure Synapse Analytics provides powerful Apache Spark pools for big data processing and machine learning workloads. While creating these resources manually through the Azure portal is straightforward, infrastructure as code (IaC) approaches like Bicep provide significant benefits for repeatability, version control, and automation.</p>

<blockquote>
  <p>🚀 In this post, I’ll walk through how to use Bicep to deploy a Spark pool to an existing Synapse workspace and manage its Python packages.</p>
</blockquote>

<h2 id="prerequisites">Prerequisites</h2>

<p>Before we begin, make sure you have:</p>

<ul>
  <li>An Azure subscription.</li>
  <li>An existing Azure Synapse Analytics workspace.</li>
  <li>Azure CLI installed with the latest version.</li>
  <li>Basic familiarity with Bicep templates.</li>
</ul>

<h2 id="synapse-spark-pools-package-management">Synapse Spark Pools Package Management</h2>

<p>Spark pools in Azure Synapse provide a serverless Spark environment for big data processing. Some key points to understand:</p>

<ul>
  <li>Spark pools are billed based on vCore-hours used.</li>
  <li>You need package from public registry which is not available on <a href="https://learn.microsoft.com/en-us/azure/synapse-analytics/spark/apache-spark-version-support">Azure Synapse Runtime for Apache Spark</a> default packages.</li>
  <li>They support various node sizes and auto-scaling configurations.</li>
  <li><em>Custom libraries</em> can be installed at the pool level or session level. The change of session-level libraries isn’t persisted between sessions.</li>
  <li>Library management is crucial for maintaining consistency across environments</li>
</ul>

<p>Libraries provide reusable code that you might want to include in your programs or projects for Apache Spark in Azure Synapse Analytics (Azure Synapse Spark).</p>

<p>You might need to update your serverless Apache Spark pool environment for various reasons. For example, you might find that:</p>

<ul>
  <li>One of your core dependencies released a new version.</li>
  <li>You need an extra package for training your machine learning model or preparing your data.</li>
  <li>A better package is available, and you no longer need the older package.</li>
  <li>Your team has built a custom Python <code class="language-plaintext highlighter-rouge">.whl</code> package that you need available in your Apache Spark pool.</li>
</ul>

<p>There are two primary ways to install a library on a Spark pool:</p>

<ol>
  <li>Install a workspace library that’s been uploaded as a workspace package.</li>
  <li>To update <strong>Python libraries</strong>, provide a <code class="language-plaintext highlighter-rouge">requirements.txt</code> or <strong>Conda</strong> <code class="language-plaintext highlighter-rouge">environment.yml</code> environment specification file to install packages from repositories like PyPI or Conda-Forge.</li>
</ol>

<p>Next I’ll show you how to manage Python libraries that your Sparkpool loads from PyPI using the <code class="language-plaintext highlighter-rouge">requirements.txt</code> and Bicep template.</p>

<h2 id="spark-pool-bicep-template">Spark Pool Bicep Template</h2>

<p>Below is a snippet from a Bicep template that deploys a Spark pool to an existing Synapse workspace and configures what PyPI libraries it will have available for developer (you can find the complete templates at the end of the post).</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">// For brevity, only the parameters relevant to library requirements are included.</span>
<span class="s">param workspaceName string</span>
<span class="s">param name string</span>
<span class="s">// library requirements - by default loads the content from requirements.txt in the same folder.</span>
<span class="s">param libraryRequirements object = {</span>
  <span class="s">filename</span><span class="err">:</span> <span class="s1">'</span><span class="s">requirements.txt'</span>
  <span class="na">content</span><span class="pi">:</span> <span class="s">loadTextContent('./requirements.txt')</span>
<span class="err">}</span>

<span class="s">// Existing parent workspace resource</span>
<span class="s">resource workspace 'Microsoft.Synapse/workspaces@2021-06-01' existing = {</span>
  <span class="s">name</span><span class="err">:</span> <span class="s">workspaceName</span>
<span class="err">}</span>

<span class="s">// Create Apache Spark Pool</span>
<span class="s">resource bigDataPool 'Microsoft.Synapse/workspaces/bigDataPools@2021-06-01' = {</span>
  <span class="s">name</span><span class="err">:</span> <span class="s">name</span>
  <span class="s">parent</span><span class="err">:</span> <span class="s">workspace</span>
  <span class="s">location</span><span class="err">:</span> <span class="s">resourceGroup().location</span>
  <span class="s">properties</span><span class="err">:</span> <span class="pi">{</span>
    <span class="nv">libraryRequirements</span><span class="pi">:</span> <span class="nv">libraryRequirements</span>
    <span class="nv">// Other required properties omitted for brevity</span>
  <span class="pi">}</span>
<span class="err">}</span>

</code></pre></div></div>

<p><em><code class="language-plaintext highlighter-rouge">modules/synapse/big-data-pools/main.bicep</code></em></p>

<p>This template creates a Spark pool with auto-scaling enabled and a few common Python libraries specified directly in the template.</p>

<h2 id="external-requirements-file">External Requirements File</h2>

<p>The bicep <em><code class="language-plaintext highlighter-rouge">modules/synapse/big-data-pools/main.bicep</code></em> module expects that the you provide the libraries reuirements as <code class="language-plaintext highlighter-rouge">requirements.txt</code> file in the same folder.</p>

<p>It has a parameter <code class="language-plaintext highlighter-rouge">libraryRequirements</code> to accept list of packages to be loaded and by default it will uses Bicep function <code class="language-plaintext highlighter-rouge">loadTextContent</code>to load requirements from the external file.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">param libraryRequirements object = {</span>
  <span class="s">filename</span><span class="err">:</span> <span class="s1">'</span><span class="s">requirements.txt'</span>
  <span class="na">content</span><span class="pi">:</span> <span class="s">loadTextContent('./requirements.txt')</span>
<span class="err">}</span>
</code></pre></div></div>

<p>The requirements file contains the libraries to be loaded in package/version key/value pairs for example:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">polars==1.23.0</span>
<span class="s">pandas==2.2.3</span>
<span class="s">snowflake-connector-python==3.14.0</span>
</code></pre></div></div>

<p>This approach keeps your Bicep template cleaner and makes it easier to manage library versions separately.</p>

<h2 id="deploying-the-template">Deploying the template</h2>

<p>Run in powershell session following <code class="language-plaintext highlighter-rouge">az cli</code> command in the same folder as the module template:</p>

<div class="language-powershell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">az</span><span class="w"> </span><span class="nx">deployment</span><span class="w"> </span><span class="nx">group</span><span class="w"> </span><span class="nx">create</span><span class="w"> </span><span class="se">`
</span><span class="w">  </span><span class="nt">-g</span><span class="w"> </span><span class="s2">"&lt;your existing resource group name&gt;"</span><span class="w"> </span><span class="se">`
</span><span class="w">  </span><span class="nt">-f</span><span class="w"> </span><span class="s2">"main.bicep"</span><span class="w"> </span><span class="se">`
</span><span class="w">  </span><span class="nt">--parameters</span><span class="w"> </span><span class="se">`
</span><span class="w">    </span><span class="s2">"synapseWorkspaceName=&lt;your existing workspace name&gt;"</span><span class="w"> </span><span class="se">`
</span><span class="w">    </span><span class="s2">"sparkPoolName=&lt;your spark pool name&gt;"</span><span class="w">
</span></code></pre></div></div>

<p>or with bash shell:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>az deployment group create <span class="se">\</span>
  <span class="nt">-g</span> <span class="s2">"&lt;your existing resource group name&gt;"</span> <span class="se">\</span>
  <span class="nt">-f</span> <span class="s2">"main.bicep"</span> <span class="se">\</span>
  <span class="nt">--parameters</span> <span class="se">\</span>
    <span class="s2">"synapseWorkspaceName=&lt;your existing workspace name&gt;"</span> <span class="se">\</span>
    <span class="s2">"sparkPoolName=&lt;your spark pool name&gt;"</span>
</code></pre></div></div>

<blockquote>
  <p>❗NOTE: When adding or removing PyPI packages the deployment might take a long time.
Deployment will trigger a system job to install/unstall and <em>cache</em> the specified libraries.
This process helps reduce overall session startup time.</p>
</blockquote>

<p>After deployment you should see in Azure Portal the <code class="language-plaintext highlighter-rouge">requirements.txt</code> file deployed in the Packages section of your Azure Spark Pool.</p>

<p><img src="/assets/images/2024-05-01-deploy-spark-pool-packages-bicep-part-1/azure-portal-spark-packages-requirements.png" alt="Azure Portal - packages section" /></p>

<h2 id="references">References</h2>

<ul>
  <li><a href="https://learn.microsoft.com/en-us/azure/synapse-analytics/quickstart-create-apache-spark-pool-portal">Create a new serverless Apache Spark pool using the Azure portal</a></li>
  <li><a href="https://learn.microsoft.com/en-us/azure/synapse-analytics/quickstart-create-apache-spark-pool-studio">Create a serverless Apache Spark pool using Synapse Studio</a></li>
  <li><a href="https://learn.microsoft.com/en-us/azure/synapse-analytics/spark/apache-spark-azure-portal-add-libraries">Manage libraries for Apache Spark in Azure Synapse Analytics</a></li>
  <li><a href="https://learn.microsoft.com/en-us/azure/synapse-analytics/spark/apache-spark-manage-pool-packages">Manage Sparkpool Packages</a></li>
  <li><a href="https://docs.microsoft.com/en-us/azure/azure-resource-manager/bicep/">Bicep documentation</a></li>
  <li><a href="https://docs.microsoft.com/en-us/rest/api/synapse/2021-06-01/big-data-pools">Synapse Spark pool REST API reference</a></li>
  <li><a href="https://spark.apache.org/docs/latest/">Apache Spark documentation</a></li>
</ul>

<h2 id="modulessynapsebig-data-poolsmainbicep">modules/synapse/big-data-pools/main.bicep</h2>

<p>This module deploys Azure Synapse Apache Sparkpool to an existing Azure Synapse Workspace. It assumes that there is a <code class="language-plaintext highlighter-rouge">requirements.txt</code> file in the same folder that contains all the PyPI libraries that needs to be installed to the pool.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">metadata name = 'Synapse Analytics Apache Spark Pools'</span>
<span class="s">metadata description = 'This module deploys an Apache Spark Pool for existing Azure Synapse Workspace.'</span>
<span class="s">metadata owner = 'cloud-center-of-excellence/bicep-module-owners'</span>

<span class="err">@</span><span class="s">description('Required. The name of the existing parent Synapse Workspace.')</span>
<span class="s">param workspaceName string</span>

<span class="s">// General</span>
<span class="err">@</span><span class="s">minLength(3)</span>
<span class="err">@</span><span class="s">maxLength(15)</span>
<span class="err">@</span><span class="s">description('Required. Name of the Azure Spark Pool. Valid characters</span><span class="err">:</span> <span class="s">Alphanumerics. Max length of 15 characters.')</span>
<span class="s">param name string</span>

<span class="err">@</span><span class="s">description('Optional. The geo-location where the resource lives.')</span>
<span class="s">param location string = resourceGroup().location</span>

<span class="err">@</span><span class="s">description('Optional. Tags of the resource.')</span>
<span class="s">param tags object = {}</span>

<span class="s">// AutoPauseProperties</span>
<span class="err">@</span><span class="s">description('Optional. Number of minutes of idle time before the Big Data pool is automatically paused.')</span>
<span class="s">param autoPauseDelayInMinutes int = </span><span class="m">15</span>
<span class="err">@</span><span class="s">description('Optional. Whether the Big Data pool is auto-paused.')</span>
<span class="s">param autoPauseEnabled bool = </span><span class="no">true</span>

<span class="s">// AutoScaleProperties</span>
<span class="err">@</span><span class="s">description('Optional. Whether the Big Data pool is auto-scaled.')</span>
<span class="s">param autoScaleEnabled bool = </span><span class="no">true</span>
<span class="err">@</span><span class="s">minValue(3)</span>
<span class="err">@</span><span class="s">maxValue(200)</span>
<span class="err">@</span><span class="s">description('Optional. The maximum number of nodes the Big Data pool can have.')</span>
<span class="s">param autoScaleMaxNodeCount int = </span><span class="m">3</span>
<span class="err">@</span><span class="s">minValue(3)</span>
<span class="err">@</span><span class="s">maxValue(200)</span>
<span class="err">@</span><span class="s">description('Optional. The minimum number of nodes the Big Data pool can have.')</span>
<span class="s">param autoScaleMinNodeCount int = </span><span class="m">3</span>

<span class="s">// CustomLibraries (custom .whl or .jar files)</span>
<span class="err">@</span><span class="s">description('Optional. List of custom libraries/packages associated with the spark pool.')</span>
<span class="s">param customLibraries array = []</span>

<span class="err">@</span><span class="s">description('Optional. The default folder where Spark logs will be written. Default value is "spark-logs".')</span>
<span class="s">param defaultSparkLogFolder string = 'spark-logs'</span>

<span class="err">@</span><span class="s">description('Optional. Whether autotune is enabled.')</span>
<span class="s">param isAutotuneEnabled bool = </span><span class="no">true</span>

<span class="err">@</span><span class="s">description('Optional. Whether compute isolation is enabled.')</span>
<span class="s">param isComputeIsolationEnabled bool = </span><span class="no">false</span>

<span class="err">@</span><span class="s">description('Optional. The library requirements. Default loads the content from requirements.txt file at the same folder as this module.')</span>
<span class="s">param libraryRequirements object = {</span>
  <span class="s">filename</span><span class="err">:</span> <span class="s1">'</span><span class="s">requirements.txt'</span>
  <span class="na">content</span><span class="pi">:</span> <span class="s">loadTextContent('./requirements.txt')</span>
<span class="err">}</span>

<span class="err">@</span><span class="s">minValue(3)</span>
<span class="err">@</span><span class="s">maxValue(200)</span>
<span class="err">@</span><span class="s">description('Optional. The number of nodes in the Big Data pool. Defaults to 3.')</span>
<span class="s">param nodeCount int = </span><span class="m">3</span>

<span class="err">@</span><span class="s">allowed([</span>
  <span class="s">'Large'</span>
  <span class="s">'Medium'</span>
  <span class="s">'None'</span>
  <span class="s">'Small'</span>
  <span class="s">'XLarge'</span>
  <span class="s">'XXLarge'</span>
  <span class="s">'XXXLarge'</span>
<span class="err">]</span><span class="s">)</span>
<span class="err">@</span><span class="s">description('Optional. The level of compute power that each node in the Big Data pool has.')</span>
<span class="s">param nodeSize string = 'Small'</span>

<span class="err">@</span><span class="s">allowed([</span>
  <span class="s">'HardwareAcceleratedFPGA'</span>
  <span class="s">'HardwareAcceleratedGPU'</span>
  <span class="s">'MemoryOptimized'</span>
<span class="err">]</span><span class="s">)</span>
<span class="err">@</span><span class="s">description('Optional. The kind of nodes that the Big Data pool provides.')</span>
<span class="s">param nodeSizeFamily string = 'MemoryOptimized'</span>

<span class="err">@</span><span class="s">description('Optional. Whether session level packages enabled.')</span>
<span class="s">param sessionLevelPackagesEnabled bool = </span><span class="no">true</span>

<span class="err">@</span><span class="s">description('Optional. Whether dynamic executor allocation is enabled.')</span>
<span class="s">param dynamicExecutorAllocationEnabled bool = </span><span class="no">true</span>
<span class="err">@</span><span class="s">description('Optional. The maximum number of executors the Big Data pool can have. This value must be less than the maximum number of autoScaleMaxNodeCount.')</span>
<span class="s">param dynamicExecutorAllocationMaxExecutors int = autoScaleMaxNodeCount - </span><span class="m">1</span>
<span class="err">@</span><span class="s">description('Optional. The minimum number of executors the Big Data pool can have.')</span>
<span class="s">param dynamicExecutorAllocationMinExecutors int = </span><span class="m">1</span>

<span class="s">// SparkConfigProperties</span>
<span class="err">@</span><span class="s">description('Optional. Spark configuration file to specify additional properties.')</span>
<span class="s">param sparkConfigProperties object = {}</span>

<span class="err">@</span><span class="s">description('Optional. The Spark events folder.')</span>
<span class="s">param sparkEventsFolder string = 'spark-events'</span>

<span class="err">@</span><span class="s">allowed([</span>
  <span class="s">'3.4'</span>
<span class="err">]</span><span class="s">)</span>
<span class="err">@</span><span class="s">description('Optional. The version of Spark. Default value is 3.4.')</span>
<span class="s">param sparkVersion string = '3.4'</span>

<span class="s">// Existing parent resource</span>
<span class="s">resource workspace 'Microsoft.Synapse/workspaces@2021-06-01' existing = {</span>
  <span class="s">name</span><span class="err">:</span> <span class="s">workspaceName</span>
<span class="err">}</span>

<span class="s">// Create Apache Spark Pool</span>
<span class="s">resource bigDataPool 'Microsoft.Synapse/workspaces/bigDataPools@2021-06-01' = {</span>
  <span class="s">name</span><span class="err">:</span> <span class="s">name</span>
  <span class="s">location</span><span class="err">:</span> <span class="s">location</span>
  <span class="s">tags</span><span class="err">:</span> <span class="s">tags</span>
  <span class="s">parent</span><span class="err">:</span> <span class="s">workspace</span>
  <span class="s">properties</span><span class="err">:</span> <span class="pi">{</span>
    <span class="nv">autoPause</span><span class="pi">:</span> <span class="pi">{</span>
      <span class="nv">delayInMinutes</span><span class="pi">:</span> <span class="nv">autoPauseDelayInMinutes</span>
      <span class="nv">enabled</span><span class="pi">:</span> <span class="nv">autoPauseEnabled</span>
    <span class="pi">}</span>
    <span class="nv">autoScale</span><span class="pi">:</span> <span class="pi">{</span>
      <span class="nv">enabled</span><span class="pi">:</span> <span class="nv">autoScaleEnabled</span>
      <span class="nv">maxNodeCount</span><span class="pi">:</span> <span class="nv">autoScaleMaxNodeCount</span>
      <span class="nv">minNodeCount</span><span class="pi">:</span> <span class="nv">autoScaleMinNodeCount</span>
    <span class="pi">}</span>
    <span class="nv">customLibraries</span><span class="pi">:</span> <span class="nv">customLibraries</span>
    <span class="nv">defaultSparkLogFolder</span><span class="pi">:</span> <span class="nv">defaultSparkLogFolder</span>
    <span class="nv">dynamicExecutorAllocation</span><span class="pi">:</span> <span class="pi">{</span>
      <span class="nv">enabled</span><span class="pi">:</span> <span class="nv">dynamicExecutorAllocationEnabled</span>
      <span class="nv">maxExecutors</span><span class="pi">:</span> <span class="nv">dynamicExecutorAllocationMaxExecutors</span>
      <span class="nv">minExecutors</span><span class="pi">:</span> <span class="nv">dynamicExecutorAllocationMinExecutors</span>
    <span class="pi">}</span>
    <span class="nv">isAutotuneEnabled</span><span class="pi">:</span> <span class="nv">isAutotuneEnabled</span>
    <span class="nv">isComputeIsolationEnabled</span><span class="pi">:</span> <span class="nv">isComputeIsolationEnabled</span>
    <span class="nv">libraryRequirements</span><span class="pi">:</span> <span class="nv">libraryRequirements</span>
    <span class="nv">nodeCount</span><span class="pi">:</span> <span class="nv">nodeCount</span>
    <span class="nv">nodeSize</span><span class="pi">:</span> <span class="nv">nodeSize</span>  
    <span class="nv">nodeSizeFamily</span><span class="pi">:</span> <span class="nv">nodeSizeFamily</span>
    <span class="nv">sessionLevelPackagesEnabled</span><span class="pi">:</span> <span class="nv">sessionLevelPackagesEnabled</span>
    <span class="nv">sparkConfigProperties</span><span class="pi">:</span> <span class="nv">sparkConfigProperties</span>
    <span class="nv">sparkEventsFolder</span><span class="pi">:</span> <span class="nv">sparkEventsFolder</span> 
    <span class="nv">sparkVersion</span><span class="pi">:</span> <span class="nv">sparkVersion</span>
  <span class="pi">}</span>
<span class="err">}</span>

<span class="s">output sparkPoolName string = bigDataPool.name</span>
<span class="s">output sparkPoolId string = bigDataPool.id</span>

</code></pre></div></div>

<p><em><code class="language-plaintext highlighter-rouge">modules/synapse/big-data-pools/main.bicep</code></em></p>]]></content><author><name>Okko Oulasvirta</name></author><category term="data" /><category term="azure" /><category term="azure synapse" /><category term="bicep" /><category term="iac" /><category term="spark" /><category term="pyspark" /><summary type="html"><![CDATA[Learn how to use Bicep to automate the deployment of Spark pools in Azure Synapse Analytics and manage pool packages to install Python libraries PyPi registry.]]></summary></entry><entry><title type="html">Testing how az app credential reset works</title><link href="/azure/2023/07/31/testing-ad-app-credential-secret-reset.html" rel="alternate" type="text/html" title="Testing how az app credential reset works" /><published>2023-07-31T00:00:00+00:00</published><updated>2023-07-31T00:00:00+00:00</updated><id>/azure/2023/07/31/testing-ad-app-credential-secret-reset</id><content type="html" xml:base="/azure/2023/07/31/testing-ad-app-credential-secret-reset.html"><![CDATA[<h1 id="understanding-and-testing-the-az-ad-app-credential-reset-command-in-azure-ad">Understanding and Testing the <code class="language-plaintext highlighter-rouge">az ad app credential reset</code> Command in Azure AD</h1>

<p>In application development and management, ensuring the security of your application is crucial. One such measure is routinely resetting the credentials for Azure Active Directory (AD) App Registrations. In this post, we’ll delve into the <code class="language-plaintext highlighter-rouge">az ad app credential reset</code> command, explore its options, and discuss some best practices regarding credential management.</p>

<h2 id="prerequisites">Prerequisites</h2>

<p>Before we dive in, make sure you have the following:</p>

<ul>
  <li>An active Azure account.</li>
  <li>Azure CLI installed on your machine or as an alternative you can use <a href="https://shell.azure.com/">Azure Cloud Shell</a>.</li>
  <li>At least one Azure AD App Registration for testing purposes.</li>
</ul>

<h2 id="process-overview">Process Overview</h2>

<p>We’ll be using the Azure CLI to navigate through our Azure resources. Our goal is to understand how the <a href="https://learn.microsoft.com/en-us/cli/azure/ad/app/credential?view=azure-cli-latest#az-ad-app-credential-reset">az ad app credential reset</a> command functions, explore its <code class="language-plaintext highlighter-rouge">--append</code> option, and differentiate between <strong>resetting a credential secret and a certificate</strong>.</p>

<h2 id="understanding-the-command">Understanding the Command</h2>

<p>The <code class="language-plaintext highlighter-rouge">az ad app credential reset</code> command resets the credentials of an Azure AD App Registration by creating a new password credential (Client Secret).</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>az ad app credential reset <span class="nt">--id</span> &lt;app-registration-client-id&gt;
</code></pre></div></div>

<h2 id="testing---append-switch">Testing <code class="language-plaintext highlighter-rouge">--append</code> switch</h2>

<p>The <code class="language-plaintext highlighter-rouge">--append</code> switch, when set, preserves old credentials, which can be useful when you’re rotating secrets and need to avoid downtime. When not set, the command removes all old credentials (Client secrets).</p>

<p><strong>With <code class="language-plaintext highlighter-rouge">--append</code> switch</strong></p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>az ad app credential reset <span class="nt">--id</span> &lt;app-registration-client-id&gt; <span class="nt">--append</span>
</code></pre></div></div>

<p>This command will preserve all existing credentials.</p>

<p><img src="/assets/images/2023-07-31-az-add-app-credential-reset-with-append.png" alt="reset secret with append" /></p>

<p><strong>Without <code class="language-plaintext highlighter-rouge">--append</code> switch</strong></p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>az ad app credential reset <span class="nt">--id</span> &lt;app-registration-client-id&gt;
</code></pre></div></div>

<p>This command will delete all existing password credentials (Client secrets) and creates a new one. However, it doesn’t remove Certificate credentials.</p>

<p>You can use <code class="language-plaintext highlighter-rouge">az ad app credential list --id &lt;app-registration-client-id&gt;</code> to verify the changes in both cases.</p>

<p><img src="/assets/images/2023-07-31-az-add-app-credential-reset-without-append.png" alt="reset secret with append" /></p>

<blockquote>
  <p>🚩 NOTE: you should store the secret value in a secure location. If you lose the secret, you’ll need to reset it again since Azure Portal doesn’t show the secret value later.</p>
</blockquote>

<h2 id="resetting-secret-vs-certificate">Resetting Secret vs. Certificate</h2>

<p>By default, the <code class="language-plaintext highlighter-rouge">az ad app credential reset</code> command creates a password credential. If you want to create a <strong>certificate credential</strong> instead, you can use the <code class="language-plaintext highlighter-rouge">--cert</code> and <code class="language-plaintext highlighter-rouge">--create-cert</code> options.</p>

<blockquote>
  <p>🚩 DANGER: running the command with <code class="language-plaintext highlighter-rouge">--create-cert</code> option even with <code class="language-plaintext highlighter-rouge">--append</code> option will <strong>delete all Client secrets</strong>.
<img src="/assets/images/2023-07-31-az-add-app-credential-reset-create-cert-deletes-all-client-secrets.png" alt="reset credential deletes all Client secrets" /></p>
</blockquote>

<p><strong>Let’s create a self-registered certificate credential with Azure Cloud Shell – note before running this ☝</strong></p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>az ad app credential reset <span class="nt">--id</span> &lt;app-registration-client-id&gt; <span class="nt">--create-cert</span>
</code></pre></div></div>

<p>This will create a self-signed certificate private key file with name similar to <code class="language-plaintext highlighter-rouge">tmp12321fa.pem</code>in your home directory and upload the public key to your Azure AD App Registration. Note that any existing Certificate and Client secret credentials will be deleted. If you run the same command many times, it will create a new certificate each time and it will replace the old one in Azure AD App Registration.</p>

<p>Use <code class="language-plaintext highlighter-rouge">az ad app credential list --id &lt;app-registration-client-id&gt; --cert</code> to verify the new certificate credential.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>az ad app credential reset <span class="nt">--id</span> &lt;app-registration-client-id&gt; <span class="nt">--create-cert</span> <span class="nt">--append</span>
</code></pre></div></div>

<p>This will create a new certificate credential and preserve the old one. However, <strong>it will delete all Client secret credentials</strong>.</p>

<h2 id="good-practices">Good Practices</h2>

<h3 id="one-secret-per-app-registration">One Secret per App Registration</h3>

<p>Having one secret per app registration is generally recommended for simplicity and ease of management. Especially we considering to implement fully automated secret reset solution. However, there are scenarios where multiple secrets might be needed, such as if the consuming application supports and uses secret rotation. In such cases, make sure each secret is properly tracked and managed.</p>

<h3 id="secret-rotation">Secret Rotation</h3>

<p>Regularly resetting app credentials is crucial for security. Define process for it and consider implementing an automation to rotate secrets and ensure that old secrets are invalidated.</p>

<h3 id="using-certificates">Using Certificates</h3>

<p>For higher security, consider using certificates instead of secrets. Certificates are more secure, harder to compromise, and can be managed more effectively in an enterprise environment.</p>

<h2 id="conclusion">Conclusion</h2>

<p>Understanding the <code class="language-plaintext highlighter-rouge">az ad app credential reset</code> command and its options helps in effectively managing Azure AD App Registrations. Regularly resetting these credentials is vital to maintaining the security of your Azure applications. Some of the command’s options, such as <code class="language-plaintext highlighter-rouge">--append</code>, can be useful in certain scenarios, but it’s important to understand how they work and their limitations. Also, they are even dangerous if used incorrectly.</p>

<ul>
  <li>Use <code class="language-plaintext highlighter-rouge">--append</code> switch to preserve old credentials when rotating Client secrets.</li>
  <li>If you are using both Client secrets and Certificates, you should consider separate storing them to two different app registrations or not use <code class="language-plaintext highlighter-rouge">az app credential reset</code> commands because the commmand will delete all Client secrets when creating a new certificate credential even with <code class="language-plaintext highlighter-rouge">--append</code> option.</li>
  <li>It is recommended to have one secret per app registration for simplicity and ease of management.</li>
  <li>Define process for secret rotation and consider implementing an automation to rotate secrets and ensure that old secrets are invalidated.
secret.</li>
</ul>

<h2 id="references">References</h2>

<ul>
  <li><a href="https://learn.microsoft.com/en-us/cli/azure/ad/app/credential?view=azure-cli-latest#az-ad-app-credential-reset">Azure CLI Documentation on reset app credentials</a></li>
</ul>]]></content><author><name>Okko Oulasvirta</name></author><category term="azure" /><category term="azure active directory" /><category term="entraid" /><summary type="html"><![CDATA[In application development and management, ensuring the security of your application is crucial. One such measure is routinely resetting the credentials for Azure Active Directory (AD) App Registrations. In this post, we'll delve into the az ad app credential reset command, explore its options, and discuss some best practices regarding credential management.]]></summary></entry><entry><title type="html">ChatGPT Reaches One Million: What is it?</title><link href="/azure/ai/2023/01/15/ChatGPT-Reaches-One-Million-What-is-it.html" rel="alternate" type="text/html" title="ChatGPT Reaches One Million: What is it?" /><published>2023-01-15T00:00:00+00:00</published><updated>2023-01-15T00:00:00+00:00</updated><id>/azure/ai/2023/01/15/ChatGPT-Reaches-One-Million-What-is-it</id><content type="html" xml:base="/azure/ai/2023/01/15/ChatGPT-Reaches-One-Million-What-is-it.html"><![CDATA[<h2 id="introduction">Introduction</h2>

<p>ChatGPT, OpenAI’s conversational AI model, has reached a milestone of <em>one million users</em> just days after its public launch. This extraordinary adoption rate signals a pivotal moment in artificial intelligence, as both consumers and businesses recognize the potential of this breakthrough technology.</p>

<p>The significance of this achievement extends far beyond mere user statistics. ChatGPT represents a fundamental shift in how we interact with AI systems, moving from rigid command-based interfaces to natural conversational exchanges. For enterprise decision-makers, this technology offers new possibilities for automating customer interactions, enhancing knowledge work, and transforming how employees interact with information systems.</p>

<h2 id="prerequisites-and-assumptions">Prerequisites and Assumptions</h2>

<p>Before diving deeper into ChatGPT’s implications, it’s helpful to understand:</p>

<ul>
  <li>Basic AI and machine learning concepts (neural networks, training data)</li>
  <li>The evolution of natural language processing (NLP) technologies</li>
  <li>The difference between narrow AI and more advanced language models</li>
</ul>

<p>No specific technical setup is required to understand this article, though accessing <a href="https://chat.openai.com/">ChatGPT</a> yourself can provide valuable first-hand experience with the technology.</p>

<h2 id="key-concepts">Key Concepts</h2>

<h3 id="what-is-chatgpt">What is ChatGPT?</h3>

<p>ChatGPT is a large language model (LLM) developed by OpenAI. It belongs to the GPT (Generative Pre-trained Transformer) family of models, specifically built on the GPT-3.5 architecture. At its core, ChatGPT is:</p>

<ul>
  <li>A deep learning model trained on vast amounts of text data from the internet up to 2021</li>
  <li>Designed specifically for conversational interactions</li>
  <li>Capable of understanding context across multiple exchanges</li>
  <li>Able to generate human-like responses to a wide range of queries</li>
</ul>

<h3 id="how-chatgpt-works">How ChatGPT Works</h3>

<p>ChatGPT operates on a foundation of transformer neural networks – an architecture that revolutionized natural language processing. The model:</p>

<ul>
  <li>Was pre-trained on diverse internet text to develop a broad understanding of language</li>
  <li>Was fine-tuned using Reinforcement Learning from Human Feedback (RLHF) to improve quality and safety</li>
  <li>Uses a technique called “attention” to weigh the importance of different words in understanding context</li>
  <li>Predicts the most likely continuation of a conversation based on patterns it learned during training</li>
</ul>

<h3 id="what-sets-chatgpt-apart">What Sets ChatGPT Apart?</h3>

<p>Unlike previous chatbots or virtual assistants, ChatGPT demonstrates:</p>

<ul>
  <li>Remarkable coherence across multiple conversation turns</li>
  <li>The ability to admit mistakes and reject inappropriate requests</li>
  <li>Creativity in generating content from poems to code</li>
  <li>Reasoning capabilities for problem-solving tasks</li>
</ul>

<h2 id="implications-for-enterprises">Implications for Enterprises</h2>

<p>The rapid adoption of ChatGPT hints at several important implications for businesses:</p>

<h3 id="customer-service-transformation">Customer Service Transformation</h3>

<p>ChatGPT-like technology could revolutionize customer interactions by:</p>

<ul>
  <li>Providing more natural, conversational support experiences</li>
  <li>Handling complex queries that traditional chatbots cannot</li>
  <li>Scaling support operations without proportional staff increases</li>
  <li>Maintaining consistent quality across all customer interactions</li>
</ul>

<h3 id="knowledge-worker-augmentation">Knowledge Worker Augmentation</h3>

<p>For internal operations, advanced language models offer:</p>

<ul>
  <li>Enhanced information retrieval from company documentation</li>
  <li>Assistance with content creation and editing</li>
  <li>Code generation and debugging support for developers</li>
  <li>Translation and summarization of complex documents</li>
</ul>

<h3 id="competitive-landscape-shifts">Competitive Landscape Shifts</h3>

<p>The release of ChatGPT signals:</p>

<ul>
  <li>AI capabilities that were once theoretical are now deployable</li>
  <li>Companies without AI strategies risk falling behind</li>
  <li>New opportunities for AI-native products and services</li>
  <li>A need for established businesses to reconsider their technology roadmaps</li>
</ul>

<h2 id="current-limitations">Current Limitations</h2>

<p>Despite its impressive capabilities, ChatGPT has important limitations enterprises should understand:</p>

<ul>
  <li><strong>Knowledge cutoff</strong>: ChatGPT’s training data only extends to 2021</li>
  <li><strong>Factual accuracy</strong>: The model can confidently present incorrect information</li>
  <li><strong>Reasoning limitations</strong>: Complex logical reasoning remains challenging</li>
  <li><strong>Bias concerns</strong>: The model may reflect biases present in its training data</li>
  <li><strong>Lack of integration</strong>: The current public version doesn’t connect to other systems</li>
  <li><strong>No customization</strong>: Enterprises cannot yet train the model on proprietary data</li>
</ul>

<h2 id="whats-next-for-chatgpt-and-enterprise-ai">What’s Next for ChatGPT and Enterprise AI</h2>

<p>While ChatGPT itself is a consumer-facing demonstration, the underlying technology is rapidly evolving toward enterprise applications:</p>

<ul>
  <li><strong>Azure OpenAI Service</strong>: Microsoft is bringing OpenAI’s technology to Azure with added security, compliance, and enterprise features</li>
  <li><strong>Domain-specific models</strong>: Future models will likely be fine-tuned for specific industries</li>
  <li><strong>Integration capabilities</strong>: API access will enable embedding these capabilities in existing enterprise systems</li>
  <li><strong>Reliability improvements</strong>: Work is ongoing to address hallucinations and factual accuracy</li>
  <li><strong>Multimodal capabilities</strong>: Future models will likely handle images, audio, and video alongside text</li>
</ul>

<h2 id="conclusion">Conclusion</h2>

<p>ChatGPT’s milestone of one million users in record time represents more than just a technological achievement—it signals a fundamental shift in AI accessibility and capability. This conversational AI demonstrates that advanced language understanding and generation is no longer confined to research labs but is ready for practical applications.</p>

<p>For enterprise leaders, ChatGPT offers a glimpse of the next wave of AI transformation. While the current public version has limitations, the technology is rapidly evolving toward enterprise readiness through platforms like Azure OpenAI Service. Organizations that begin exploring these capabilities now will be better positioned to leverage them strategically as they mature.</p>

<p>The conversation around AI is changing—from speculative discussions about future potential to practical considerations of immediate implementation. As an enterprise leader, the question is no longer if conversational AI will transform your industry, but how quickly you can adapt to the transformation already underway.</p>

<h2 id="known-and-resolved-issues">Known and Resolved Issues</h2>

<h3 id="known-issues">Known Issues</h3>
<ul>
  <li>ChatGPT occasionally produces confident-sounding but incorrect information</li>
  <li>The model has no built-in verification mechanism for factual accuracy</li>
  <li>Response quality can vary depending on how questions are phrased</li>
  <li>The model has no persistent memory beyond the current conversation</li>
  <li>Handling of complex, multi-step reasoning remains inconsistent</li>
</ul>

<h2 id="references">References</h2>

<ul>
  <li><a href="https://openai.com/blog/chatgpt/">OpenAI ChatGPT Official Page</a></li>
  <li><a href="https://azure.microsoft.com/en-us/products/cognitive-services/openai-service/">Microsoft Azure OpenAI Service</a></li>
  <li><a href="https://openai.com/blog/chatgpt/">Introducing ChatGPT - OpenAI Blog</a></li>
  <li><a href="https://arxiv.org/abs/2005.14165">GPT-3.5 Technical Report</a></li>
  <li><a href="https://arxiv.org/abs/2203.02155">Reinforcement Learning from Human Feedback</a></li>
</ul>]]></content><author><name>Okko Oulasvirta</name></author><category term="azure" /><category term="ai" /><category term="azure" /><category term="ai" /><category term="chatgpt" /><category term="openai" /><summary type="html"><![CDATA[OpenAI's ChatGPT has reached one million users in record time. This post explores what ChatGPT is, how it works, and what it means for enterprise AI adoption.]]></summary></entry><entry><title type="html">Create Azure API management API with Bicep and swagger file</title><link href="/azure/devops/2021/10/22/create-apim-api-bicep.html" rel="alternate" type="text/html" title="Create Azure API management API with Bicep and swagger file" /><published>2021-10-22T00:00:00+00:00</published><updated>2021-10-22T00:00:00+00:00</updated><id>/azure/devops/2021/10/22/create-apim-api-bicep</id><content type="html" xml:base="/azure/devops/2021/10/22/create-apim-api-bicep.html"><![CDATA[<p>This document describes how to use <a href="https://docs.microsoft.com/en-us/azure/azure-resource-manager/bicep/overview">Bicep</a> templates to import an Azure API Management <a href="https://docs.microsoft.com/en-us/azure/api-management/backends">Backend API</a> configurations using <a href="https://spec.openapis.org/">Open API specification</a> a.k.a <em>Swagger</em> file.</p>

<blockquote class="notice--primary">
  <p>Azure API Management (APIM) is used publish APIs to external, partner, and internal developers. APIM enables you to create and manage API gateways for existing backend services hosted anywhere. For more information, see the <a href="https://docs.microsoft.com/en-us/azure/api-management/api-management-key-concepts">Overview</a>.</p>

  <p>Backend API in APIM is a HTTP service that implements your front-end API and its operations. When importing certain APIs, APIM configures the Backend API automatically. For example, APIM configures the backend when importing:</p>

  <ul>
    <li>An OpenAPI specification.</li>
    <li>A SOAP API.</li>
    <li>Azure resources, such as an HTTP-triggered Azure Function App or Logic App.</li>
  </ul>
</blockquote>

<p>Bicep is a domain-specific language (DSL) that uses <em>declarative syntax</em> to <strong>deploy and configure Azure resources</strong>.</p>

<h2 id="review-the-template---serviceapisbicep">Review the template - service.apis.bicep</h2>

<p>This Bicep template imports and creates Backend API for existing Azure API management service. 
By default it expects that OAS spefication file comes in <code class="language-plaintext highlighter-rouge">yaml</code> format and uses
<a href="https://spec.openapis.org/oas/v3.0.0">OAS version 3.0.0</a> implementation.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="s">param apimServiceName string = replace(resourceGroup().name, 'rg-', 'apim-')</span>
<span class="s">// API name needs to unique in APIM</span>
<span class="s">param name string = 'petstore'</span>
<span class="err">@</span><span class="s">allowed([</span>
  <span class="s">'yaml-v3' //uses 'openapi-link' format</span>
  <span class="s">'json-v3' //uses 'openapi+json-link' format</span>
<span class="err">]</span><span class="s">)</span>
<span class="s">param swaggerType string = 'yaml-v3'</span>
<span class="s">// This url needs to be reachable for APIM</span>
<span class="s">param urlToSwagger string = 'https://raw.githubusercontent.com/OAI/OpenAPI-Specification/main/examples/v3.0/petstore.yaml'</span>
<span class="s">// There can be only one api without path</span>
<span class="s">param apiPath string = ''</span>
<span class="s">// param apiVersion string</span>

<span class="s">// Existing APIM service</span>
<span class="s">resource apimService 'Microsoft.ApiManagement/service@2021-01-01-preview' existing = {</span>
  <span class="s">name</span><span class="err">:</span> <span class="s">apimServiceName</span>
<span class="err">}</span>

<span class="s">var format = ((swaggerType == 'yaml-v3')  ? 'openapi-link'</span> <span class="err">:</span> <span class="s1">'</span><span class="s">openapi+json-link')</span>

<span class="s">resource api 'Microsoft.ApiManagement/service/apis@2020-06-01-preview' = {</span>
  <span class="s">name</span><span class="err">:</span> <span class="s1">'</span><span class="s">${apimService.name}/${name}'</span>
  <span class="na">properties</span><span class="pi">:</span> <span class="pi">{</span>
    <span class="nv">format</span><span class="pi">:</span> <span class="nv">format</span>
    <span class="nv">value</span><span class="pi">:</span> <span class="nv">urlToSwagger</span>
    <span class="nv">path</span><span class="pi">:</span> <span class="nv">apiPath</span>
    <span class="nv">// apiVersion</span><span class="pi">:</span> <span class="nv">apiVersion</span>
    <span class="nv">// apiVersionSetId</span><span class="pi">:</span> <span class="nv">apiVersionSet.id</span>
  <span class="pi">}</span>
<span class="err">}</span>

<span class="s">//output nameWithVersion string = nameWithVersion</span>
<span class="s">output name string = api.name</span>
<span class="s">output id string = api.id</span>

</code></pre></div></div>

<blockquote class="notice--info">
  <p>💡 TIP</p>

  <ul>
    <li>Contents of Open API specification file can be validated with <a href="https://editor.swagger.io/">Swagger Editor</a>.</li>
    <li>Open API specification V2 support is limited to JSON file format only.</li>
    <li>For OAS V2 use in Bicep <code class="language-plaintext highlighter-rouge">properties.format</code> property value <code class="language-plaintext highlighter-rouge">'swgger-link-json'</code>.</li>
    <li>The API import limitations are documented as <a href="https://docs.microsoft.com/en-us/azure/api-management/api-management-api-import-restrictions">known issues article</a>.</li>
  </ul>
</blockquote>

<h2 id="deploy-the-template-to-azure">Deploy the template to Azure</h2>

<p>To deploy Bicep template to Azure, you need to sign-in to your Azure account using <a href="https://docs.microsoft.com/en-us/cli/azure/what-is-azure-cli">Azure command line interface</a> (AZ CLI).</p>

<blockquote class="notice--warning">
  <p>🚩 NOTE</p>

  <p>Remember to sign in with your Azure AD account that has <em>Contributor</em> access role to your Azure API management environment.</p>
</blockquote>

<ol>
  <li>Open a Visual Studio Code terminal window by selecting <em>Terminal &gt; New Terminal</em>. The window usually opens at the bottom of the screen.}</li>
  <li>Switch your terminal to the directory where you saved <code class="language-plaintext highlighter-rouge">service.apis.bicep</code> Bicep template.</li>
</ol>

<h3 id="sign-in-to-azure-with-azure-cli">Sign in to Azure with Azure CLI</h3>

<p>In the Visual Studio Code terminal, sign in to Azure by running the following command:</p>

<p><code class="language-plaintext highlighter-rouge">az login</code></p>

<p>In the browser that opens, sign in to your Azure account.</p>

<p>The Visual Studio Code terminal displays a list of the subscriptions associated with this account.</p>

<p>Set the subscription context for all of the Azure CLI commands that you run in this session.</p>

<p><code class="language-plaintext highlighter-rouge">az account set --subscription "your-subscription-name"</code></p>

<h3 id="create-resource-group-with-azure-cli">Create resource group with Azure CLI</h3>

<p>Create a new <a href="https://docs.microsoft.com/en-us/azure/azure-resource-manager/management/manage-resource-groups-cli">Azure resource group</a> for your Azure development environment.</p>

<p><code class="language-plaintext highlighter-rouge">az group create --location westeurope --name "rg-yourgroup-we-dev"</code></p>

<h3 id="prerequisites-for-api-import">Prerequisites for API import</h3>

<p>You need existing <em>Azure API Management service instance</em>. Either complete MS docs quickstart <a href="https://docs.microsoft.com/en-us/azure/api-management/get-started-create-service-instance">Create an Azure API Management instance</a> or follow instructions of my previous APIM post <a href="/devops/2021/10/18/create-apim-service-bicep.html">Create APIM service instance with Bicep</a>.</p>

<h3 id="deploy-serviceapisbicep-template-to-azure">Deploy service.apis.bicep template to Azure</h3>

<p>Run the following command from the terminal in Visual Studio Code to deploy the Bicep template to Azure.</p>

<p><code class="language-plaintext highlighter-rouge">az deployment group create --template-file service.apis.bicep --resource-group "rg-yourgroup-we-dev" --name "apim-import-api-deploy"</code></p>

<p>Example above deploys template <code class="language-plaintext highlighter-rouge">service.apis.bicep</code> that creates a new <em>Frontend API</em> with name of <code class="language-plaintext highlighter-rouge">petstore</code> that maps to <em>Backend API</em>. Template uses <a href="https://raw.githubusercontent.com/OAI/OpenAPI-Specification/main/examples/v3.0/petstore.yaml">example OAS V3 yaml file for Petstore API</a> in GitHub as a default parameter.</p>

<h3 id="review-deployed-resources">Review deployed resources</h3>

<p>Use the Azure portal to check the deployed resources or use Azure CLI to <a href="https://docs.microsoft.com/en-us/cli/azure/apim/api?view=azure-cli-latest#az_apim_api_list">list the deployed APIM resources</a>.</p>

<p><strong>AZ-CLI</strong></p>

<p><code class="language-plaintext highlighter-rouge">az apim api list --resource-group "rg-yourgroup-we-dev" --service-name "apim-yourgroup-we-dev"</code></p>

<p><strong>Azure Portal</strong></p>

<ol>
  <li>In the <a href="https://portal.azure.com/">Azure portal</a>, search for and select <em>API Management</em> services, and select the service instance you created.</li>
  <li>
    <p>Review <em>petstore</em> API under APIs &gt; APIs page.</p>

    <p><img src="/assets/images/2021-10-22-create-apim-api-petstore-after-deployment.png" alt="Petstore API in Azure Portal" /></p>
  </li>
</ol>

<h2 id="see-also">See also</h2>

<ul>
  <li><a href="https://spec.openapis.org/">Open API specification</a>.</li>
  <li><a href="https://swagger.io/">Swagger.io</a>.</li>
  <li>MS product page: <a href="https://azure.microsoft.com/en-us/services/api-management/">API management</a>.</li>
  <li>Azure API management: <a href="https://azure.microsoft.com/en-us/pricing/details/api-management/">pricing</a></li>
  <li>MS docs tutorial: <a href="https://docs.microsoft.com/en-us/azure/api-management/import-and-publish">Import and publish your first API</a>.</li>
  <li>Azure CLI docs: <a href="https://docs.microsoft.com/en-us/cli/azure/deployment/group?view=azure-cli-latest#az_deployment_group_create">az deployment group create</a>.</li>
  <li>How to: <a href="https://docs.microsoft.com/en-us/cli/azure/install-azure-cli">install Azure CLI</a>.</li>
  <li>Bicep reference: <a href="https://docs.microsoft.com/en-us/azure/templates/microsoft.apimanagementservice?tabs=bicep">Microsoft.ApiManagement service</a>.</li>
</ul>]]></content><author><name>Okko Oulasvirta</name></author><category term="azure" /><category term="devops" /><category term="apim" /><category term="azure" /><category term="bicep" /><summary type="html"><![CDATA[This document describes how to use _Bicep_ templates to import an _Azure API Management_ **Backend API** configurations using _Open API specification_ a.k.a _Swagger_ file.]]></summary></entry></feed>